Mainframe to Cloud: A Practical Data Migration Playbook
💾 Did you know? An alarming 83% of data migrations fail outright or drastically overrun their budgets.
Shifting Mainframe Heavyweights to the Cloud
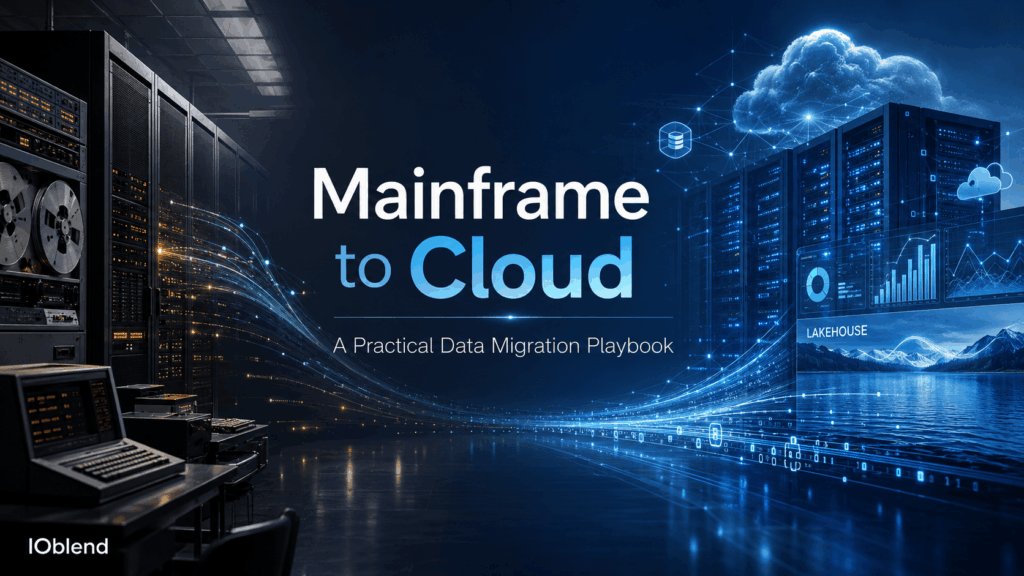
Mainframe-to-cloud data migration is the process of moving core legacy data assets, often stored in rigid formats like DB2, VSAM, or IMS, into modern cloud environments such as Databricks, Snowflake, or AWS. At its heart, this migration is not merely about moving storage bytes; it requires replicating complex, decades-old business logic and converting EBCDIC encodings into cloud-native formats without disrupting daily operational workflows.
The Friction Points of Legacy Architecture
When engineering a mainframe migration, teams consistently face severe bottlenecks. Legacy environments are notoriously opaque, making schema mapping and dependency tracking a manual nightmare. Furthermore, traditional migrations often rely on massive “big bang” cutovers that introduce unacceptable operational risks and system downtime.
Conversely, trying to run legacy and cloud systems in parallel usually triggers massive infrastructure costs and complex data drift, as standard ETL tools struggle to maintain real-time bidirectional synchronisation or handle high-throughput Change Data Capture (CDC) streams without crippling mainframe performance.
How IOblend Smooths the Migration Journey
This is where IOblend completely alters the migration playbook. Instead of forcing you to build a fragile, multi-tool stack, IOblend delivers a single, unified data integration application that standardises production pipelines on Apache Spark as portable JSON playbooks.
- Risk-Free Parallel Execution: IOblend allows you to de-risk your cloud migration by effortlessly running legacy and new systems in parallel. It handles real-time CDC and continuous data replication seamlessly, ensuring both systems remain synchronised without operational hitches.
- High-Throughput, Low-Latency Engine: Proven to handle over 1 million transactions per second with ultra-low P99 latency, IOblend processes massive mainframe batch runs and real-time streams without breaking a sweat.
- No Coding or Lock-In: Data teams can use a drag-and-drop designer to build event-driven pipelines. The system automatically generates optimised Spark jobs, using standard SQL or Python for complex transformations, ensuring your core logic remains entirely portable.
- End-to-End Observability: With record-level lineage, automated error handling, and visual debugging built in, you can trace data from its raw legacy roots right into the cloud lakehouse.
Don’t let legacy friction stall your modernisation strategy, turn your messy, scattered mainframe data into governed, cloud-ready gold by launching your migration with IOblend.

Optimising Customer Experience Through Real Time Data Sync
Optimising Customer Experiences Through Real Time Data Sync 🧠 Fun Fact: Did you know that 90% of the world’s data has been created in just the past two years? That’s a lot of information to manage – and a massive
How Poor Data Integration Drains Productivity & Profits
How Poor Data Integration Drains Productivity & Profits Data is one of the most valuable assets a company can possess. We all know that (and if you still do not, god help you). Businesses rely on data to make informed
How To Unlock Better Data Analytics with AI Agents
How To Unlock Better Data Analytics with AI Agents The new year brings with it new use cases. The speed with which the data industry evolves is incredible. It seems that the LLMs only appeared on the wider scene just