
From pipeline intent to production Spark.
Design the dataflow. Keep the logic portable. Let IOblend handle the execution plumbing. IOblend separates pipeline design, business rules and metadata from the infrastructure underneath—then turns that intent into production Apache Spark jobs inside the environment you control.
The logic is yours. The execution complexity is not.
IOblend is a metadata-driven production data layer. Engineers describe what a pipeline should do in Designer, store that intent as reusable JSON metadata, and let IOblend Engine convert it into the Spark processing required to run across enterprise systems.
For live data, IOblend supports database CDC and can also connect to Kafka to read streaming messages.
Your enterprise systems
Keep the technologies the organisation already depends on and bring batch, change data and live message streams into the same production layer.
IOblend
Pipeline design, DataOps and execution management in one operating model.
Where data is needed next
Serve the destination without rebuilding your architecture around IOblend.
Describe the pipeline once. Keep the intent portable.
IOblend playbooks store pipeline configuration, run parameters and business logic as JSON metadata. The Engine interprets that metadata at runtime instead of hard-wiring pipeline behaviour to a proprietary execution environment.
Your business logic is not trapped in a visual canvas.
Pipeline definitions are files. Transformations can remain in standard SQL and Python, making the important logic visible and reusable.
Treat pipelines like software, not configuration folklore.
JSON playbooks can sit in normal code repositories and participate in source-control, review and release workflows.
Turn working patterns into repeatable building blocks.
Components, configuration and logic can be reused rather than reconstructed every time a similar integration appears.
Change infrastructure without rewriting the business idea.
Storage, compute and pipeline intent are separated, reducing dependence on one destination, cloud or processing location.
Visual development without black-box engineering.
Designer accelerates how teams compose a DAG, but engineers still retain SQL and Python for specialised transformations, quality policies and business rules.
Build one component at a time
Add sources, transforms and sinks to the DAG and validate them as the pipeline takes shape.
Inspect schemas, metadata and run behaviour
Use development mode to see what each component is doing instead of debugging an opaque distributed job after deployment.
Prevent invalid logic from moving forward
IOblend's development workflow checks pipeline logic and SQL/Python execution before production deployment.
Retain revisions and move through CI/CD
Successful development runs validate the completed pipeline while revisions remain available for comparison and rollback.
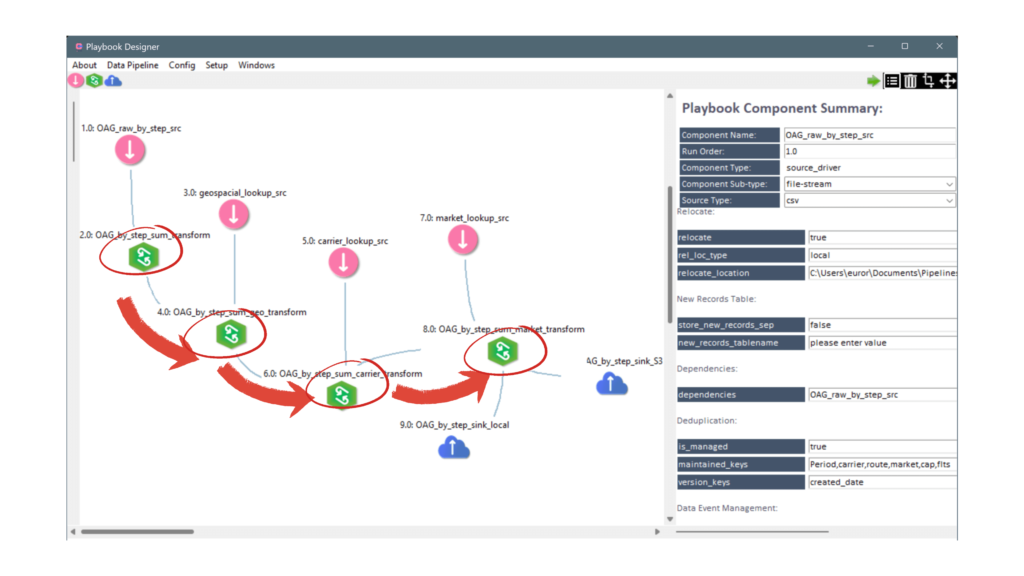
The Engine turns metadata into distributed processing.
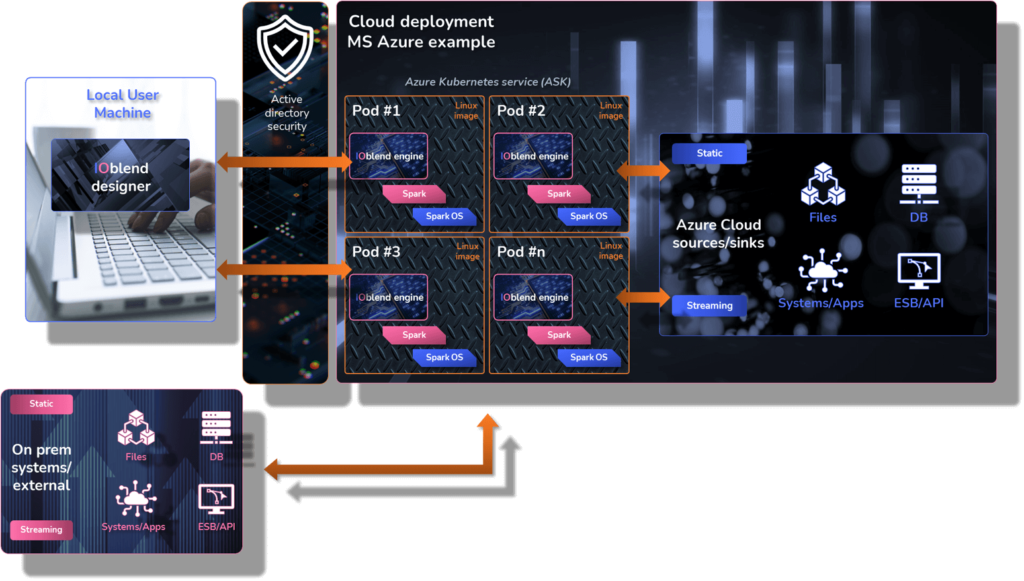
IOblend Engine is the runtime heart of the product. It reads the playbook, constructs the required Spark processing and executes the pipeline on compatible Spark infrastructure—without requiring teams to hand-code the orchestration layer for every job.
IOblend's execution layer uses Apache Spark™ ↗, the open-source engine for large-scale batch and streaming data processing.
Batch, streaming and CDC belong in the same conversation.
IOblend is designed around a Kappa-style model so teams do not need completely different development approaches for historical loads, live event streams and ongoing system synchronisation.
Production controls travel with the record.
The important production behaviour should not arrive as an afterthought. IOblend embeds lineage, CDC state, schema handling, deduplication, SCD/MDM patterns, metadata and exception management into the pipeline operating model itself.
Know what happened to the data—not just whether the job was green.
Trace and manage the lifecycle of records through ingestion, transformation and delivery.
Keep bad records from becoming everybody else's problem.
Apply rules in flight, isolate exceptions, preserve context and continue processing records that are fit for use.
Your environment stays the centre of gravity.
IOblend can be used locally for development and deployed into cloud or on-premises Spark infrastructure for production. The Engine runs inside the customer's environment and can work across hybrid and multi-cloud estates.
Put intelligence where enterprise context is already moving.
AI does not need to sit beside the integration architecture as another disconnected subsystem. IOblend can invoke Python-based AI logic inside the pipeline so unstructured content and model output can be validated and combined with normal enterprise data processing.
Unstructured data becomes another governed pipeline input.
Bring documents, messages or other unstructured content into the same production flow as structured enterprise data.
Less plumbing between AI and the data it needs.
Keep model-enabled processing inside the production dataflow, with quality, lineage and exception-management concepts surrounding it.
IOblend documents integration with LangChain ↗ for Python-based agent workflows.
Twelve similar source tables do not need twelve bespoke integration projects.
Metadata-driven execution is most valuable when the next pipeline can reuse the structure of the first one. This example shows the operating model rather than a customer benchmark.
One playbook family for a source domain.
Tables that share extraction, transformation, quality and destination patterns can be parameterised through reusable metadata and macros rather than maintained as twelve unrelated codebases.
Test components while you construct the flow.
IOblend can block invalid pipeline logic and SQL/Python errors during development, reducing the amount of separate test harness and deployment troubleshooting required later.
The pipeline logic stays separate from cluster plumbing.
The same portable definition can move from development into distributed Spark execution without rewriting business logic around a different orchestration framework.
Illustrative architecture / delivery pattern. Exact implementation effort, throughput and latency depend on source systems, data volumes, infrastructure and business rules.
Answers before the architecture conversation.
The questions enterprise architects and data engineering teams usually ask first.
How does IOblend work?
Teams build and test a pipeline DAG in IOblend Designer. Configuration, run parameters and business logic are stored in JSON playbooks. IOblend Engine interprets those playbooks and creates the Apache Spark processing needed to execute the pipeline on customer-controlled infrastructure.
Do we need to write Spark code?
No Spark coding is required for standard pipeline development. IOblend abstracts much of the Spark orchestration while allowing SQL and Python for transformations, quality rules and specialised business logic.
Can one pipeline mix batch, streaming and CDC?
Yes. IOblend is built to work with historical and live data within the same operating model, including Change Data Capture and real-time synchronisation use cases.
How does testing and CI/CD work?
Components are executable and testable during development. Invalid logic or SQL/Python can be prevented from executing, successful development runs validate the completed pipeline, revisions are retained, and JSON playbooks can be managed in normal source-control workflows.
Where does the Engine run?
IOblend can run locally for development and can deploy into on-premises or cloud Spark infrastructure. It is designed for cloud, on-premises, edge, hybrid and multi-cloud estates.
Does IOblend lock the business logic into the product?
The architecture is deliberately designed around portable metadata plus SQL and Python. If infrastructure changes, the core business intent does not have to be rewritten around a proprietary transformation language.
Bring us the integration your current stack makes painful.
We will map the sources, business logic, quality controls and target architecture—and show how the same requirement is expressed and executed with IOblend.