IOblend and Streamsets are both advanced data integration platforms that cater to the growing needs of businesses, especially in real-time analytics use cases. While there are similarities, they also bring different features to the table. Here’s an overview of their capabilities:
Real-time Data Integration
IOblend:
- Supports real-time, production-grade data pipelines using Apache Spark with proprietary tech enhancements.
- Can integrate equally streaming (transactional event) and batch data due to its Kappa architecture with full CDC capabilities.
Streamsets:
- Designed to handle streaming data with native support for change data capture (CDC) and supports both real-time and batch processing.
Low-code/No-code Development
IOblend:
- Provides low-code/no-code development, facilitating quicker data migration and minimization of manual data wrangling.
Streamsets:
- Features a drag-and-drop interface for designing data pipelines and also supports scripting for more intricate requirements.
Data Architecture
IOblend:
- Enables delivery of both centralized and federated data architectures.
Streamsets:
- Offers a flexible architecture allowing for both centralized and decentralized data operations.
Performance & Scalability
IOblend:
- Boasts low-latency, massively parallelized data processing with speeds exceeding 10 million transactions per second.
Streamsets:
- Optimized for performance in large-scale environments and supports various scalability configurations to handle growing data loads.
Partnerships & Cloud Integration
IOblend:
- Has real-time integration capabilities with Snowflake, AWS, Google Cloud and Azure products and is an ISV technology partner with Snowflake and Microsoft.
Streamsets:
- Provides integration with major cloud platforms including AWS, Azure, Google Cloud, as well as other platforms and data stores.
User Interface & Design
IOblend:
- Consists of two main components: IOblend Designer and IOblend Engine, facilitating design and execution respectively.
Streamsets:
- Offers a singular, intuitive platform called Streamsets Data Collector, tailored for designing, deploying, and monitoring data pipelines.
Data Management & Governance
IOblend:
- Ensures data integrity with features like automatic record-level lineage, CDC, SCD, metadata management, de-duping, cataloguing, schema drifts, windowing, regressions, eventing, late-arriving data, etc. integrated in every data pipeline.
- Connects to any data source via ESB/API/JDBC/flat files, both batch and streaming (inc. JDBC) with CDC (supports all three log, trigger or query based).
Streamsets:
- Prioritizes data drift management, ensuring pipeline robustness against changes in data, infrastructure, and schemas. Also has strong monitoring capabilities.
- 100+ pre-built connectors to all major data sources
Cost & Licensing
IOblend:
- The Developer Edition is free, while the Enterprise Suite requires a paid annual license.
Streamsets:
- Offers a free community version and premium versions with added functionalities and support.
Deployment & Flexibility
IOblend:
- Operational on any cloud, on-premises, or in hybrid settings. Comes in Developer and Enterprise Editions.
Streamsets:
- Supports deployment in cloud, on-premises, and edge devices, ensuring flexibility in data operations.
Community & Support
IOblend:
- Being relatively new, its community is still burgeoning. Provides online support for Developer Edition and premium support for Enterprise Edition.
Streamsets:
- Sports a vibrant community providing resources, plugins, and assistance. Premium support is also available for enterprise-grade users.
To sum up, while IOblend places emphasis on real-time data integration and low-code solutions, Streamsets is tailored for handling streaming data with an emphasis on data drift management. Choosing between them would rest on the specific requirements, infrastructure, and objectives of an organization.

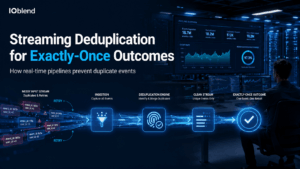
Streaming Deduplication for Exactly-Once Outcomes
Deduplicate Streaming Events: Exact-Once Outcomes in Real Life 📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads. Understanding exact-once outcomes In real-time data engineering, achieving
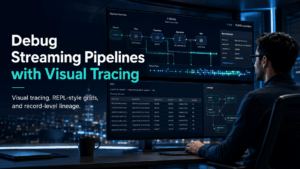
Visual Debugging for Apache Spark Streams
Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration 📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory,
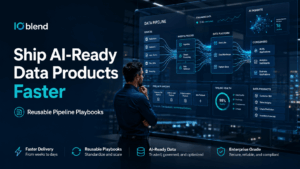
Ship AI-Ready Data Products Faster
Build a “Data Product” in Days: Reusable Pipeline Playbooks 📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority