Democratising Spark: How IOblend enables Data Analysts to build production-grade Spark pipelines without writing Scala or Java
Did You Know? The average enterprise now manages over 350 different data sources, yet nearly 70% of data leaders report feeling “trapped” by their own infrastructure.
The Concept: Democratising the Spark Engine
At its core, Apache Spark is a lightning-fast, distributed computing framework capable of processing petabytes of data. However, for years, “production-grade” Spark was synonymous with complex software engineering.
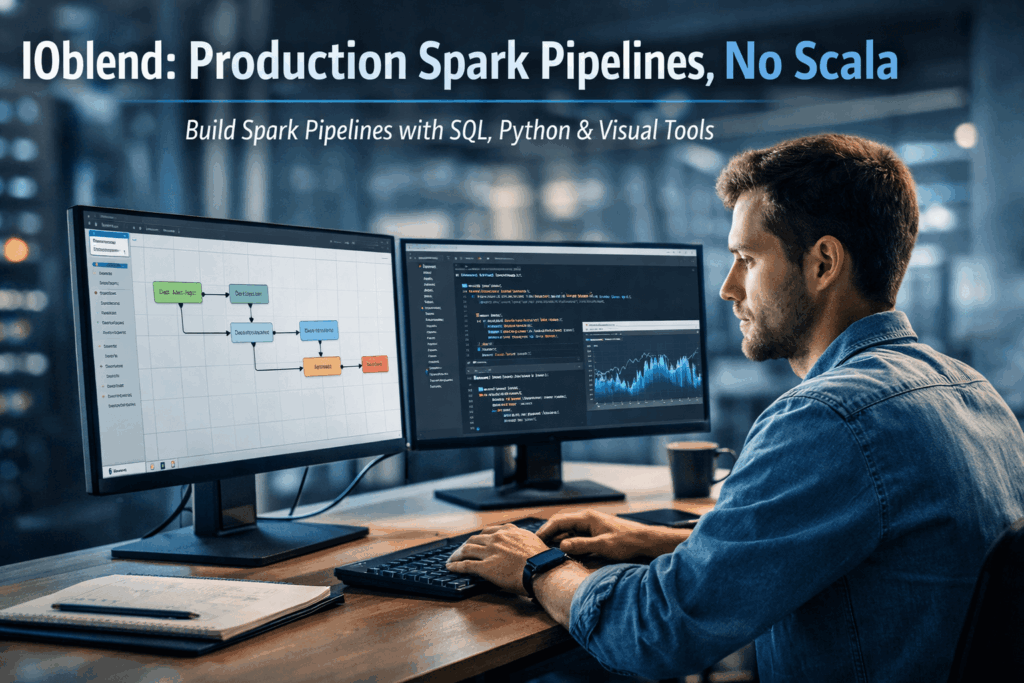
IOblend changes this narrative by decoupling the power of Spark from the complexity of its code. It acts as a sophisticated abstraction layer, a managed Spark DataOps environment, that allows Data Analysts to build, deploy, and govern high-performance pipelines using only SQL, Python, or an intuitive drag-and-drop interface.
Why Businesses Struggle
For most organisations, the path from “data ingestion” to “actionable insight” is riddled with three primary obstacles:
- The Talent Gap: Expert Spark developers (fluent in Scala or Java) are rare and expensive. This creates a dependency where Analysts must wait months for Engineering teams to “productionise” a simple data model.
- Brittle Pipelines: Traditional hand-coded pipelines often lack built-in DataOps. Without automated error handling, record-level lineage, or schema drift detection, pipelines “fail quietly,” leading to untrustworthy reports.
- Real-Time Rigidity: Many legacy systems are built on batch processing. Transitioning to real-time streaming usually requires a complete architectural overhaul, often resulting in “vendor lock-in” to expensive cloud ecosystems.
The IOblend Solution: Production Power Without the Code
IOblend transforms these challenges into a streamlined, automated workflow. By utilising a Kappa-based architecture, it treats batch and streaming data with equal ease, allowing businesses to achieve 90% faster delivery of data products.
Key features that solve common business issues include:
- Visual Designer & Engine: Use a desktop GUI to design complex Directed Acyclic Graphs (DAGs). The IOblend Engine then converts these into efficient Spark jobs that run on any infrastructure, on-prem, cloud, or hybrid.
- In-built DataOps: Every pipeline automatically includes record-level lineage, Change Data Capture (CDC), and Slowly Changing Dimensions (SCD). You no longer need to “bolt-on” governance; it is baked into the metadata.
- Agentic AI Integration: Uniquely, IOblend allows you to embed AI agents directly into the ETL flow. You can validate, ground, and transform unstructured data before it even hits your warehouse.
- Zero Lock-in: Pipelines are stored as portable JSON playbooks. This ensures your business logic remains your own, easily versioned in standard repositories like Git.
It’s time to find your flow with IOblend.

Better airport operations with real-time analytics
Good and bad Welcome to the next issue of our real-time analytics blog. Now that the summer holiday season is upon us, many of us will be using air travel to get to their destinations of choice. This means, we
The making of a commercial flight
What makes a flight Welcome to the next leg of our airline data blog journey. In this article, we will be looking at what happens behind the scenes to make a single commercial flight, well, take flight. We will again

Enhance your airline’s analytics with a data mesh
Building a flying program In the last blog, I have covered how airlines plan their route networks using various strategies, data sources and analytical tools. Today, we will be covering how the network plan comes to life. Once the plans