Deduplicate Streaming Events: Exact-Once Outcomes in Real Life
📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads.
Understanding exact-once outcomes
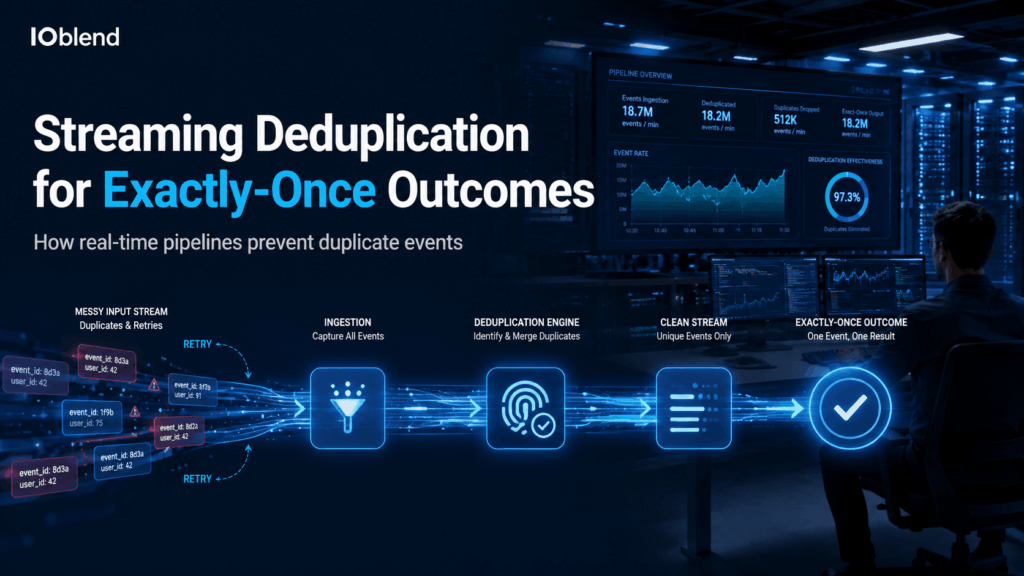
In real-time data engineering, achieving “exactly-once” outcomes does not mean a message is transported across the wire only once, distributed networks make physical delivery guarantees at the wire level impossible. Instead, it means that despite network timeouts, retries, and consumer restarts, the end result of processing a message is committed to your target system precisely once. Stateful deduplication is the engine behind idempotency, transforming an unruly “at-least-once” stream into crisp, deterministic data states.
The painful business cost of duplicate streams
When organisations rely on streaming architectures for real-time analytics or operational automation, duplicate records create severe operational friction:
- Financial and transactional distortion: Consider a fintech payment gateway processing thousands of transactions per second. If a network glitch triggers a producer retry and the pipeline lacks stateful deduplication, a payment event is processed twice, leading to duplicate debits, compliance breaches, and customer churn.
- Corrupted analytics and AI models: In IoT fleet management or airline logistics, duplicated telemetry events distort windowed aggregations. A safety monitoring system reading doubled sensor pings might falsely trigger emergency alerts or corrupt real-time ML feature stores, degrading decision quality.
- Engineering complexity and infrastructure bloat: Building custom deduplication logic in native Apache Spark or Flink requires managing state stores, handling late-arriving data, and writing complex windowing boilerplate.
Solved: Seamless deduplication with IOblend
To achieve true exactly-once processing without drowning in custom code, modern data teams rely on IOblend. Designed around a high-performance Kappa architecture powered by Apache Spark, IOblend abstracts away the heavy lifting of stateful streaming pipelines.
- In-built, zero-code deduplication: IOblend provides automated, record-level de-duping, full-spectrum Change Data Capture (CDC), and real-time upserts out of the box. Engineers no longer need to write complex Spark code or maintain custom state managers.
- Ultra-low latency at scale: Operating seamlessly in-memory on modest hardware or existing Spark infrastructure (such as Databricks or cloud EMR), IOblend processes over 1,000,000 transactions per second at P99 ultra-low latencies.
- Unified stream and batch DataOps: By defining portable playbooks, IOblend unifies streaming and batch workloads while managing schema drift and record-level lineage automatically.
Blend precision into your real-time data pipelines with IOblend.

Optimising Customer Experience Through Real Time Data Sync
Optimising Customer Experiences Through Real Time Data Sync 🧠 Fun Fact: Did you know that 90% of the world’s data has been created in just the past two years? That’s a lot of information to manage – and a massive
How Poor Data Integration Drains Productivity & Profits
How Poor Data Integration Drains Productivity & Profits Data is one of the most valuable assets a company can possess. We all know that (and if you still do not, god help you). Businesses rely on data to make informed
How To Unlock Better Data Analytics with AI Agents
How To Unlock Better Data Analytics with AI Agents The new year brings with it new use cases. The speed with which the data industry evolves is incredible. It seems that the LLMs only appeared on the wider scene just