
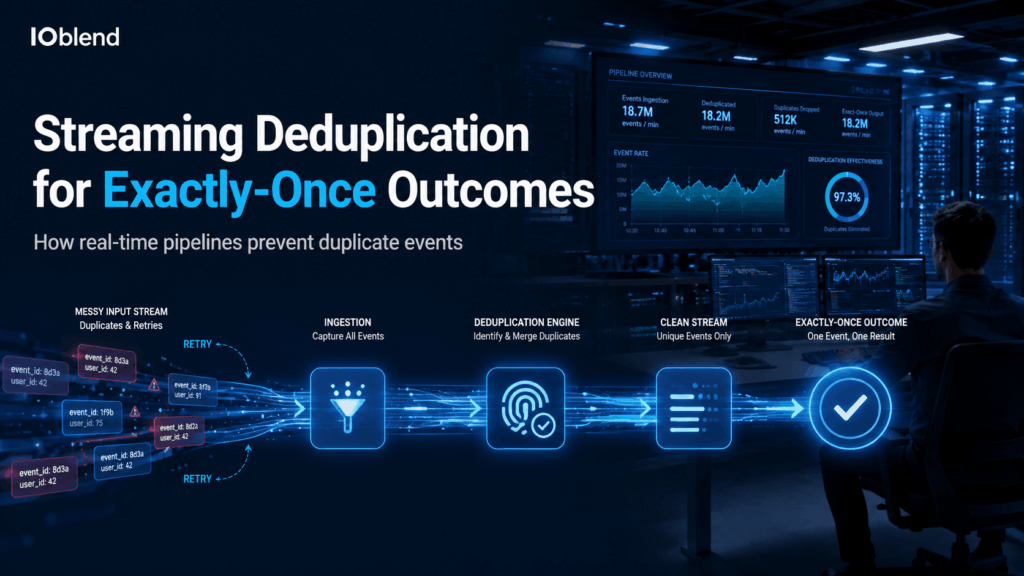
Deduplicate Streaming Events: Exact-Once Outcomes in Real Life
📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads.
Understanding exact-once outcomes
In real-time data engineering, achieving “exactly-once” outcomes does not mean a message is transported across the wire only once, distributed networks make physical delivery guarantees at the wire level impossible. Instead, it means that despite network timeouts, retries, and consumer restarts, the end result of processing a message is committed to your target system precisely once. Stateful deduplication is the engine behind idempotency, transforming an unruly “at-least-once” stream into crisp, deterministic data states.
The painful business cost of duplicate streams
When organisations rely on streaming architectures for real-time analytics or operational automation, duplicate records create severe operational friction:
- Financial and transactional distortion: Consider a fintech payment gateway processing thousands of transactions per second. If a network glitch triggers a producer retry and the pipeline lacks stateful deduplication, a payment event is processed twice, leading to duplicate debits, compliance breaches, and customer churn.
- Corrupted analytics and AI models: In IoT fleet management or airline logistics, duplicated telemetry events distort windowed aggregations. A safety monitoring system reading doubled sensor pings might falsely trigger emergency alerts or corrupt real-time ML feature stores, degrading decision quality.
- Engineering complexity and infrastructure bloat: Building custom deduplication logic in native Apache Spark or Flink requires managing state stores, handling late-arriving data, and writing complex windowing boilerplate.
Solved: Seamless deduplication with IOblend
To achieve true exactly-once processing without drowning in custom code, modern data teams rely on IOblend. Designed around a high-performance Kappa architecture powered by Apache Spark, IOblend abstracts away the heavy lifting of stateful streaming pipelines.
- In-built, zero-code deduplication: IOblend provides automated, record-level de-duping, full-spectrum Change Data Capture (CDC), and real-time upserts out of the box. Engineers no longer need to write complex Spark code or maintain custom state managers.
- Ultra-low latency at scale: Operating seamlessly in-memory on modest hardware or existing Spark infrastructure (such as Databricks or cloud EMR), IOblend processes over 1,000,000 transactions per second at P99 ultra-low latencies.
- Unified stream and batch DataOps: By defining portable playbooks, IOblend unifies streaming and batch workloads while managing schema drift and record-level lineage automatically.
Blend precision into your real-time data pipelines with IOblend.

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit Trails 📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur? Understanding migration QA at scale Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands 📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers. The Concept: Stopping Bad Data at the Border Lakehouse Quality Gates are automated,
Automated Data Contracts: Stop Schema Drift
Data Contracts That Stick: Enforce Schema and Expectations Automatically 📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts A data contract is

