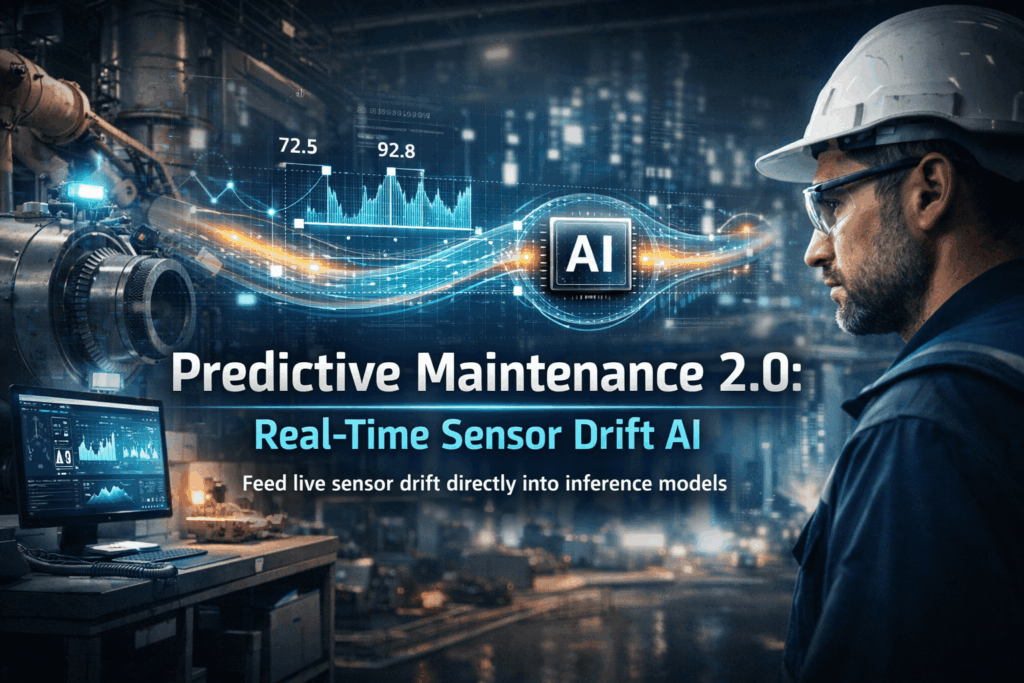
Predictive Maintenance 2.0: Feeding real-time sensor drifts directly into inference models using streaming engineĀ
š©Ā Did you know? The cost of unplanned downtime for industrial manufacturers is estimated at nearly Ā£400 billion annually.Ā
Predictive Maintenance 2.0: The Real-Time EvolutionĀ
Predictive Maintenance 2.0 represents a paradigm shift from batch-processed diagnostics to live, autonomousĀ synchronisation. In the traditional 1.0 era, data was collected, stored in a lake, andĀ analysedĀ hours or days later. Predictive Maintenance 2.0, however, feeds real-time sensor drifts, the gradual deviation of a sensorās output from its true value directly into inference models. By treating data as a continuous stream rather than a static snapshot, businesses can adjust their AI’s baseline in milliseconds, ensuring that “model decay” never interferes with operational safety.Ā
The Problem: The Drift Dilemma and Data LatencyĀ
For most data experts, the hurdle isn’t building the machine learning model; it is the “data plumbing” required to keep it accurate. Industrial sensors operate in harsh environments where heat, vibration, and age cause readings to drift.Ā
Ā
Standard architectures struggle with this for two reasons.Ā
Firstly, Data Latency: By the time sensor data is cleaned and moved through a traditional ETL (Extract, Transform, Load) pipeline, the “real-time” window has closed.Ā
Secondly, Feature Inconsistency: If an inference model is fed raw, unadjusted drift data, it triggers false positives.Ā
TheĀ IOblendĀ Solution: Streamlining the Edge to InferenceĀ
This is where IOblend transforms the landscape. IOblendās streaming engine is designed to eliminate the friction between raw IoT outputs and production-ready AI.Ā
- Real-time Transformation at Scale:Ā IOblendĀ allows data engineers to build high-performance streaming pipelines that perform complex transformations, such asĀ normalisingĀ sensor drift on the fly. Instead of waiting for a batch job,Ā IOblendāsĀ engine calculates moving averages and handles out-of-order events instantly, ensuring the inference model receives perfectly “cleaned” features.Ā
- Unified Data Engineering:Ā IOblendĀ simplifies the tech stack by merging streaming and batch processing into a single workflow. For a manufacturer, this means using the same logic to train a model on historical data as they do to run inference on live sensor streams. This consistency eliminates the “training-serving skew” that plagues many predictive projects.Ā
- Automated Schema Evolution:Ā In complex industrial setups, adding new sensors or updating firmware often breaks data pipelines.Ā IOblendāsĀ “Data Engineering in a Box” approach handles these changes automatically, ensuring that the flow of drift data to your inference models remains uninterrupted.Ā
Ready to eliminate downtime?Ā SynchroniseĀ your data and your destiny withĀ IOblend.Ā
IOblend presents a ground-breaking approach to IoT and data integration, revolutionizing the way businesses handle their data. It’s an all-in-one data integration accelerator, boasting real-time, production-grade, managed Apache Spark⢠data pipelines that can be set up in mere minutes. This facilitates a massive acceleration in data migration projects, whether from on-prem to cloud or between clouds, thanks to its low code/no code development and automated data management and governance.
IOblend also simplifies the integration of streaming and batch data through Kappa architecture, significantly boosting the efficiency of operational analytics and MLOps. Its system enables the robust and cost-effective delivery of both centralized and federated data architectures, with low latency and massively parallelized data processing, capable of handling over 10 million transactions per second. Additionally, IOblend integrates seamlessly with leading cloud services like Snowflake and Microsoft Azure, underscoring its versatility and broad applicability in various data environments.
At its core, IOblend is an end-to-end enterprise data integration solution built with DataOps capability. It stands out as a versatile ETL product for building and managing data estates with high-grade data flows. The platform powers operational analytics and AI initiatives, drastically reducing the costs and development efforts associated with data projects and data science ventures. It’s engineered to connect to any source, perform in-memory transformations of streaming and batch data, and direct the results to any destination with minimal effort.
IOblendās use cases are diverse and impactful. It streams live data from factories to automated forecasting models and channels data from IoT sensors to real-time monitoring applications, enabling automated decision-making based on live inputs and historical statistics. Additionally, it handles the movement of production-grade streaming and batch data to and from cloud data warehouses and lakes, powers data exchanges, and feeds applications with data that adheres to complex business rules and governance policies.
The platform comprises two core components: the IOblend Designer and the IOblend Engine. The IOblend Designer is a desktop GUI used for designing, building, and testing data pipeline DAGs, producing metadata that describes the data pipelines. The IOblend Engine, the heart of the system, converts this metadata into Spark streaming jobs executed on any Spark cluster. Available in Developer and Enterprise suites, IOblend supports both local and remote engine operations, catering to a wide range of development and operational needs. It also facilitates collaborative development and pipeline versioning, making it a robust tool for modern data management and analytics

Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit TrailsĀ šĀ Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur?Ā Understanding migration QA at scaleĀ Migration QA

Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data LandsĀ šĀ Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing globalĀ organisationsĀ billions each year in wasted compute, broken analytical models, and polluted