Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration
📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory, traditional breakpoints and step-through debugging are impossible without stopping the entire world, corrupting states, and causing downstream disaster.
The Concept of Visual Tracing
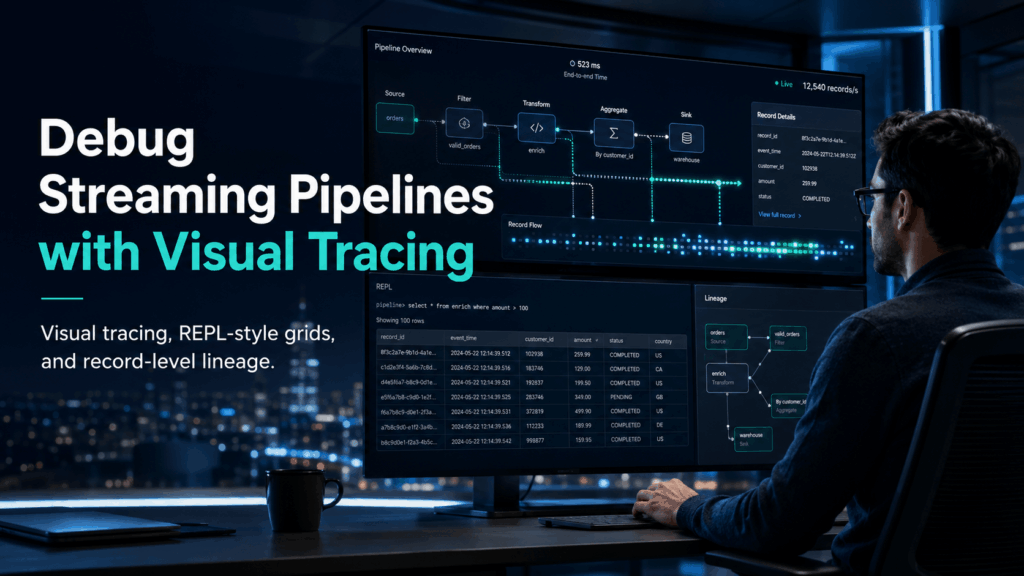
Streaming debugging is notoriously complex. Unlike batch processing, where you can pause, inspect, and rerun a static chunk of data, streaming flows constantly. Visual tracing changes this entirely. It acts like a high-speed camera for data-in-motion, allowing data experts to map out data flows and evaluate execution blocks in real time. Instead of looking at unformatted command-line error logs, engineers can see records moving through transformations interactively, mimicking Read-Eval-Print Loop (REPL) interactive grids.
Streaming Bottlenecks for Modern Enterprises
Building real-time data architectures, like Kappa or Lambda models, presents massive operational challenges for businesses:
- The Black Box Dilemma: When an aggregate metric spikes or a schema drifts, finding the exact corrupted record or broken joint downstream requires hours of parsing log files.
- Sluggish Iteration Cycles: Testing a minor business logic adjustment or custom Python snippet often requires full redeployment to a remote Apache Spark or Apache Flink cluster, dragging out development phases from days into weeks.
- Late-Arriving Records & Drift: Data arriving out of order or unexpected upstream structural modifications can silently break hand-written stateful transformations, resulting in inaccurate real-time dashboards and broken business trust.
The IOblend Solution
To overcome these production bottlenecks, IOblend shifts the entire streaming paradigm by embedding built-in DataOps directly into a low-code visual environment. Running on a highly optimised Kappa architecture, IOblend autogenerates distributed Apache Spark streaming jobs without requiring manual code.
For data experts debugging complex streams, IOblend provides specific, production-ready capabilities:
- Visual Debugging & REPL Grids: Test real-time data flows locally via an interactive developer desktop application with REPL-like data grids, allowing you to iterate instantly before pushing pipelines live.
- Granular Record-Level Lineage: If an error occurs, IOblend tracks data changes down to the individual record, exposing exactly what modified the data.
- Automated Drift & Late Data Handling: It automatically tracks schema evolution, protects data contracts, and seamlessly replays transforms whenever late-arriving data hits the engine.
Simplify your pipelines and scale with confidence by leveraging the real-time observability of IOblend.

Change Data Capture: IOblend’s Seamless Approach
Change Data Capture In the fast-paced world of data management, staying ahead of the curve is not an option, it’s a necessity. Change Data Capture (CDC) is the secret weapon that allows businesses to keep pace with the constant flux
Data Schema Management with IOblend
Data Schema Management In today’s data-driven world, managing data effectively is crucial for businesses seeking to gain insights and make informed decisions. Data schema management is a fundamental aspect of this process, ensuring that data is organized, structured, and compatible
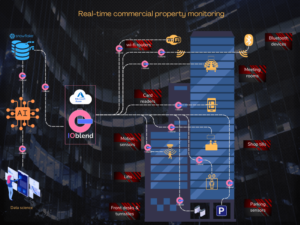
Smarter office management with real-time analytics
Commercial property Welcome to the next issue of our real-time analytics blog. This time we are taking a detour from the aviation analytics to the world of commercial property management. The topic arose from a use case we are working