
Beyond Micro-batching: Why Continuous Streaming Engine is the Future of “Fresh Data” for AIÂ
💻 Did you know? Most modern “real-time” AI applications are actually running on data that is already several minutes old. Traditional micro-batching collects data into small chunks before processing it, introducing a “latency tax” that can render predictive models obsolete before they even fire.Â
The Concept of Continuous Streaming
While micro-batching is essentially a series of very fast traditional batches, continuous streaming is a smooth, uninterrupted flow. A continuous engine processes each data event the moment it occurs. It moves beyond the limitations of Apache Spark’s standard micro-batching intervals, delivering true sub-second freshness by treating data as a perpetual, living stream rather than a collection of small files.Â
The “Stale Data” Crisis in Modern AIÂ
For data experts, the issue is clear: AI is only as good as its last update. In high-stakes environments, such as fraud detection, dynamic pricing, or autonomous logistics a 60-second delay is an eternity.Â
Businesses today face a “complexity wall.” To achieve true real-time speeds, they are often forced to maintain two separate architectures: a batch layer for historical accuracy and a streaming layer for speed. This leads to:Â
- Inconsistent Logic: Different codebases for batch and stream.Â
- Infrastructure Bloat: Managing separate clusters for Flink, Kafka, and Spark.Â
- Data Drift: The nightmare of keeping training data in sync with real-time inference data.Â
How IOblend Solves the Freshness GapÂ
IOblend replaces this fragmented mess with a “Feature Store without the Store,” leveraging its continuous streaming engine to unify the lifecycle of data. Based on its advanced technology, IOblend provides:Â
- True Streaming, Not Mini-Batch: It extends Spark to run pipelines with P99 freshness and over 1 million transactions per second (TPS), ensuring AI models always act on “Fresh Data.”Â
- The Kappa Architecture Advantage: By using a single engine for both batch and real-time data, IOblend eliminates the need for redundant systems, reducing infrastructure costs by up to 50%.Â
- In-Built DataOps & Governance: Unlike DIY setups, IOblend has record-level lineage, Change Data Capture (CDC), and schema drift management baked into the engine. It automatically handles late-arriving data and stateful transformations like windowed joins and deduplication.Â
- Agentic AI Integration: IOblend allows you to embed AI agents directly into the data flow. These agents can process unstructured documents or validate data quality before it lands in your warehouse, moving intelligence to the far left of the pipeline.Â
By removing the friction between data ingestion and model inference, IOblend ensures that your AI isn’t just fast it’s actually current.Â
Stop settling for “fast enough” and start seeing more with IOblend.Â
IOblend presents a ground-breaking approach to IoT and data integration, revolutionizing the way businesses handle their data. It’s an all-in-one data integration accelerator, boasting real-time, production-grade, managed Apache Spark™ data pipelines that can be set up in mere minutes. This facilitates a massive acceleration in data migration projects, whether from on-prem to cloud or between clouds, thanks to its low code/no code development and automated data management and governance.
IOblend also simplifies the integration of streaming and batch data through Kappa architecture, significantly boosting the efficiency of operational analytics and MLOps. Its system enables the robust and cost-effective delivery of both centralized and federated data architectures, with low latency and massively parallelized data processing, capable of handling over 10 million transactions per second. Additionally, IOblend integrates seamlessly with leading cloud services like Snowflake and Microsoft Azure, underscoring its versatility and broad applicability in various data environments.
At its core, IOblend is an end-to-end enterprise data integration solution built with DataOps capability. It stands out as a versatile ETL product for building and managing data estates with high-grade data flows. The platform powers operational analytics and AI initiatives, drastically reducing the costs and development efforts associated with data projects and data science ventures. It’s engineered to connect to any source, perform in-memory transformations of streaming and batch data, and direct the results to any destination with minimal effort.
IOblend’s use cases are diverse and impactful. It streams live data from factories to automated forecasting models and channels data from IoT sensors to real-time monitoring applications, enabling automated decision-making based on live inputs and historical statistics. Additionally, it handles the movement of production-grade streaming and batch data to and from cloud data warehouses and lakes, powers data exchanges, and feeds applications with data that adheres to complex business rules and governance policies.
The platform comprises two core components: the IOblend Designer and the IOblend Engine. The IOblend Designer is a desktop GUI used for designing, building, and testing data pipeline DAGs, producing metadata that describes the data pipelines. The IOblend Engine, the heart of the system, converts this metadata into Spark streaming jobs executed on any Spark cluster. Available in Developer and Enterprise suites, IOblend supports both local and remote engine operations, catering to a wide range of development and operational needs. It also facilitates collaborative development and pipeline versioning, making it a robust tool for modern data management and analytics

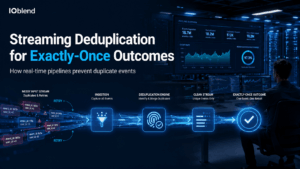
Streaming Deduplication for Exactly-Once Outcomes
Deduplicate Streaming Events: Exact-Once Outcomes in Real Life 📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads. Understanding exact-once outcomes In real-time data engineering, achieving “exactly-once” outcomes does not mean a message is transported across the wire only once, distributed
Visual Debugging for Apache Spark Streams
Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration 📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory, traditional breakpoints and step-through debugging are impossible without stopping the entire world, corrupting states, and
Ship AI-Ready Data Products Faster
Build a “Data Product” in Days: Reusable Pipeline Playbooks 📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority of their time building the same structural boilerplate over and over again. What are reusable
Schema Evolution with Strong Data Contracts
Schema Evolution Without Chaos: Strong Data Contracts Enforced In Pipelines 📋 Did you know? In the early days of big data, a single altered column in a production database could trigger a catastrophic “data graveyard” effect. The Concept of Schema Evolution Schema evolution is the ability of a data platform to gracefully adapt to structural changes
Mainframe to Cloud: Data Migration with CDC
Mainframe to Cloud: A Practical Data Migration Playbook 💾 Did you know? An alarming 83% of data migrations fail outright or drastically overrun their budgets. Shifting Mainframe Heavyweights to the Cloud Mainframe-to-cloud data migration is the process of moving core legacy data assets, often stored in rigid formats like DB2, VSAM, or IMS, into modern cloud
Real-Time CDC to Databricks Delta Tables
Realtime Ingestion to Databricks: From Source to Delta Tables 💽 Did you know? According to industry surveys, nearly eighty per cent of an enterprise’s data budget is consumed purely by data integration and upfront data wrangling rather than actual analytics. Defining real-time ingestion Real-time ingestion to Databricks represents the technical evolution from rigid scheduled batch processing

