From DB2 to Lakehouse: Real-Time CDC Without Re-Platforming
💻 Did you know? Mainframe systems like DB2 still process approximately 30 billion business transactions every single day. Despite the rush toward modern cloud architectures, the world’s most critical financial and logistical data often resides in these “legacy” environments, making them the silent engines of the global economy.
The Concept: Bridging the Gap
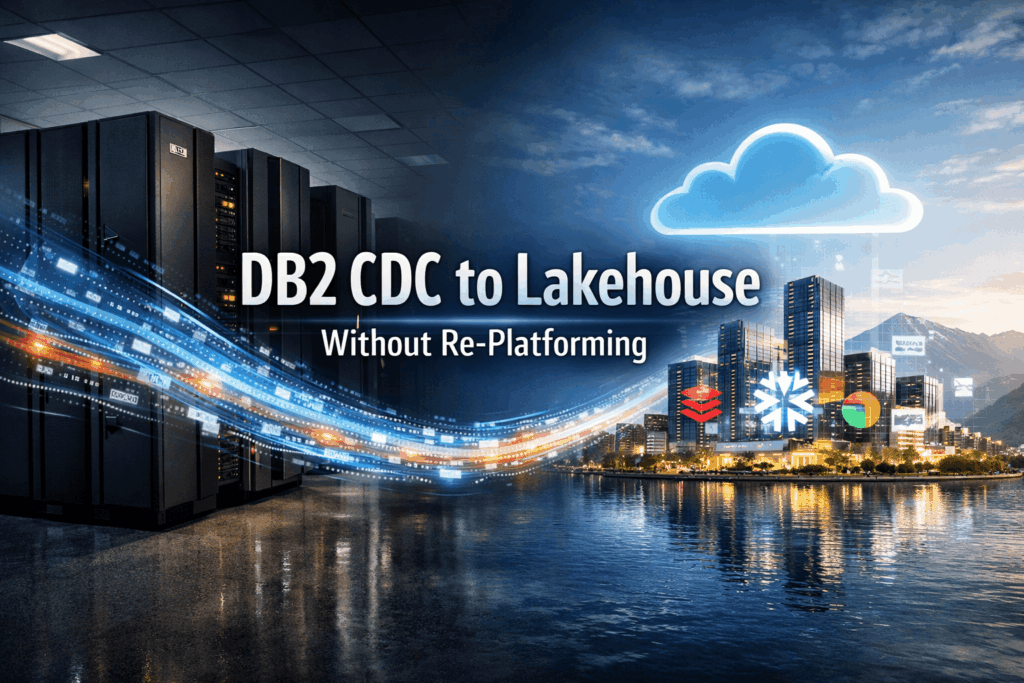
The journey from a traditional DB2 relational database to a modern Data Lakehouse is often framed as a binary choice: stay put and suffer from data latency, or undergo a multi-year “re-platforming” nightmare. Real-time Change Data Capture (CDC) offers a third way. It involves identifying and capturing every insertion, update, or deletion in the DB2 source as it happens and immediately streaming those changes to a Lakehouse (like Snowflake, Databricks, or Fabric). This creates a live, synchronised mirror of your operational data, ready for AI and analytics, without moving the original database.
The Friction: Why Legacy Systems Stall Innovation
Enterprises relying on DB2 frequently hit a wall when trying to feed modern analytics platforms. The primary issue is Batch Latency; waiting for nightly ETL runs means your “real-time” dashboard is actually 24 hours out of date.
Furthermore, DB2 environments are notoriously sensitive. Traditional query-based extraction puts an immense “observer load” on the production system, slowing down the very transactions the business depends on.
There is also the Complexity Trap: many CDC tools require installing invasive agents on the mainframe or demand bespoke coding to handle schema evolution.
The Friction: Why The Solution: IOblend’s Modern Path
This is where IOblend transforms the architecture. Rather than requiring a total re-platforming, IOblend provides an “AI-Forward” ingestion and transformation layer that specialises in high-speed, agentless CDC.
Real-World Use Case: Financial Services
Consider a bank running core ledgers on DB2. By using IOblend, they can stream transaction logs into a Lakehouse in seconds. IOblend handles the complex schema mapping and data type conversions automatically.
How IOblend Solves the Issue:
- Zero-Code Engineering: IOblend replaces manual Python or SQL pipelines with an intuitive interface, allowing experts to focus on data strategy rather than plumbing.
- Agentless CDC: It captures changes without taxing the DB2 source, ensuring production performance remains intact.
- Automatic Schema Evolution: If a table structure changes in DB2, IOblend detects and propagates that change to the Lakehouse automatically, preventing pipeline failure.
- Unified Data Flow: IOblend merges ingestion and transformation into a single move, ensuring data is “AI-ready” the moment it hits the Lakehouse.
Stop migrating and start innovating, unleash your legacy data with the power of IOblend.

Streaming Deduplication for Exactly-Once Outcomes
Deduplicate Streaming Events: Exact-Once Outcomes in Real Life 📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads. Understanding exact-once outcomes In real-time data engineering, achieving
Visual Debugging for Apache Spark Streams
Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration 📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory,
Ship AI-Ready Data Products Faster
Build a “Data Product” in Days: Reusable Pipeline Playbooks 📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority