AW-10865990051

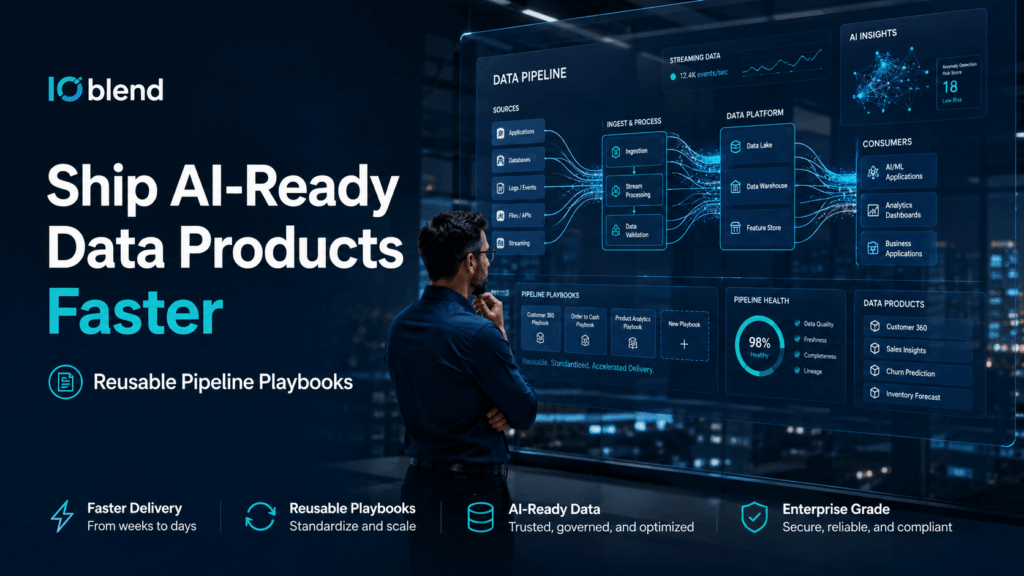
Ship AI-Ready Data Products Faster

Ship AI-Ready Data Products Faster IOblend

Build a “Data Product” in Days: Reusable Pipeline Playbooks 

📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority of their time building the same structural boilerplate over and over again. 

What are reusable pipeline playbooks? 

A data product treats data as a curated, standalone asset designed for immediate business consumption. Historically, shipping a new data product meant writing bespoke, monolithic Extract, Transform, Load (ETL) code. Reusable pipeline playbooks flip this model. They decouple infrastructure and orchestration from business rules by storing dataflows as modular, metadata-driven configuration files (like JSON). This means you can standardise ingestion, cleaning, and delivery into plug-and-play templates. Data teams can instantiate a robust, production-grade data product in days by simply feeding new schemas or parameters into an existing playbook.

Common architectural bottlenecks  

Most enterprises suffer from brittle, hand-coded pipelines that cannot scale. When a source schema changes unexpectedly, downstream systems break silently, causing data drift chaos. 

Consider a financial services firm trying to create an emergency risk-analytics data product. The engineering team has to stitch together historical batch databases and real-time streaming feeds. They spend weeks writing complex Apache Spark™ logic, managing Slowly Changing Dimensions (SCD), tracking record-level lineage, and tuning infrastructure. By the time the code is tested and deployed, the business opportunity has passed, and the team is trapped under a mountain of maintenance technical debt. 

Accelerating data products with IOblend

This is precisely where IOblend eliminates friction. IOblend standardises production data pipelines on Spark as portable, lightweight JSON playbooks. It provides a low-code, drag-and-drop interface that abstracts the engineering complexity while autogenerating highly optimised distributed compute code behind the scenes. 

  • Seamless Kappa Architecture: Easily mix real-time streaming and batch sources dynamically without writing disparate pipelines. 
  • Built-in DataOps & Governance: Out-of-the-box features automatically handle Change Data Capture (CDC), Type I and II SCD regressions, deduplication, and record-level lineage. 
  • Resilience to Drift: Schema evolution is managed safely via strong data contracts, ensuring pipelines never fail quietly. 

With IOblend, you build your core dataflow logic once and run it anywhere, across multi-cloud, on-prem, or hybrid environments. 

Stop wasting quarters hand-coding brittle pipelines; accelerate your modern data estate and ship production-ready data products in days with IOblend. 

IOblend: See more. Do more. Deliver better.

AI

Digital Twin Evolution: Big Data & AI with

The Industrial Renaissance: How Agentic AI and Big Data Power the Self-Optimising Digital Twin  🏭 Did You Know? A fully realised industrial Digital Twin, underpinned by real-time data, has been proven to reduce unplanned production downtime by up to 20%.  The Digital Twin Evolution 
Read More »
AI

Unify Clinical & Financial Data to Cut Readmissions

Clinical-Financial Synergy: The Seamless Integration of Clinical and Financial Data to Minimise Readmissions   🚑 Did You Know? Unnecessary hospital readmissions within 30 days represent a colossal financial burden, often reflecting suboptimal transitional care.  Clinical-Financial Synergy: The Seamless Integration of Clinical and Financial

Read More »
Scroll to Top