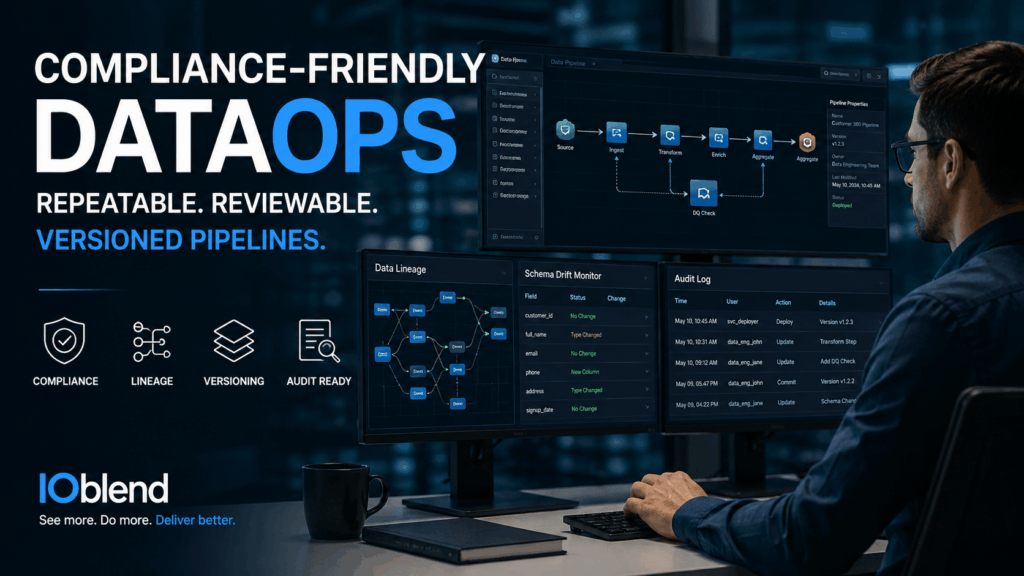
Compliance-Friendly DataOps: Repeatable, Reviewable, Versioned Pipelines
📓 Did you know? According to industry compliance reports, nearly 70% of businesses face difficulties tracing their data back to its raw origins during regular regulatory audits.
The Concept of Compliance-Friendly DataOps
Compliance-friendly DataOps represents an operational framework that embeds strict regulatory governance directly into the data engineering lifecycle. Instead of treating data auditing as an afterthought, this methodology ensures that data transformation pipelines are systematically repeatable, fully reviewable, and meticulously versioned. In practice, this means every single record can be traced back to its precise source code state and ingestion window.
Fragmented Pipelines and the Cost of Chaos
Modern enterprise data architectures are frequently crippled by structural drift and opaque processing layers. Data experts regularly battle with fragmented workflows where a sudden upstream schema change completely breaks downstream analytics without warning.
When a financial institution or healthcare provider is asked to explain a specific metric to an auditor, they are forced into a scramble of manual code inspection, database log reconstruction, and speculative debugging.
Consider a real-world use case in banking risk assessment. If a machine learning model flags an account based on transformed streaming data, compliance requires absolute reproducibility. Without pipeline versioning, reproducing the exact state of that data from three months ago is practically impossible.
The IOblend Solution
Designed as an advanced end-to-end data integration application with native DataOps capability, IOblend standardises production data pipelines on Apache Spark as portable JSON and Python playbooks.
IOblend resolves enterprise governance challenges through an array of built-in production features:
- Automated Record-Level Lineage: It registers auditing metadata dynamically across the full data journey, giving experts precise visibility from source to sink.
- Pipeline Versioning and Collaborative Development: The platform natively supports strict CI/CD deployment principles and pipeline versioning via the IOblend Designer, allowing teams to track code changes and safely replay historical data transforms.
- Real-Time Governance & Drift Handling: IOblend features out-of-the-box Change Data Capture (CDC) and instantaneous schema drift monitoring. If changes happen, they do not fail quietly; you see exactly what was impacted down to individual records.
- Advanced Error Management: Out-of-the-box data validation and exception handling isolate anomalies into secure quarantine zones for immediate SME review.
Standardise your data governance and build production-ready, auditable pipelines with ease.

Digital Twin Evolution: Big Data & AI with
The Industrial Renaissance: How Agentic AI and Big Data Power the Self-Optimising Digital Twin 🏭 Did You Know? A fully realised industrial Digital Twin, underpinned by real-time data, has been proven to reduce unplanned production downtime by up to 20%. The Digital Twin Evolution
Real-Time Risk Modelling with Legacy & Modern Data
Risk Modelling in Real-time: Integrating Legacy Oracle/HP Underwriting Data with Modern External Datasets 💼 Did you know that in the time it takes to brew a cup of tea, a real-time risk model could have processed enough data to flag over
Unify Clinical & Financial Data to Cut Readmissions
Clinical-Financial Synergy: The Seamless Integration of Clinical and Financial Data to Minimise Readmissions 🚑 Did You Know? Unnecessary hospital readmissions within 30 days represent a colossal financial burden, often reflecting suboptimal transitional care. Clinical-Financial Synergy: The Seamless Integration of Clinical and Financial