
Compliance-Friendly DataOps: Repeatable, Reviewable, Versioned Pipelines
📓 Did you know? According to industry compliance reports, nearly 70% of businesses face difficulties tracing their data back to its raw origins during regular regulatory audits.
The Concept of Compliance-Friendly DataOps
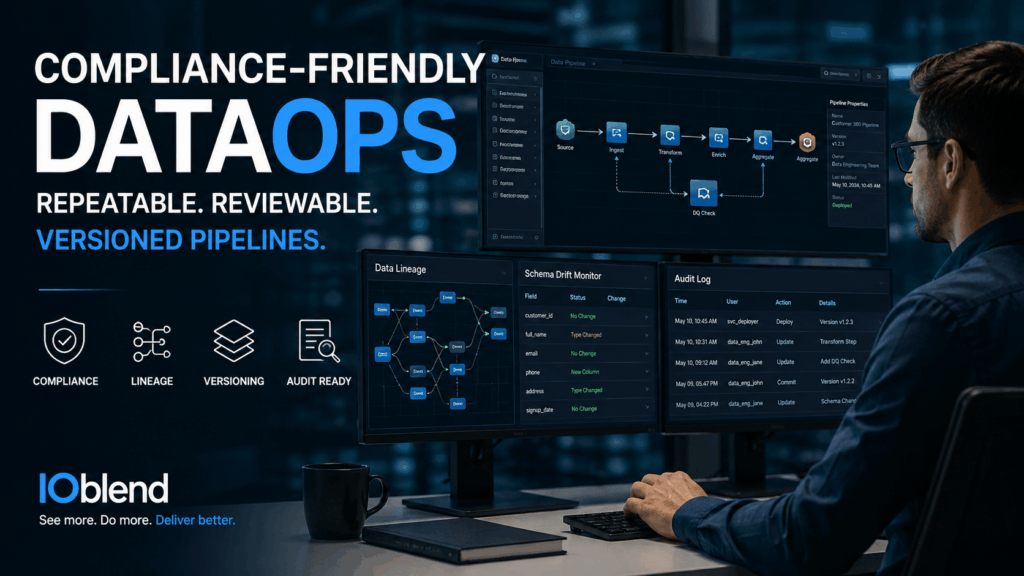
Compliance-friendly DataOps represents an operational framework that embeds strict regulatory governance directly into the data engineering lifecycle. Instead of treating data auditing as an afterthought, this methodology ensures that data transformation pipelines are systematically repeatable, fully reviewable, and meticulously versioned. In practice, this means every single record can be traced back to its precise source code state and ingestion window.
Fragmented Pipelines and the Cost of Chaos
Modern enterprise data architectures are frequently crippled by structural drift and opaque processing layers. Data experts regularly battle with fragmented workflows where a sudden upstream schema change completely breaks downstream analytics without warning.
When a financial institution or healthcare provider is asked to explain a specific metric to an auditor, they are forced into a scramble of manual code inspection, database log reconstruction, and speculative debugging.
Consider a real-world use case in banking risk assessment. If a machine learning model flags an account based on transformed streaming data, compliance requires absolute reproducibility. Without pipeline versioning, reproducing the exact state of that data from three months ago is practically impossible.
The IOblend Solution
Designed as an advanced end-to-end data integration application with native DataOps capability, IOblend standardises production data pipelines on Apache Spark as portable JSON and Python playbooks.
IOblend resolves enterprise governance challenges through an array of built-in production features:
- Automated Record-Level Lineage: It registers auditing metadata dynamically across the full data journey, giving experts precise visibility from source to sink.
- Pipeline Versioning and Collaborative Development: The platform natively supports strict CI/CD deployment principles and pipeline versioning via the IOblend Designer, allowing teams to track code changes and safely replay historical data transforms.
- Real-Time Governance & Drift Handling: IOblend features out-of-the-box Change Data Capture (CDC) and instantaneous schema drift monitoring. If changes happen, they do not fail quietly; you see exactly what was impacted down to individual records.
- Advanced Error Management: Out-of-the-box data validation and exception handling isolate anomalies into secure quarantine zones for immediate SME review.
Standardise your data governance and build production-ready, auditable pipelines with ease.

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit Trails 📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur? Understanding migration QA at scale Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands 📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers. The Concept: Stopping Bad Data at the Border Lakehouse Quality Gates are automated,
Automated Data Contracts: Stop Schema Drift
Data Contracts That Stick: Enforce Schema and Expectations Automatically 📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts A data contract is

