Entity Resolution at Scale: Merge Duplicates as Data Moves
Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context.
Entity resolution has traditionally been handled through batch processing. But when data is moving continuously through CDC and event streams, resolving duplicates overnight is no longer enough.
What Is Entity Resolution?
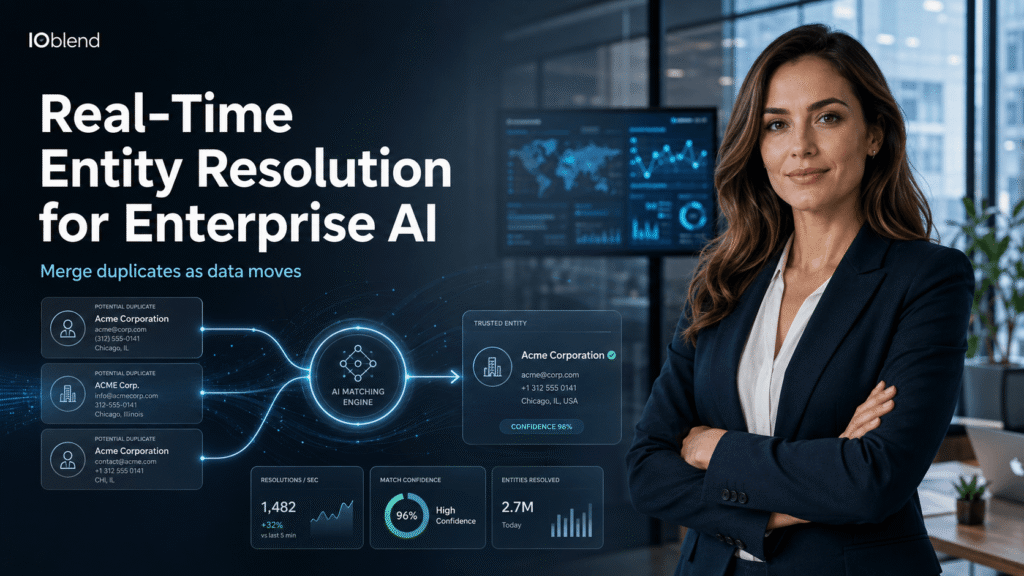
Entity Resolution identifies records that refer to the same real-world entity and links or merges them into a trusted representation.
A CRM may contain “John Smith”, an ERP may store “J Smith”, and a support platform may record “John A. Smith”. At small scale, matching these records is simple. Across millions of continuously changing records, it becomes a significant engineering challenge.
Modern entity resolution needs to combine deterministic rules, fuzzy matching and more advanced logic while maintaining low latency and high throughput.
Why Real-Time Entity Resolution Is Difficult
The challenge is not simply finding a duplicate. Streaming records need to be matched against large volumes of historical data without creating processing bottlenecks.
The system also needs to maintain state. A new event may need to be compared with information that arrived months or years earlier, while customer details, supplier records and product hierarchies continue to change.
Many organisations solve this by combining separate CDC tools, streaming engines, matching services, lookup databases, batch jobs and data-quality platforms. The result is often an architecture that works, but becomes increasingly complex and expensive to maintain.
Resolve Entities Inside the Data Flow
IOblend takes a different approach.
Instead of treating entity resolution as a separate downstream process, IOblend allows matching, deduplication, enrichment and validation to happen directly within the data pipeline.
As data moves between operational systems, Microsoft Fabric, Databricks, Snowflake, applications or AI platforms, IOblend can determine whether a record represents a new entity, an update, a duplicate or an exception requiring further validation.
This turns entity resolution from an occasional clean-up exercise into a continuous data operation.
How IOblend Helps
Powered by Apache Spark, IOblend can process historical data, CDC events and streaming workloads through the same execution layer. Data teams can apply matching and transformation logic using familiar SQL or Python without building a separate architecture for every processing pattern.
Deterministic rules such as customer IDs, email addresses, telephone numbers, product codes and composite business keys can be applied directly in the pipeline. More complex records can also be enriched, normalised or validated using AI-assisted processing where ambiguity exists.
Duplicate or invalid records can be merged, corrected or quarantined before they reach reporting, applications or AI systems.
IOblend can also support Slowly Changing Dimension patterns, including SCD Type I and Type II, helping organisations maintain trusted current records while preserving historical changes where required.
Keep Your Existing Data Platform
Entity resolution should not require another major platform migration.
IOblend works across existing environments including Microsoft Fabric, Databricks, Snowflake, databases, ERP platforms, CRM systems, APIs and event sources.
The objective is not to create another storage layer. It is to improve the quality of data while it is already moving between systems.
Entity Resolution Is Becoming an AI Requirement
AI systems are only as reliable as the entities behind their data.
An AI assistant cannot build an accurate customer view if one person exists as multiple disconnected records. An AI agent should not make supplier decisions from duplicate vendor profiles. Analytics cannot calculate customer value correctly if activity is divided across several identities.
Entity resolution is therefore becoming an important part of AI readiness.
The goal is not simply fewer duplicates. It is a continuously trusted view of the business.
One customer. One supplier. One product. One entity downstream systems can rely on.
With IOblend, entity resolution becomes part of the data flow itself, combining streaming integration, CDC, data quality, governance and AI-assisted processing within one execution layer.
Trusted data while it moves. Ready for analytics, automation and AI.

Agentic Pipelines and Real-Time Data with Guardrails
The New Era of ETL: Agentic Pipelines and Real-Time Data with Guardrails For years, ETL meant one thing — moving and transforming data in predictable, scheduled batches, often using a multitude of complementary tools. It was practical, reliable, and familiar.
Real-Time Insurance Claims with CDC and Spark
From Batch to Real-Time: Accelerating Insurance Claims Processing with CDC and Spark 💼 Did you know? In the insurance sector, the move from overnight batch processing to real-time stream processing has been shown to reduce the average claims settlement time
Agentic AI: The New Standard for ETL Governance
Autonomous Finance: Agentic AI as the New Standard for ETL Governance and Resilience 📌 Did You Know? Autonomous data quality agents deployed by leading financial institutions have been shown to proactively detect and correct up to 95% of critical data quality