
IOblend and Hitachi Pentaho are both advanced data integration platforms that cater to the growing needs of businesses. They both operate in the data integration domain but differ in architecture design, features and cost.
Here’s an overview of their capabilities:
Real-time Data Integration
IOblend:
- Supports true real-time, production-grade data pipelines using Apache Spark with proprietary tech enhancements to enable extremely efficient data processing at scale (>10m transactions per sec).
- Can integrate equally streaming (transactional event) and batch data due to its Kappa architecture with full CDC capabilities.
Pentaho:
- Hitachi Pentaho, while offering real-time data integration (can use Spark), leans more towards traditional ETL processes (Kettle).
- Using its data integration tools, users can set up complex transformations, orchestrations, and workflows that cater to both real-time and batch processing requirements.
Low-code/No-code Development
IOblend:
- Provides low-code/no-code development, facilitating quicker data migration and minimization of manual data wrangling. No requirement to have Spark expertise. Just apply SQL and Python for business logic.
Pentaho:
- Features a drag-and-drop designer which makes it easy to design ETL workflows without extensive coding. The platform is designed to be user-friendly, even for those who aren’t experts in data integration.
Data Architecture
- Allows businesses to choose between centralized (where all data is processed and stored centrally) and federated (distributed processing and storage) architectures, providing flexibility based on business needs.
- IOblend offers unparalleled flexibility for data engineering. It equally supports ETL/ELT/rETL to allow for any strategy: in-memory transforms, in-warehouse transforms, push data back to the apps – all can be handled in the same pipeline.
Pentaho:
- Operates largely on a modular and plugin-based architecture. This allows users to expand its capabilities as needed.
- While it can support both ETL and ELT, Pentaho’s design leans more towards the ETL approach, capitalizing on its robust transformation capabilities.
Performance & Scalability
IOblend:
- Boasts low-latency, massively parallelized data processing with speeds exceeding 10 million transactions per second.
- Data syncing in true real-time with unlimited window sizes and automatic regressions.
- No limit on the amount of data that can be processed – automatically scales with infrastructure. Uses proprietary optimisation layers to boost compute efficiency and reduce cost.
Pentaho:
- Ensures performance optimization through its adaptive execution layer, which allows transformations to run anywhere – from the source server to the target platform or in a data cluster. Its scalability features ensure that as data volumes grow, performance is not compromised.
Partnerships & Cloud Integration
IOblend:
- Has real-time integration capabilities with Snowflake, AWS, Google Cloud and Azure products and is an ISV technology partner with Snowflake and Microsoft.
Pentaho:
- Pentaho has a vast array of connectors and integration capabilities with various databases, cloud platforms, and big data solutions. Its compatibility is one of its strong suits, ensuring it can connect with various data sources and targets.
User Interface & Design
IOblend:
- Consists of two main components: IOblend Designer and IOblend Engine, facilitating design and execution respectively.
- IOblend Designer is a visual interface for fast pipeline development and testing using a drag-and-drop approach
Pentaho:
- Pentaho’s interface is intuitive and user-centric, providing a holistic platform for setup, monitoring, and error handling. Its visual tools simplify complex integration tasks.
Data Management & Governance
IOblend:
- Ensures data integrity with features like automatic record-level lineage, CDC, SCD, metadata management, de-duping, cataloguing, compaction, schema drifts, windowing, regressions, eventing, late-arriving data, etc. integrated in every data pipeline.
- Connects to any data source via ESB/API/JDBC/flat files, both batch and real-time streaming (inc. JDBC) with CDC (supports all three log, trigger and query based).
Pentaho:
- Pentaho places emphasis on data quality and governance, offering features like data profiling, validation, and lineage tracking. Its data services layer ensures unified and consistent data delivery.
Cost & Licensing
IOblend:
- The Developer Edition is free, while the Enterprise Edition requires a paid annual license (unlimited users/usage) that includes training and support.
Pentaho:
- Pentaho’s pricing model is based on a combination of server cores, data volumes, and user roles. It offers flexibility to cater to both small businesses and large enterprises.
Deployment & Flexibility
IOblend:
- Deploys fully inside the customer environments: on-prem, cloud and hybrid, residing entirely inside the client’s security net.
- Flexibility to be fully managed or self-managed, and any combination of the two.
Pentaho:
- Pentaho supports on-premises, cloud, and hybrid deployments, allowing businesses to choose based on their infrastructure needs.
Community & Support
IOblend:
- Being relatively new, its community is still burgeoning. Provides online support for Developer Edition and premium support for Enterprise Edition.
Pentaho:
- Pentaho benefits from a mature and vibrant community. With extensive documentation, tutorials, webinars, and dedicated support, users are well-guided through any challenges.
In essence, IOblend is a data pipeline accelerator, offering all engineering, management and governance capabilities as part of a single tool. IOblend was designed to be flexible and cost effective and is thus suitable for a wide range of data integration initiatives (including aging legacy systems, syncing data cross multiple systems, and powering real-time apps and products), data migration projects and data exchanges. It works equally well with real-time events and batch data of any size and complexity, requiring no coding beyond the business rules (defined in SQL or Python).
Hitachi Pentaho is a comprehensive data integration and business intelligence platform designed to help organizations aggregate, prepare, and analyse data from various sources. Its suite of tools allows for data extraction, transformation, and loading (ETL), as well as advanced data analytics, visualization, and reporting capabilities. Businesses use Hitachi Pentaho to gain insights from their data, optimize operations, and make informed decisions. The platform supports a wide range of data sources, from traditional databases to big data solutions and cloud services, ensuring flexibility and scalability for diverse enterprise needs.
The best fit depends on an organization’s specific needs, existing infrastructure, and future goals.

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
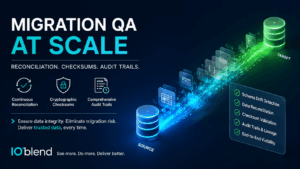
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit Trails 📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur? Understanding migration QA at scale Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands 📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers. The Concept: Stopping Bad Data at the Border Lakehouse Quality Gates are automated,
Automated Data Contracts: Stop Schema Drift
Data Contracts That Stick: Enforce Schema and Expectations Automatically 📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts A data contract is
