
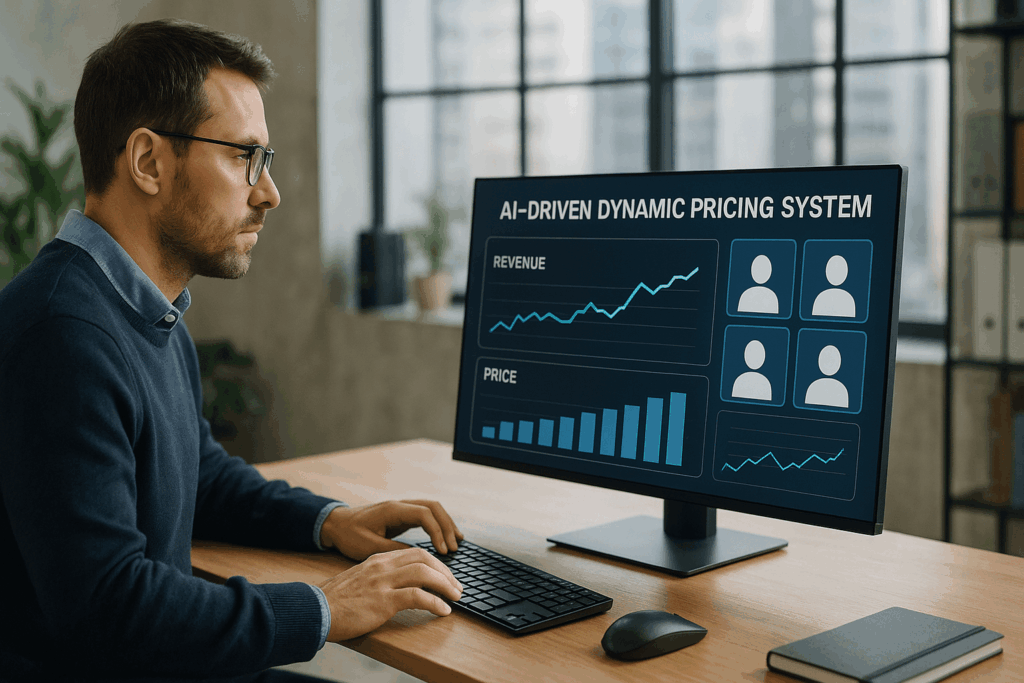
The Agentic Edge: Real-Time Dynamic Pricing through AI-Driven Cloud Data Integration
📊 Did You Know? The most sophisticated dynamic pricing systems can process and react to market signals in under 100 milliseconds.
The Evolution of Value Optimisation
Dynamic Pricing and Revenue Management (DPRM) is a complex computational science. At its core, DPRM aims to sell the right product to the right customer at the right time for the right price. In the age of hyperscale cloud computing, DPRM systems must move beyond simple rule-based algorithms to embrace Agentic AI. These agents operate autonomously within data pipelines, orchestrating complex tasks like scraping competitor data, cleaning historical booking logs, and automatically training or refreshing pricing models based on observed market shifts.
The Integration Imperative: Complexity and Constraint
For businesses, the shift to Agentic AI-driven DPRM exposes critical failures in traditional data pipelines. The challenge isn’t the predictive model itself; it is the data integration imperative: feeding that model with fresh, trustworthy, and governed data at scale.
- Real-Time Data Velocity: DPRM demands low-latency feature engineering. When a competitor changes a price or inventory drops suddenly, the system must react in milliseconds, not minutes.
- Data Governance and Lineage: Pricing decisions are high-stakes and regulated. Organisations need record-level lineage, ensuring every price adjustment can be traced back to its specific source inputs. Without this, compliance becomes impossible.
- Scaling and Cost: Integrating high-volume, continuous data streams from various sources (APIs, CDC logs, cloud data lakes) requires massively parallel processing, typically via frameworks like Apache Spark.
Solving the Data Challenge with IOblend
The IOblend software is engineered to directly solve the data integration complexities that cripple enterprise dynamic pricing initiatives. By embedding Agentic AI into the ETL process, IOblend allows the developers to transform raw, siloed data into high-quality, real-time features – ready for making split-second decisions.
- Real-Time Performance: Utilising a Kappa-based architecture, IOblend seamlessly blends streaming and batch data, delivering ultra-low P99 latency and scaling to over a million transactions per second. This speed ensures that competitor moves and booking spikes are captured and reflected in the pricing model instantly.
- Automation and Governance: IOblend automates critical DataOps tasks, including Change Data Capture (CDC), schema drift detection, error handling, and record-level lineage. This is vital for DPRM, as it guarantees data quality and provides the full audit trail required for compliance.
- Cost Efficiency and Flexibility: IOblend’s proprietary Engine automatically manages and optimises Spark pipelines, often reducing infrastructure cost by up to 50% compared to manually engineered Spark deployments.
Unleash maximum revenue velocity with IOblend’s Agentic AI-powered data integration.
IOblend presents a ground-breaking approach to IoT and data integration, revolutionizing the way businesses handle their data. It’s an all-in-one data integration accelerator, boasting real-time, production-grade, managed Apache Spark™ data pipelines that can be set up in mere minutes. This facilitates a massive acceleration in data migration projects, whether from on-prem to cloud or between clouds, thanks to its low code/no code development and automated data management and governance.
IOblend also simplifies the integration of streaming and batch data through Kappa architecture, significantly boosting the efficiency of operational analytics and MLOps. Its system enables the robust and cost-effective delivery of both centralized and federated data architectures, with low latency and massively parallelized data processing, capable of handling over 10 million transactions per second. Additionally, IOblend integrates seamlessly with leading cloud services like Snowflake and Microsoft Azure, underscoring its versatility and broad applicability in various data environments.
At its core, IOblend is an end-to-end enterprise data integration solution built with DataOps capability. It stands out as a versatile ETL product for building and managing data estates with high-grade data flows. The platform powers operational analytics and AI initiatives, drastically reducing the costs and development efforts associated with data projects and data science ventures. It’s engineered to connect to any source, perform in-memory transformations of streaming and batch data, and direct the results to any destination with minimal effort.
IOblend’s use cases are diverse and impactful. It streams live data from factories to automated forecasting models and channels data from IoT sensors to real-time monitoring applications, enabling automated decision-making based on live inputs and historical statistics. Additionally, it handles the movement of production-grade streaming and batch data to and from cloud data warehouses and lakes, powers data exchanges, and feeds applications with data that adheres to complex business rules and governance policies.
The platform comprises two core components: the IOblend Designer and the IOblend Engine. The IOblend Designer is a desktop GUI used for designing, building, and testing data pipeline DAGs, producing metadata that describes the data pipelines. The IOblend Engine, the heart of the system, converts this metadata into Spark streaming jobs executed on any Spark cluster. Available in Developer and Enterprise suites, IOblend supports both local and remote engine operations, catering to a wide range of development and operational needs. It also facilitates collaborative development and pipeline versioning, making it a robust tool for modern data management and analytics

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit Trails 📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur? Understanding migration QA at scale Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands 📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers. The Concept: Stopping Bad Data at the Border Lakehouse Quality Gates are automated,
Automated Data Contracts: Stop Schema Drift
Data Contracts That Stick: Enforce Schema and Expectations Automatically 📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts A data contract is

