
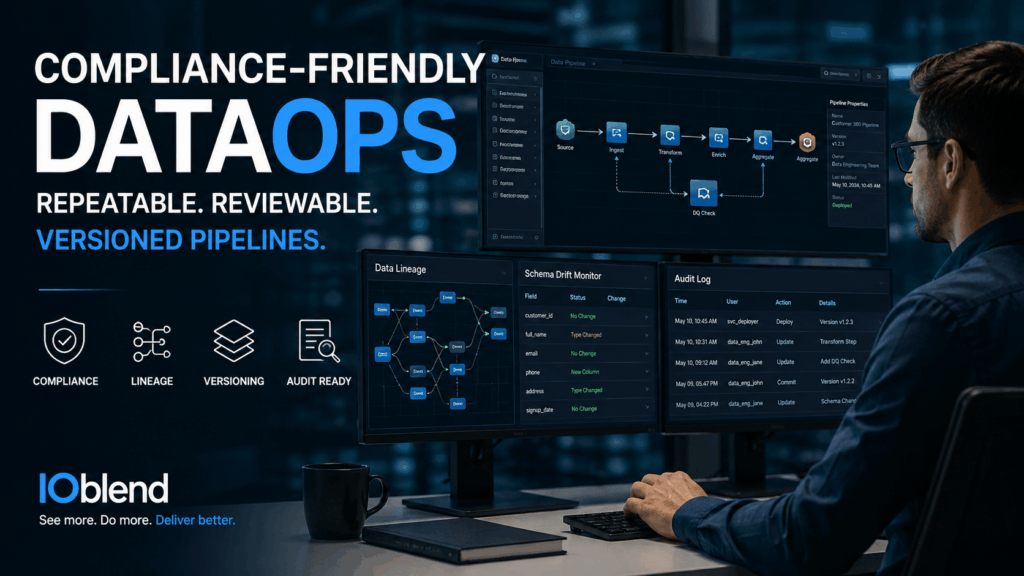
Compliance-Friendly DataOps: Repeatable, Reviewable, Versioned Pipelines
📓 Did you know? According to industry compliance reports, nearly 70% of businesses face difficulties tracing their data back to its raw origins during regular regulatory audits.
The Concept of Compliance-Friendly DataOps
Compliance-friendly DataOps represents an operational framework that embeds strict regulatory governance directly into the data engineering lifecycle. Instead of treating data auditing as an afterthought, this methodology ensures that data transformation pipelines are systematically repeatable, fully reviewable, and meticulously versioned. In practice, this means every single record can be traced back to its precise source code state and ingestion window.
Fragmented Pipelines and the Cost of Chaos
Modern enterprise data architectures are frequently crippled by structural drift and opaque processing layers. Data experts regularly battle with fragmented workflows where a sudden upstream schema change completely breaks downstream analytics without warning.
When a financial institution or healthcare provider is asked to explain a specific metric to an auditor, they are forced into a scramble of manual code inspection, database log reconstruction, and speculative debugging.
Consider a real-world use case in banking risk assessment. If a machine learning model flags an account based on transformed streaming data, compliance requires absolute reproducibility. Without pipeline versioning, reproducing the exact state of that data from three months ago is practically impossible.
The IOblend Solution
Designed as an advanced end-to-end data integration application with native DataOps capability, IOblend standardises production data pipelines on Apache Spark as portable JSON and Python playbooks.
IOblend resolves enterprise governance challenges through an array of built-in production features:
- Automated Record-Level Lineage: It registers auditing metadata dynamically across the full data journey, giving experts precise visibility from source to sink.
- Pipeline Versioning and Collaborative Development: The platform natively supports strict CI/CD deployment principles and pipeline versioning via the IOblend Designer, allowing teams to track code changes and safely replay historical data transforms.
- Real-Time Governance & Drift Handling: IOblend features out-of-the-box Change Data Capture (CDC) and instantaneous schema drift monitoring. If changes happen, they do not fail quietly; you see exactly what was impacted down to individual records.
- Advanced Error Management: Out-of-the-box data validation and exception handling isolate anomalies into secure quarantine zones for immediate SME review.
Standardise your data governance and build production-ready, auditable pipelines with ease.

Streaming Deduplication for Exactly-Once Outcomes
Deduplicate Streaming Events: Exact-Once Outcomes in Real Life 📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads. Understanding exact-once outcomes In real-time data engineering, achieving “exactly-once” outcomes does not mean a message is transported across the wire only once, distributed
Visual Debugging for Apache Spark Streams
Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration 📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory, traditional breakpoints and step-through debugging are impossible without stopping the entire world, corrupting states, and
Ship AI-Ready Data Products Faster
Build a “Data Product” in Days: Reusable Pipeline Playbooks 📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority of their time building the same structural boilerplate over and over again. What are reusable
Schema Evolution with Strong Data Contracts
Schema Evolution Without Chaos: Strong Data Contracts Enforced In Pipelines 📋 Did you know? In the early days of big data, a single altered column in a production database could trigger a catastrophic “data graveyard” effect. The Concept of Schema Evolution Schema evolution is the ability of a data platform to gracefully adapt to structural changes
Mainframe to Cloud: Data Migration with CDC
Mainframe to Cloud: A Practical Data Migration Playbook 💾 Did you know? An alarming 83% of data migrations fail outright or drastically overrun their budgets. Shifting Mainframe Heavyweights to the Cloud Mainframe-to-cloud data migration is the process of moving core legacy data assets, often stored in rigid formats like DB2, VSAM, or IMS, into modern cloud
Real-Time CDC to Databricks Delta Tables
Realtime Ingestion to Databricks: From Source to Delta Tables 💽 Did you know? According to industry surveys, nearly eighty per cent of an enterprise’s data budget is consumed purely by data integration and upfront data wrangling rather than actual analytics. Defining real-time ingestion Real-time ingestion to Databricks represents the technical evolution from rigid scheduled batch processing

