
AW-10865990051

Metadata Management Made Simple with IOblend

social media, media, board-1989152.jpg

Metadata

In today’s data-driven world, information reigns supreme. Businesses and organizations are constantly seeking ways to extract valuable insights from their data to make informed decisions. One often overlooked but essential aspect of this process is metadata. Metadata is the unsung hero that empowers data management, analytics, and decision-making.

In this blog, we will delve into the world of metadata, exploring what it is, how it is used, why it is crucial, and how IOblend makes it simple to work with metadata.

What is Metadata?

Metadata is “data about data”. It provides essential context and information about a dataset, helping users understand and utilize the data effectively. Metadata includes details such as data source, creation date, author, data format, data lineage, and much more. Think of metadata as a comprehensive catalogue that makes your data organized, searchable, and valuable. Metadata can tell you when, where, how, and by whom a piece of data was created, modified, accessed, or stored. Metadata can also help you find, sort, filter, or analyse data more easily and efficiently.

There are different types of metadata for different purposes and domains.

 Some common types are:

Descriptive metadata – This type of metadata provides information about the content and features of a resource, such as its title, author, subject, keywords, abstract, etc. Descriptive metadata is often used for discovery and identification of resources. For example, the metadata of a book can include its title, author name, publisher, ISBN number, genre, etc.

Structural metadata – This type of metadata describes how a resource is composed or organized, such as its format, layout, hierarchy, sequence, etc. Structural metadata can help users navigate or manipulate a resource. For example, the metadata of a web page can include its HTML tags, CSS stylesheets, links, images, etc.

Administrative metadata – This type of metadata provides information about the management and usage of a resource, such as its creation date, modification date, owner, permissions, location, etc. Administrative metadata can help users control or monitor a resource. For example, the metadata of a file can include its name, size, type, path, checksum, etc.

There are many other types and subtypes of metadata that can be specific to certain fields or applications, such as:

Geospatial metadata – This type of metadata describes the geographic location and features of a resource or data set. It can include coordinates, projections, scales, accuracy, etc.

Statistical metadata – This type of metadata describes the methods and quality of statistical data collection and analysis. It can include definitions, sources, indicators, variables, units, etc.

Legal metadata – This type of metadata describes the legal status and rights of a resource or data set. It can include creator name, copyright holder name, license type and terms, etc.

Metadata can be stored and accessed in various ways depending on the format and system of the data. Some common methods are:

Embedded metadata – This type of metadata is stored within the same file or document as the data itself. It can be in the form of headers, footers, comments, tags, attributes, etc.

External metadata – This type of metadata is stored separately from the data itself. It can be in the form of databases, catalogues, registries, repositories, etc.

How is Metadata Used?

Metadata serves various purposes across the data lifecycle:

Data Discovery: Metadata enables users to find relevant datasets quickly. It acts as a roadmap to locate specific data sources or files.

Data Quality: Metadata tracks data lineage, making it easier to identify and rectify errors or discrepancies in the data. It aids in maintaining data quality and consistency.

Data Governance: Metadata helps enforce data governance policies and ensure compliance with regulations by recording data usage, permissions, and access history.

Data Analytics: Data scientists and analysts rely on metadata to understand the content, structure, and context of data, which is crucial for accurate analysis and modelling.

Data Integration: Metadata simplifies the process of integrating data from multiple sources by providing insights into the schema, transformations, and relationships between datasets.

Why is Metadata Important?

Metadata is the backbone of successful data management and analytics for several reasons:

Data Understanding: It provides the necessary context for interpreting data correctly, reducing the risk of misinterpretation or misuse.

Efficiency: Metadata accelerates data discovery and integration, saving time and resources.

Data Lineage: It ensures data traceability, which is vital for auditing, debugging, and maintaining data quality.

Data Governance: Metadata supports data governance practices, helping organizations maintain control over their data assets.

Collaboration: Metadata facilitates collaboration by making it easier for different teams and individuals to understand and work with shared datasets.

IOblend: Automating Metadata Management

IOblend is an end-to-end enterprise data integration solution that takes metadata management very seriously. IOblend offers true DataOps capabilities by automating various aspects of data pipeline development and management, with a particular focus on metadata handling.

IOblend manages data through its entire journey, including record-level lineage, change data capture (CDC), schema management, eventing, de-duplication, slowly changing dimensions (SCD), cataloguing, regressions, and more. This comprehensive metadata management approach is crucial for successful operational analytics and MLOps.

IOblend empowers data professionals with a low-code solution, making it easy for them to work with data estates while ensuring that metadata is automatically maintained. This democratizes data pipeline development and maintenance, allowing non-engineers to create robust data pipelines.

Real-world Applications of IOblend and Metadata

IOblend is ideally suited for operational analytics cases, where speed, data quality, and reliability are paramount. Here are some real-world applications:

Factory Automation: Streaming live data reliably from factory machinery to automated forecasting models, optimizing operations in real time.

IoT Sensor Data: Flowing data from IoT sensors to real-time monitoring applications that make automated decisions based on live inputs and historical statistics.

Cloud Data Warehousing: Moving production-grade streaming and batch data to and from cloud data warehouses and lakes.

Data Exchanges: Powering data exchanges by ensuring data quality and compliance with strict governance policies.

Complex Business Rules: Feeding applications with data that requires complex business rules and governance policies, ensuring data consistency and reliability.

In conclusion, metadata enables effective data management, analytics, and decision-making. IOblend, with its innovative capabilities and automation simplifies production-grade data pipeline development and maintenance while ensuring data assets are robust and well-documented automatically. In the era of data-driven insights, IOblend and metadata are invaluable allies for organizations seeking to harness the full potential of their data.

Managing metadata, a crucial aspect of data management, involves handling detailed information about data, enhancing its organization, searchability, and utility. Metadata includes various types such as descriptive, structural, administrative, geospatial, statistical, and legal, each serving distinct purposes. It is stored either embedded within data files or externally in databases or catalogues. Metadata plays vital roles in data discovery, quality, governance, analytics, and integration. It acts as a guide to locate specific data sources, tracks data lineage for quality control, enforces governance policies, and aids data scientists in understanding data context for accurate analysis. IOblend simplifies metadata management, streamlining these processes and integrating them into broader data management and analytics frameworks, thereby resolving the complexities associated with metadata management in various data-driven contexts.

Enterpsise-Data-Platform-blog-IOblend
AI
admin

When Enterprise Data Platforms Become Too Complex

When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Read More »
Real-Time-Entity-Resolution-for-Enterprise-AI-IOblend
AI
admin

Real-Time Entity Resolution for Enterprise Data and AI

Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Read More »
Real-Time-Customer-360-MDM-for-AI-Ready-Data-IOblend
AI
admin

Real-Time Customer 360: MDM for AI-Ready Data

Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
Read More »
Migration-QA-at-Scale-Reconciliation-Checksums-and-Audit-Trails
AI
admin

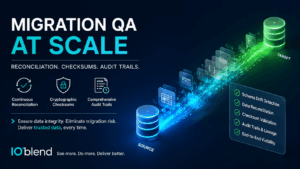
Data Migration QA: Checksums & Audit Trails

Migration QA at Scale: Reconciliation, Checksums, and Audit Trails  📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur?  Understanding migration QA at scale  Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Read More »
Lakehouse-Quality-Gates-Fail-Fast-Before-Bad-Data-Lands-IOblend
AI
admin

Lakehouse Data Quality Gates: Stop Bad Data Fast

Lakehouse Quality Gates: Fail Fast Before Bad Data Lands  📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers.  The Concept: Stopping Bad Data at the Border  Lakehouse Quality Gates are automated,
Read More »
Data-contracts-with-IOblend
AI
admin

Automated Data Contracts: Stop Schema Drift

Data Contracts That Stick: Enforce Schema and Expectations Automatically  📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts  A data contract is

Read More »
Scroll to Top