Zero-Lag Operations: Stream Database Changes to Your LakehouseÂ
💾 Did you know? The “data downtime” caused by traditional batch processing costs the average enterprise approximately ÂŁ12,000 per minute.Â
The Concept: Moving at the Speed of ChangeÂ
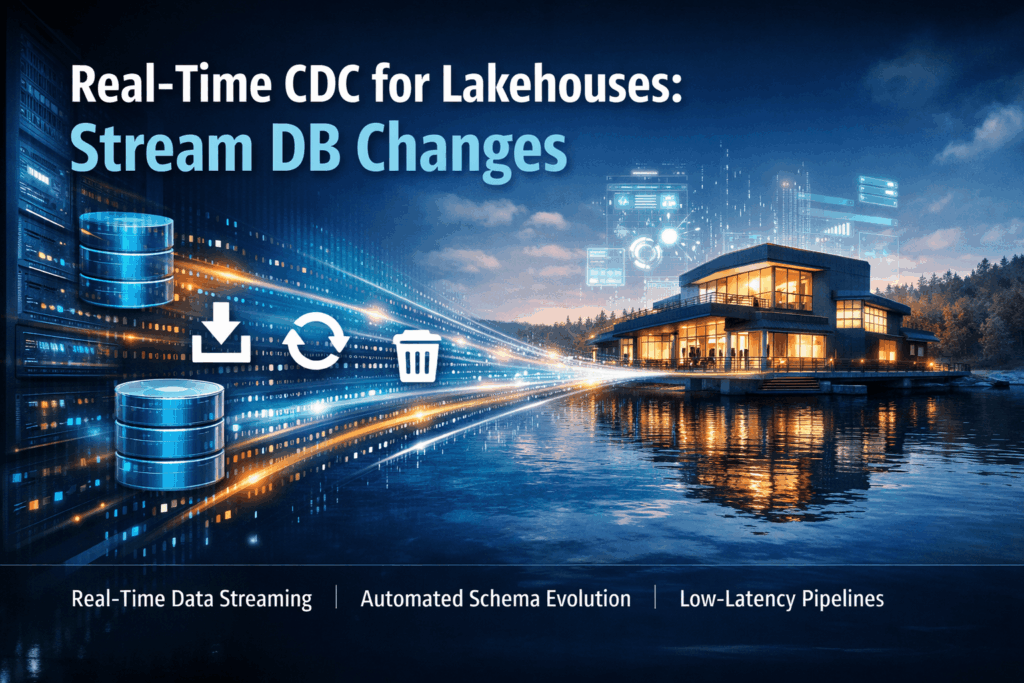
Zero-lag operations rely on a transition from periodic “snapshots” to continuous “streams.” Instead of moving massive blocks of data at midnight, modern architectures capture every insert, update, or delete in a source database the moment it happens. This approach, often powered by Change Data Capture (CDC), ensures that your Data Lakehouse remains a living, breathing mirror of your operational systems. It transforms the Lakehouse from a historical archive into a real-time engine for decision-making.Â
The Friction: Why Legacy Integration FailsÂ
Most organisations still grapple with the “Batch Trap.” Traditional ETL (Extract, Transform, Load) processes are inherently high-latency. When a customer updates their profile or a stock level changes in a relational database, that information often sits stagnant until the next scheduled sync.Â
This delay creates several critical issues:Â
- Stale Insights: Data scientists build models on “yesterday’s news,” leading to inaccurate forecasting.Â
- Operational Fragility: Massive batch windows put immense pressure on source systems, often slowing down production databases during peak hours.Â
- Complex Transformation: Mapping changing relational schemas to a flat Lakehouse structure manually is a recipe for broken pipelines and inconsistent metadata.Â
How IOblend Solves the Latency GapÂ
Bridging the gap between operational databases and a Lakehouse requires more than just a fast pipe; it requires an intelligent execution engine. IOblend addresses these challenges by replacing complex, hand-coded pipelines with a streamlined, “Zero-Lag” framework.Â
- Real-Time Data Streaming: IOblend moves beyond legacy batching, allowing for continuous data flow from any source to your Lakehouse with minimal latency.Â
- Automated Schema Evolution: One of the biggest headaches in database streaming is schema drift. IOblend automatically detects and handles changes in the source database, ensuring your Lakehouse tables stay synchronised without manual intervention.Â
- Advanced Data Engineering: Built on a powerful Spark-based engine, IOblend allows you to perform complex transformations on the fly as data streams in, rather than waiting until it lands.Â
- Multi-Cloud Agility: Whether your Lakehouse sits on Azure, AWS, or GCP, IOblend provides a unified interface to manage these streams, reducing the “vendor lock-in” often found in native cloud tools.Â
Stop waiting for your data to catch up, achieve true operational synchronicity with IOblend.Â

IOblend: Simplifying Feature Stores for Modern MLOps
IOblend: Simplifying Feature Stores for Modern MLOps Feature stores emerged to solve a real challenge in machine learning: managing features across models, maintaining consistency between training and inference, and ensuring proper governance. To meet this need, many solutions introduced new
Rethinking the Feature Store concept for MLOps
Rethinking the Feature Store concept for MLOps Today we talk about Feature Stores. The recent Databricks acquisition of Tecton raised an interesting question for us: can we make a feature store work with any infra just as easily as a
CRM + ERP: Powering Predictive Analytics
The Data-Driven Value Chain: Predictive Analytics with CRM and ERP 📊 Did you know? A study on real-time data integration platforms revealed that organisations can reduce their average response time to supply chain disruptions from 5.2 hours to just 37 minutes. A Unified