Streaming Without the Sting: Data Quality Rules That Never Break the Flow
💻 Did you know? A single minute of downtime in a high-velocity streaming environment can result in the loss of millions of data points, potentially costing a business thousands of pounds in missed opportunities or regulatory fines.
—
Defining Resilient Streaming Quality
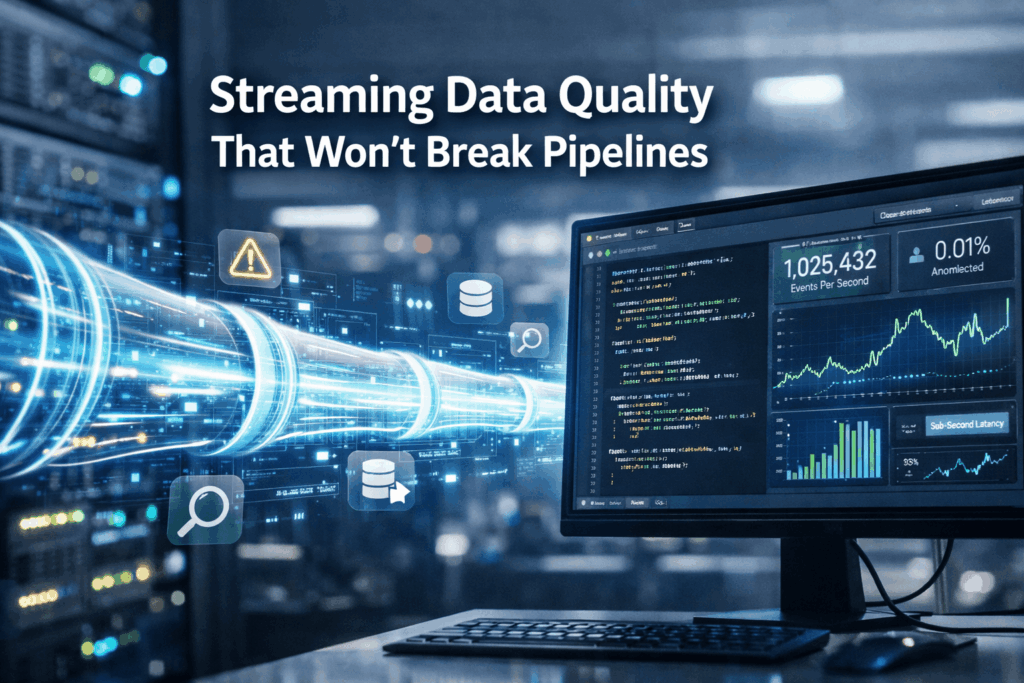
Data quality in a streaming context refers to the continuous validation of data as it moves through a pipeline, ensuring it is accurate, complete, and consistent without pausing the flow. Unlike batch processing, where you can afford to halt a job to investigate a null value, streaming requires a “non-breaking” approach where rules are applied in-flight, allowing valid data to pass while isolating anomalies in real-time.
The Hurdles of Modern Data Streams
Businesses today face significant challenges when trying to maintain high standards of data integrity within live environments:
- Schema Drift: Source systems often change without notice. A new field or a renamed column can instantly crash a traditional Spark job, leading to “silent failures” where data is lost or corrupted.
- Latency vs. Logic: Complex validation rules often introduce lag. For data experts, balancing sophisticated Python or SQL logic with the need for sub-second latency is a constant struggle.
- Tooling Bloat: Many teams “babysit” a five-tool stack just to handle CDC, streaming, and quality audits, leading to high operational overhead and fragmented lineage.
- Scaling Costs: Most vendors charge more as your data volume grows, making high-throughput quality checks prohibitively expensive.
How IOblend Solves the Streaming Puzzle
IOblend is designed to eliminate the fragility of production-grade pipelines by standardising them as portable playbooks. It offers a unique suite of solutions to ensure your data quality rules never break the stream:
- Drift Handling & Lineage: IOblend doesn’t fail quietly. It identifies what changed and what it impacted, providing record-level lineage so you can fix issues without stopping the flow.
- In-Flight Transformations: You can apply custom quality rules using SQL or Python directly within the pipeline. This allows for complex validation at scale (over 1M TPS) without the usual performance penalties.
- Agentic AI ETL: IOblend now allows you to embed AI agents directly into your ETL process. These agents can validate unstructured data or perform intelligent automation in real-time, bridging the gap between raw data and actionable insight.
- Infrastructure Agnostic: Whether on-prem or in the cloud, IOblend runs on your Spark infrastructure, reducing compute costs by up to 50% compared to DIY setups.
Stop rebuilding fragile pipelines and start delivering ROI, turbo-charge your data integration with IOblend today.

The Data Was Right. The Action Was Wrong.
The Data Was Right. The Decision Was Right. The Action Was Still Wrong. I’ve been thinking about one slightly awkward part of Agentic AI. Not hallucinations. Not prompts. Not whether the model is clever enough. Timing. We’ve spent a lot
The Agent Has Permission. Should It Have the Data?
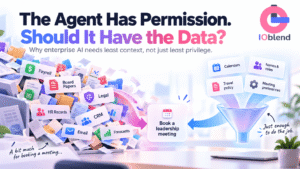
Why least privilege may need a companion: least context Here’s a funny thing about enterprise AI. We spend a lot of time talking about what an agent should be allowed to do, but much less time talking about what it
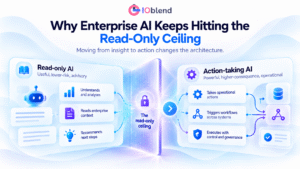
Why Enterprise AI Keeps Hitting the Read-Only Ceiling
The difficult part starts when an agent stops describing the business and starts changing it Enterprise AI has become very good at telling us what it thinks should happen next. It can investigate an incident, review a supplier, classify a