
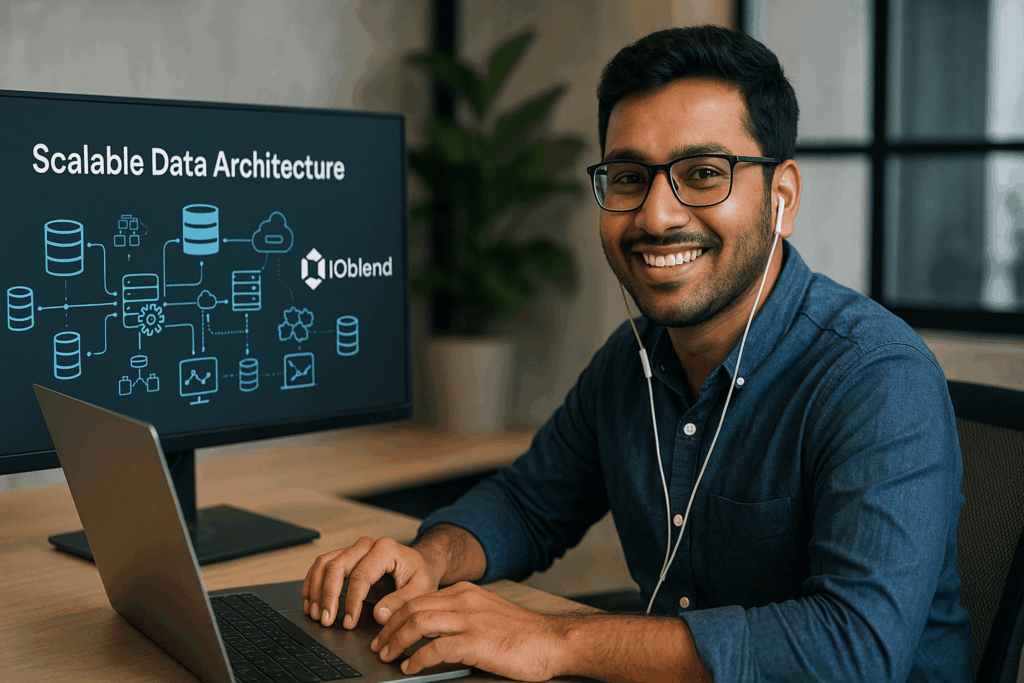
The Data Deluge: Are You Ready?
📰 Did you know? Some modern data centres are being designed with modularity in mind, allowing them to expand upwards – effectively “raising the roof” – to accommodate future increases in data demand without significant structural overhauls.
—
Raising the data roof refers to designing and implementing a data infrastructure that can flexibly and efficiently handle increasing volumes, velocities, and varieties of data, adapting to the growing ambitions and needs of an organisation. It’s about building a system that doesn’t just store data but enables its effective processing, analysis, and utilisation as the business expands.
Fighting the Data
As we move through 2025, we see organisations are now facing an overwhelming surge in data—from customer interactions and IoT devices to digital twins, AI Agents and complex operational systems. Traditional tools and legacy infrastructures simply weren’t built for this scale. We see a lot of issues with scale, data freshness and data quality as the volumes increase. The constant fight to get on top of the data slows down decision-making, increases compliance risks, and limits your ability to extract real value from your data.
Why Scalable Data Architecture Matters
Being able to manage, access and make sense of growing volumes of data is essential for staying competitive. As organisations gather information from a wide range of sources—cloud platforms, connected devices, customer touchpoints, internal systems and third-party services—their data landscape becomes more complex. Without a scalable data architecture in place, it becomes harder to keep up, leading to fragmented systems, sluggish performance and inefficient processes.
A scalable data architecture provides the solid foundation needed to keep pace with growth and change. It enables you to:
- Easily connect new data sources without needing to overhaul existing systems.
- Maintain reliable performance as data volumes and user demands increase.
- Support real-time and batch processing, so data is always timely and usable.
- Harness the power of advanced analytics, including artificial intelligence and machine learning, by ensuring data is accessible, structured and trustworthy.
But scalability isn’t just about capacity—it’s about clarity. With the right architecture, your data—whether structured, semi-structured or unstructured—can be brought together in the way that suits your needs best. This unified view gives you a clearer picture of what’s happening across your organisation, enabling smarter, quicker decision-making and more agile responses to change.
In short, a scalable data architecture helps you do more with your data—unlocking insights, streamlining operations, and setting the stage for future innovation.
How IOblend Empowers You to Master Your Data
IOblend is a comprehensive data integration solution designed to address the exact same complexities of modern data environments. It enables organisations to build, run, scale and manage production-grade data pipelines efficiently, regardless of the underlying data complexity or architecture.
- Accelerated Data Pipeline Development: IOblend significantly reduces the time and resources required to develop data pipelines by automating and simplifying the bulk of the development work.
- Real-Time and Batch Data Handling: IOblend seamlessly manages both batch and low-latency real-time streaming data, making it ideal for various use cases, including data migrations, IoT analytics, and AI initiatives.
- Low/No-Code Development: IOblend offers a user-friendly interface that supports low-code or no-code development, enabling rapid deployment of data pipelines using SQL or Python.
- Built-In DataOps Capabilities: IOblend includes extensive in-built DataOps features, streamlining the data integration lifecycle for efficient data management and governance.
- Versatile Integration: IOblend supports integration with a wide range of data sources and sinks through JDBC, API, ESB, dataframes, or flat files, Agentic AI, offering flexibility in handling data from various origins and destinations.
By leveraging our extensive data capabilities, your organisation can overcome the limitations of traditional data integration methods, achieving faster insights, improved data quality, and enhanced decision-making capabilities. But, crucially, it also allows you to achieve the freedom of designing your data architecture the way it suits your needs best, not succumbing to the limitations of off-the-shelf platforms (legacy or modern alike).
Don’t let your data ambitions be limited by your current data infrastructure. Explore how IOblend can help you build a data roof that scales with your growth.
IOblend presents a ground-breaking approach to IoT and data integration, revolutionizing the way businesses handle their data. It’s an all-in-one data integration accelerator, boasting real-time, production-grade, managed Apache Spark™ data pipelines that can be set up in mere minutes. This facilitates a massive acceleration in data migration projects, whether from on-prem to cloud or between clouds, thanks to its low code/no code development and automated data management and governance.
IOblend also simplifies the integration of streaming and batch data through Kappa architecture, significantly boosting the efficiency of operational analytics and MLOps. Its system enables the robust and cost-effective delivery of both centralized and federated data architectures, with low latency and massively parallelized data processing, capable of handling over 10 million transactions per second. Additionally, IOblend integrates seamlessly with leading cloud services like Snowflake and Microsoft Azure, underscoring its versatility and broad applicability in various data environments.
At its core, IOblend is an end-to-end enterprise data integration solution built with DataOps capability. It stands out as a versatile ETL product for building and managing data estates with high-grade data flows. The platform powers operational analytics and AI initiatives, drastically reducing the costs and development efforts associated with data projects and data science ventures. It’s engineered to connect to any source, perform in-memory transformations of streaming and batch data, and direct the results to any destination with minimal effort.
IOblend’s use cases are diverse and impactful. It streams live data from factories to automated forecasting models and channels data from IoT sensors to real-time monitoring applications, enabling automated decision-making based on live inputs and historical statistics. Additionally, it handles the movement of production-grade streaming and batch data to and from cloud data warehouses and lakes, powers data exchanges, and feeds applications with data that adheres to complex business rules and governance policies.
The platform comprises two core components: the IOblend Designer and the IOblend Engine. The IOblend Designer is a desktop GUI used for designing, building, and testing data pipeline DAGs, producing metadata that describes the data pipelines. The IOblend Engine, the heart of the system, converts this metadata into Spark streaming jobs executed on any Spark cluster. Available in Developer and Enterprise suites, IOblend supports both local and remote engine operations, catering to a wide range of development and operational needs. It also facilitates collaborative development and pipeline versioning, making it a robust tool for modern data management and analytics

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit Trails 📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur? Understanding migration QA at scale Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands 📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers. The Concept: Stopping Bad Data at the Border Lakehouse Quality Gates are automated,
Automated Data Contracts: Stop Schema Drift
Data Contracts That Stick: Enforce Schema and Expectations Automatically 📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts A data contract is

