
Data Contracts That Stick: Enforce Schema and Expectations Automatically
📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed.
The Concept of Enforceable Data Contracts
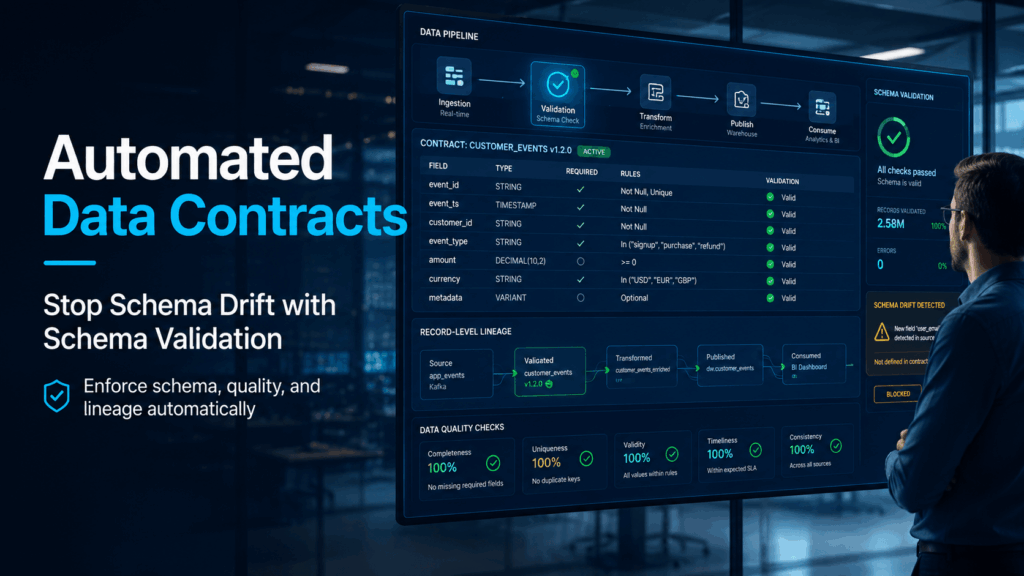
A data contract is an explicit, programmatic agreement between data producers and downstream consumers. It defines expected schemas, data types, freshness, and quality constraints at the pipeline level, guaranteeing that structural evolution occurs safely and predictably without breaking production systems.
The Brittle Reality of Unenforced Schema Drift
As software engineering teams update microservices and operational databases, underlying data structures inevitably shift. Without automated enforcement, this schema drift ripples across modern lakehouses with severe consequences:
- Silent Data Poisoning: Pipelines often do not crash when a column type changes; instead, they ingest malformed records, poisoning clean target tables and corrupting executive dashboards silently.
- Broken Downstream AI/ML Models: In an e-commerce setup, if an upstream team renames `user_zip_code` to `postal_code`, fraud detection algorithms relying on that feature suddenly receive null values, crippling real-time predictions.
- Engineering Fatigue: Data engineers spend up to 70% of their time writing defensive error-handling scripts, firefighting broken runs, and running painful manual backfills.
Automating Contract Enforcement with IOblend
Managing schema evolution and data contracts manually is an uphill battle, but IOblend completely automates this enterprise challenge through built-in DataOps capabilities:
- Dynamic Schema Generation & Versioning: IOblend automatically generates schemas from incoming streams, tracking and versioning structural shifts over time to maintain backward compatibility.
- Automatic Schema Validation: Every incoming batch or stream is checked against predefined contracts prior to ingestion.
- Automated Error Isolation: Rather than crashing the entire pipeline or ingesting corrupted data, invalid records are channelled into dedicated error tables for isolated debugging while valid data continues to flow.
- Record-Level Lineage: In the event of schema drift, IOblend provides complete record-level visibility, letting teams instantly trace what changed, what was impacted, and how to resolve it.
By abstracting away Apache Spark complexity into drag-and-drop, metadata-driven pipelines, IOblend guarantees production-grade data quality without manual overhead.
Eliminate pipeline downtime and secure your data estate with IOblend, where data contracts stick automatically.

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity. More services are added. More specialist skills are needed. More workloads become dependent on one
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation, it creates unreliable context. Entity resolution has traditionally been handled through batch processing. But when
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses adopt AI, copilots and real-time analytics, that gap becomes harder to ignore. Real-time Master Data
Data Migration QA: Checksums & Audit Trails
Migration QA at Scale: Reconciliation, Checksums, and Audit Trails 📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur? Understanding migration QA at scale Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise
Lakehouse Data Quality Gates: Stop Bad Data Fast
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands 📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers. The Concept: Stopping Bad Data at the Border Lakehouse Quality Gates are automated,
Automated Data Contracts: Stop Schema Drift
Data Contracts That Stick: Enforce Schema and Expectations Automatically 📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed. The Concept of Enforceable Data Contracts A data contract is

