Data Contracts That Stick: Enforce Schema and Expectations Automatically
📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of analytics records before anyone noticed.
The Concept of Enforceable Data Contracts
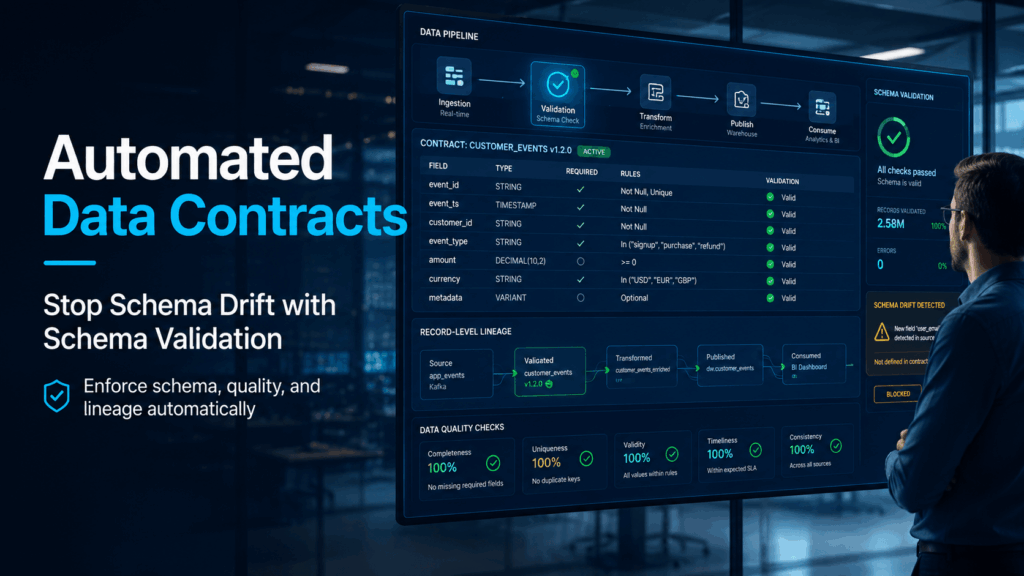
A data contract is an explicit, programmatic agreement between data producers and downstream consumers. It defines expected schemas, data types, freshness, and quality constraints at the pipeline level, guaranteeing that structural evolution occurs safely and predictably without breaking production systems.
The Brittle Reality of Unenforced Schema Drift
As software engineering teams update microservices and operational databases, underlying data structures inevitably shift. Without automated enforcement, this schema drift ripples across modern lakehouses with severe consequences:
- Silent Data Poisoning: Pipelines often do not crash when a column type changes; instead, they ingest malformed records, poisoning clean target tables and corrupting executive dashboards silently.
- Broken Downstream AI/ML Models: In an e-commerce setup, if an upstream team renames `user_zip_code` to `postal_code`, fraud detection algorithms relying on that feature suddenly receive null values, crippling real-time predictions.
- Engineering Fatigue: Data engineers spend up to 70% of their time writing defensive error-handling scripts, firefighting broken runs, and running painful manual backfills.
Automating Contract Enforcement with IOblend
Managing schema evolution and data contracts manually is an uphill battle, but IOblend completely automates this enterprise challenge through built-in DataOps capabilities:
- Dynamic Schema Generation & Versioning: IOblend automatically generates schemas from incoming streams, tracking and versioning structural shifts over time to maintain backward compatibility.
- Automatic Schema Validation: Every incoming batch or stream is checked against predefined contracts prior to ingestion.
- Automated Error Isolation: Rather than crashing the entire pipeline or ingesting corrupted data, invalid records are channelled into dedicated error tables for isolated debugging while valid data continues to flow.
- Record-Level Lineage: In the event of schema drift, IOblend provides complete record-level visibility, letting teams instantly trace what changed, what was impacted, and how to resolve it.
By abstracting away Apache Spark complexity into drag-and-drop, metadata-driven pipelines, IOblend guarantees production-grade data quality without manual overhead.
Eliminate pipeline downtime and secure your data estate with IOblend, where data contracts stick automatically.

Real-Time Defect Detection with Agentic AI + ETL
Smart Quality Control: Embedding Agentic AI into ETL pipelines to visually inspect and categorise production defects 🔩 Did you know? “visual drift” in manual quality control can lead to a 20% drop in defect detection accuracy over a single eight-hour shift The Concept:
Agentic AI ETL for Real-Time Sentiment Pricing
Sentiment-Driven Pricing: Using Agentic AI ETL to scrape social sentiment and adjust prices dynamically within the data flow 🤖 Did you know? A single viral tweet or a trending TikTok “dupe” video can alter the perceived value of a product by
BCBS 239 Compliance with Record-Level Lineage
Regulatory Compliance at Scale: Automating record-level lineage and audit trails for BCBS 239 📋 Did you know? In the wake of the 2008 financial crisis, the Basel Committee found that many global banks were unable to aggregate risk exposures accurately or