AW-10865990051
IOblend Blog

Practical thinking for enterprise data in production.

Data integration, DataOps, real-time architecture and AI-ready data without the platform theatre. We write about the engineering problems that appear when enterprise data has to move, stay current, remain governed and support real operational outcomes.

IOblend - Managed Spark real-time data integration solution. - Page 2

Data-contracts-with-IOblend

Automated Data Contracts: Stop Schema Drift

Data Contracts That Stick: Enforce Schema and Expectations Automatically  📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of
Read More »
Deduplicate Streaming Events IOblend

Streaming Deduplication for Exactly-Once Outcomes

Deduplicate Streaming Events: Exact-Once Outcomes in Real Life  📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads.  Understanding exact-once outcomes  In real-time data engineering, achieving

Read More »
Debugging-for-Apache-Spark-Streams-IOblend

Visual Debugging for Apache Spark Streams

Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration  📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory,

Read More »
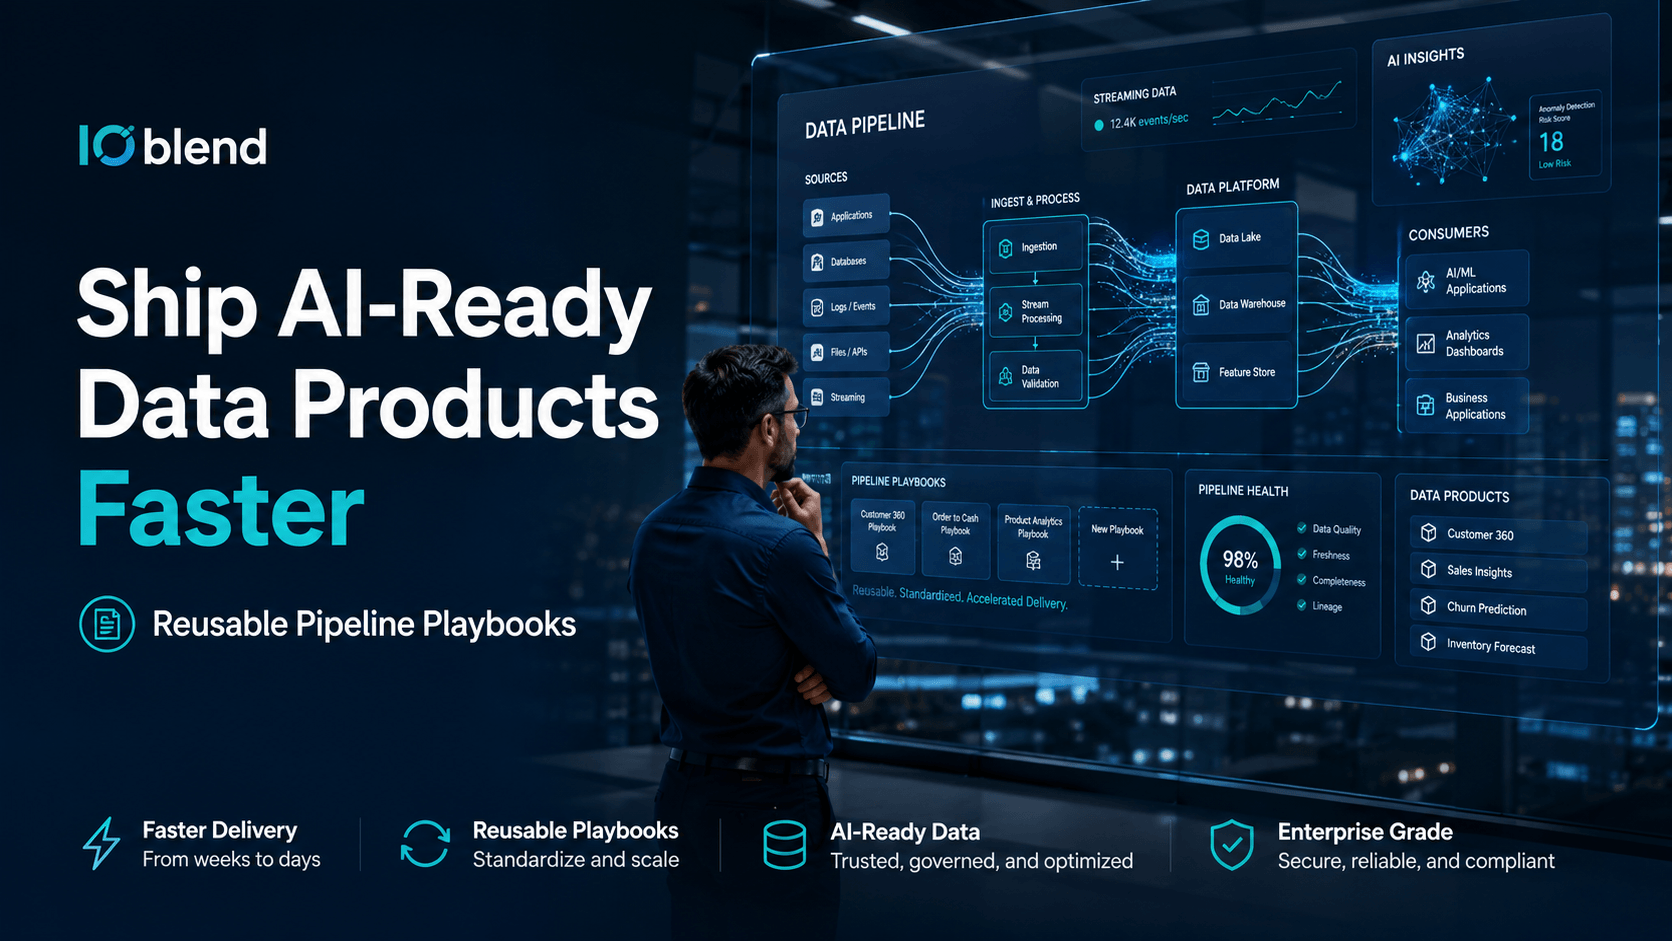
Ship AI-Ready Data Products Faster IOblend

Ship AI-Ready Data Products Faster

Build a “Data Product” in Days: Reusable Pipeline Playbooks  📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority

Read More »
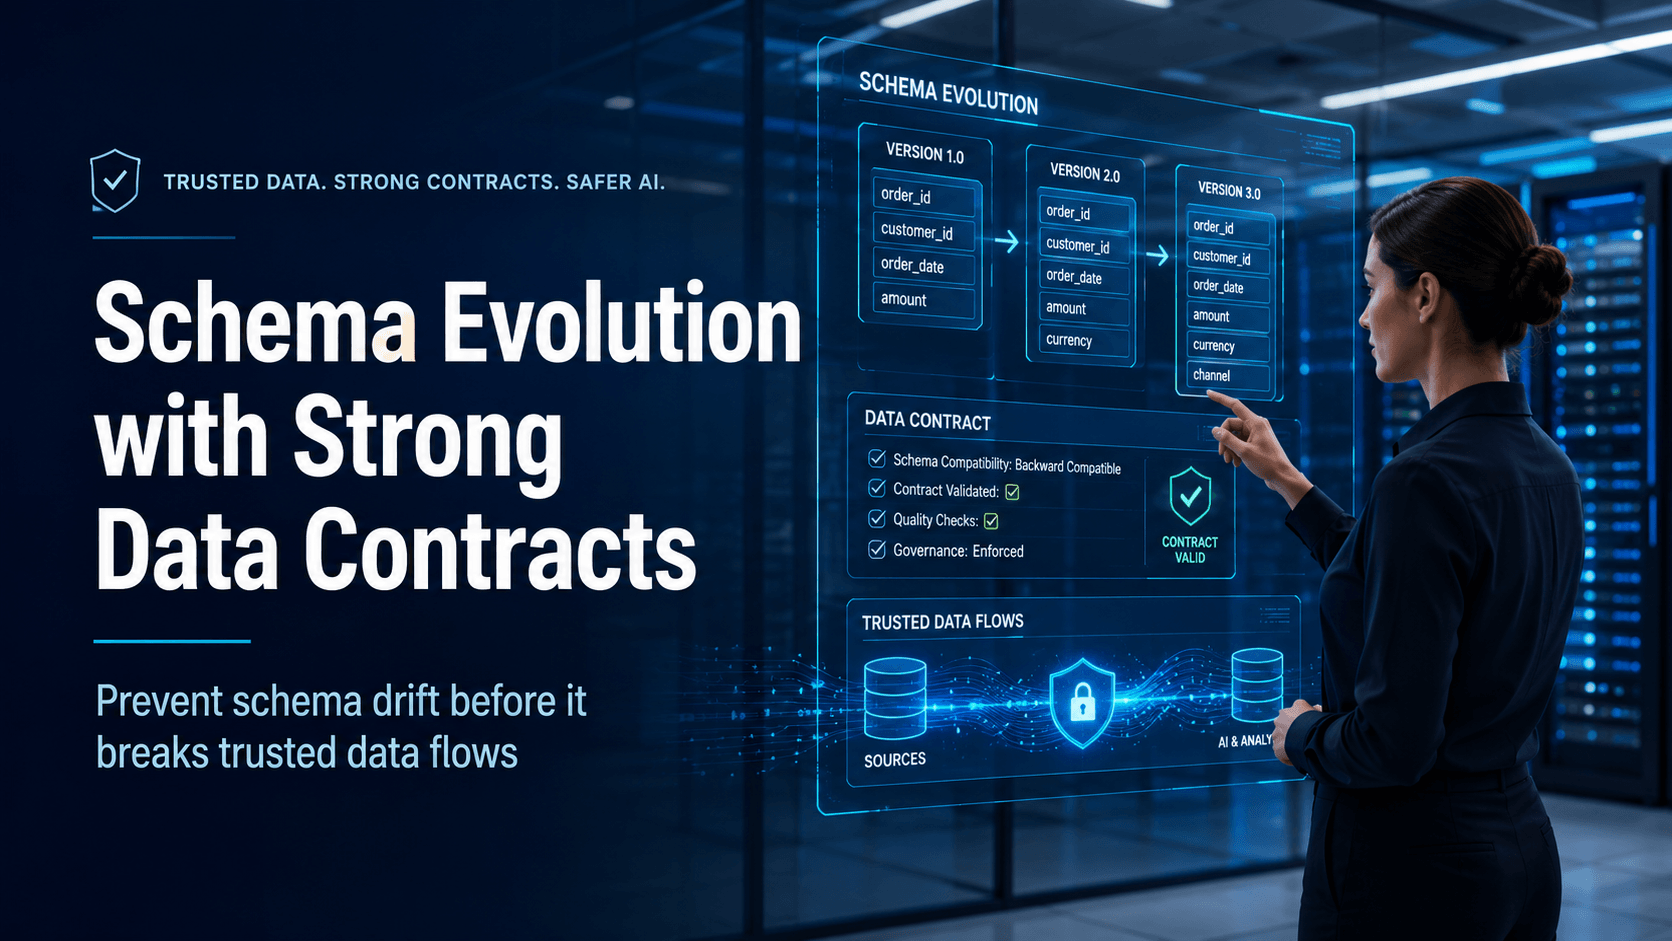
Schema-Evolution-Without-Chaos-Strong-Data-Contracts-Enforced-In-Pipelines

Schema Evolution with Strong Data Contracts

Schema Evolution Without Chaos: Strong Data Contracts Enforced In Pipelines  📋 Did you know? In the early days of big data, a single altered column in a production database could trigger a catastrophic “data graveyard” effect.  The Concept of Schema Evolution 

Read More »
Mainframe-to-Cloud-with-CDC-IOblend

Mainframe to Cloud: Data Migration with CDC

Mainframe to Cloud: A Practical Data Migration Playbook  💾 Did you know? An alarming 83% of data migrations fail outright or drastically overrun their budgets.  Shifting Mainframe Heavyweights to the Cloud  Mainframe-to-cloud data migration is the process of moving core legacy

Read More »
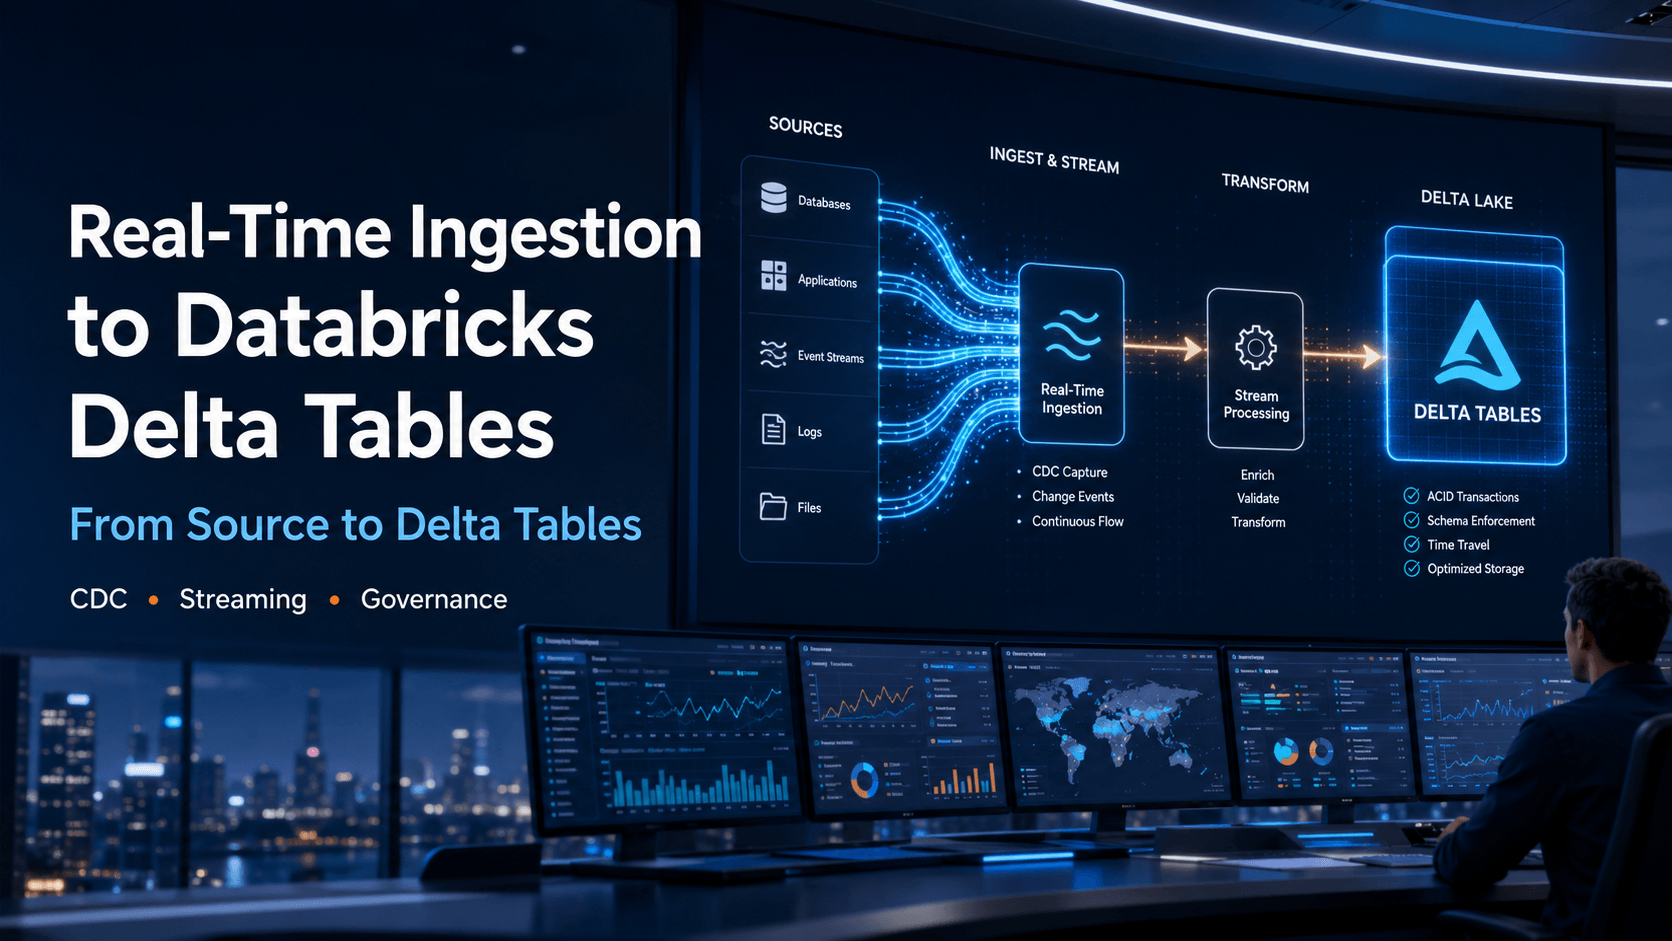
Real-time-CDC-pipelines-into-Delta-tables-IOblend

Real-Time CDC to Databricks Delta Tables

Realtime Ingestion to Databricks: From Source to Delta Tables  💽 Did you know? According to industry surveys, nearly eighty per cent of an enterprise’s data budget is consumed purely by data integration and upfront data wrangling rather than actual analytics.  Defining

Read More »
Scroll to Top