AW-10865990051
IOblend Blog

Practical thinking for enterprise data in production.

Data integration, DataOps, real-time architecture and AI-ready data without the platform theatre. We write about the engineering problems that appear when enterprise data has to move, stay current, remain governed and support real operational outcomes.

IOblend - Managed Spark real-time data integration solution. - Page 4

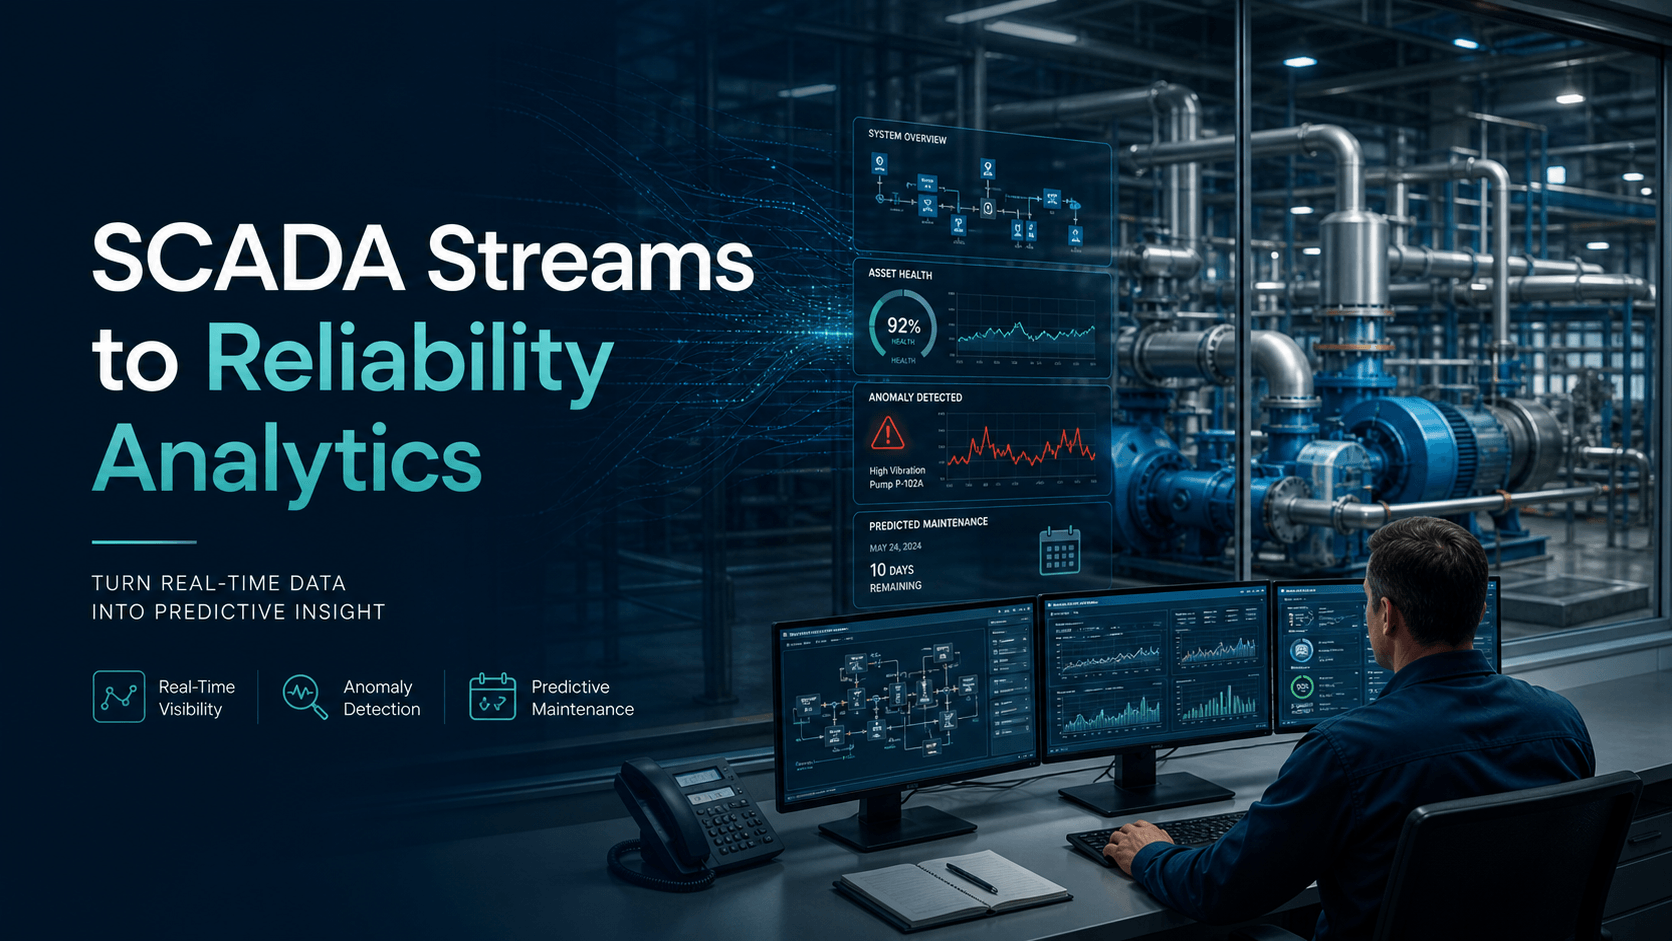
Smart meter billing and AI forecasting with IOblend

Smart Meter Data: Billing to Forecasting

Utilities: Smart Meter Data to Billing and Demand Forecasting  📋 Did You Know? The global roll-out of smart meters generates more data in a single day than most utility companies used to collect in an entire decade. While traditional meters were
Read More »
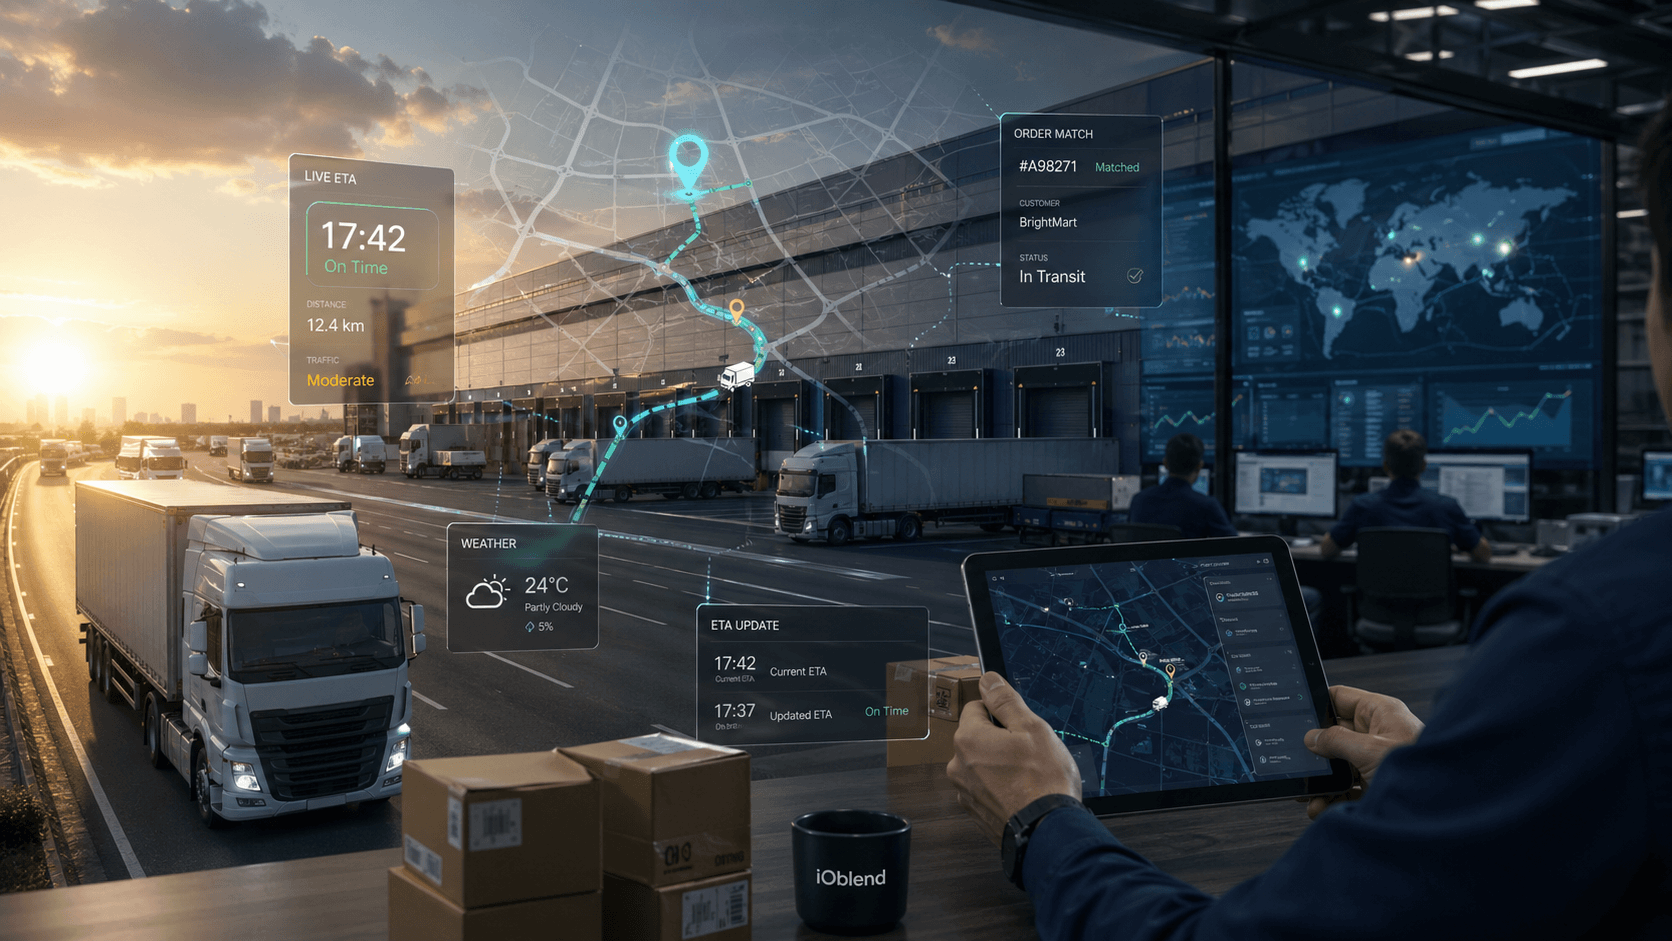
SCADA streams with IOblend

SCADA Streams to Reliability Analytics

Energy: SCADA Streams to Reliability Analytics  🔌 Did you know? The average modern wind turbine or smart substation generates roughly 1 to 2 terabytes of data every month. However, historically, less than 5% of that sensor data was actually used for

Read More »
Logistics operator at a workstation using a tablet with holographic screens showing live ETA, weather, and a route map at a busy distribution hub.

Building Live ETA Pipelines for Fleet Operations

Logistics: Live ETA Prediction Pipelines from Fleet + Orders  🚚 Did you know? The “Last Mile” is famously the most expensive and inefficient part of the supply chain, often accounting for up to 53% of total shipping costs.  The Evolution of

Read More »
DB2-to-Lakehouse-with-CDC-IOblend

DB2 CDC to Lakehouse Without Re-Platforming

From DB2 to Lakehouse: Real-Time CDC Without Re-Platforming  💻 Did you know? Mainframe systems like DB2 still process approximately 30 billion business transactions every single day. Despite the rush toward modern cloud architectures, the world’s most critical financial and logistical data

Read More »
Real-time-data-processing-with-deduplication

Real-Time Upserts: Deduping and Idempotency

Streaming Upserts Done Right: Deduping and Idempotency at Scale  💻 Did you know? In many high-velocity streaming environments, the “same” event can be sent or processed multiple times due to network retries or distributed system failures.  The Art of the Upsert  At its core,

Read More »
schema-drift-handling-with-IOblend

Schema Drift: The Silent Killer of Data Pipelines

The Silent Pipeline Killer: Surviving Schema Drift in the Wild  📊 Did you know? In the early days of big data, a single column change in a source database could trigger a “data graveyard” effect, where downstream analytics remained broken for

Read More »
Scroll to Top