Migration QA at Scale: Reconciliation, Checksums, and Audit Trails
📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur?
Understanding migration QA at scale
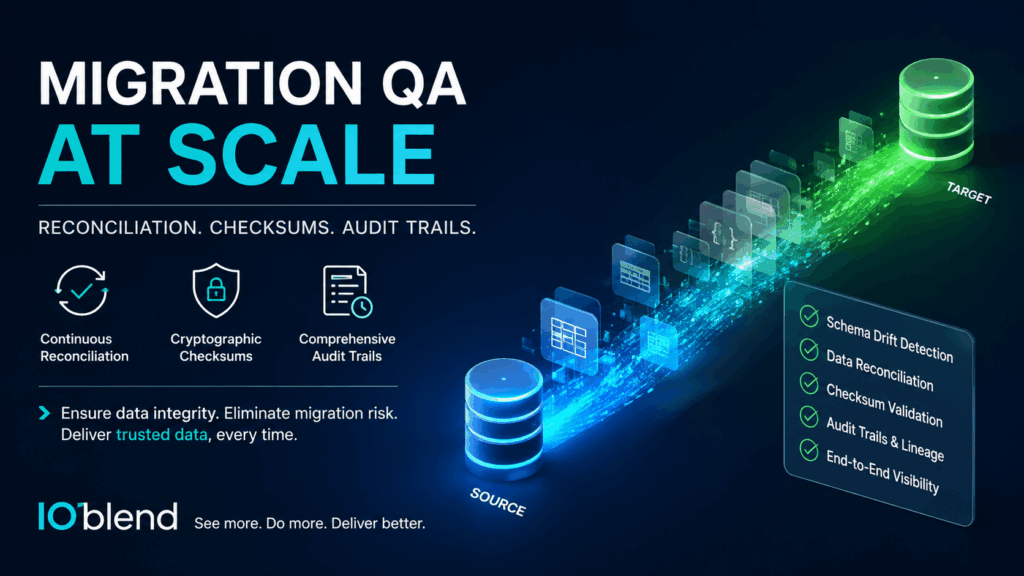
Migration QA at scale refers to the systematic validation of volume, structure, and integrity when shifting enterprise data across heterogeneous environments. Rather than relying on simple row counts, modern reconciliation demands three core pillars: continuous reconciliation to guarantee record symmetry, cryptographic checksums to verify payload fidelity down to individual byte values, and comprehensive audit trails to record end-to-end lineage and schema evolution.
The operational bottlenecks in enterprise migrations
Engineering teams undertaking complex migrations regularly encounter severe operational hurdles:
- Silent schema drift and field truncation: Unannounced schema changes or subtle precision losses (e.g. timestamp truncation or numeric overflow) in active source pipelines corrupt target datasets quietly without throwing fatal job errors.
- Prohibitive compute overhead: Executing full-table hashing or cell-by-cell row comparisons across billions of records introduces unsustainable latency and spikes warehouse consumption costs.
- Lack of record-level lineage: When discrepancies emerge, pinpointing whether the fault stemmed from network drops, transformation logic, or late-arriving CDC records requires painstaking manual log analysis.
- Multi-tool stack complexity: Orchestrating separate tools for batch extracts, streaming CDC, data quality assertions, and logging creates fragile pipelines that fail unexpectedly under high throughput.
Eliminating migration risks with IOblend
IOblend solves these migration QA challenges by standardising production data pipelines on Apache Spark through portable JSON playbooks and native Python/SQL logic.
- Automated continuous reconciliation and line-level lineage: IOblend tracks schema evolution and change data capture in real time (including late-arriving data), delivering record-level lineage so you can trace, debug, and replay discrepancies instantly.
- Cryptographic integrity and high-throughput validation: Capable of processing over 1 million transactions per second with ultra-low P99 latency, IOblend executes validation rules and custom checksum checks directly on Spark infrastructure without heavy warehouse compute costs.
- Unified governance and auditability: Built-in audit trails, automated data quality controls, and drift handling ensure full end-to-end compliance from source to sink across cloud and on-premises environments.
Eliminate migration anxiety and streamline your data pipeline testing. Supercharge your enterprise data migrations with IOblend.

Compliance DataOps for Auditable Pipelines
Compliance-Friendly DataOps: Repeatable, Reviewable, Versioned Pipelines 📓 Did you know? According to industry compliance reports, nearly 70% of businesses face difficulties tracing their data back to its raw origins during regular regulatory audits. The Concept of Compliance-Friendly DataOps Compliance-friendly DataOps represents an operational framework that
Continuous Data Replication for DR and Continuity
Continuous Data Replication: for Business Continuity and DR 📝 Did you know? According to industry studies, the average cost of IT downtime is approximately £4,500 per minute. For a large enterprise, a single hour of data loss or system unavailability can
Smart Meter Data: Billing to Forecasting
Utilities: Smart Meter Data to Billing and Demand Forecasting 📋 Did You Know? The global roll-out of smart meters generates more data in a single day than most utility companies used to collect in an entire decade. While traditional meters were