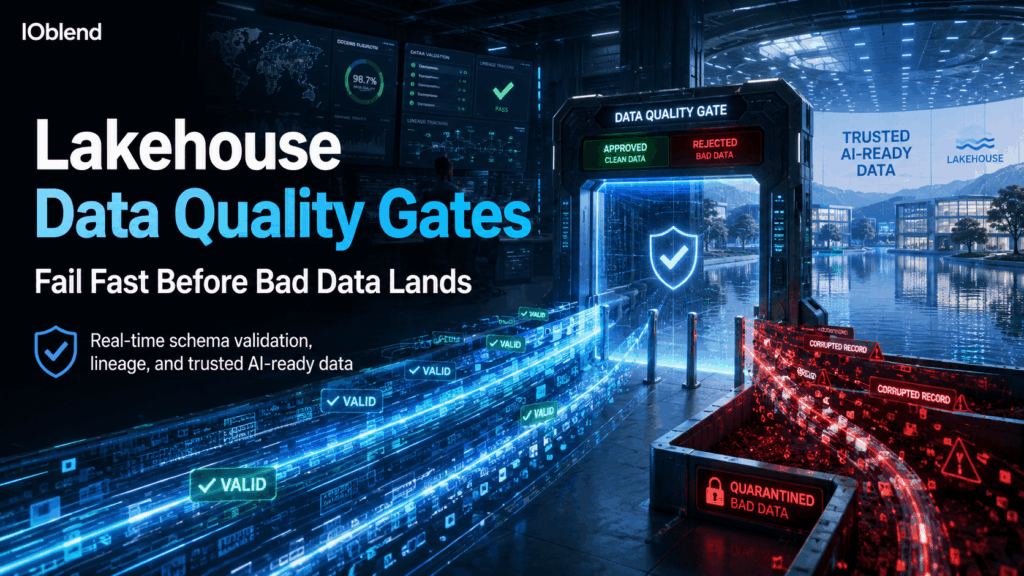
Lakehouse Quality Gates: Fail Fast Before Bad Data Lands
📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted reporting layers.
The Concept: Stopping Bad Data at the Border
Lakehouse Quality Gates are automated, in-flight checkpoints that validate incoming data before it ever touches your Delta Lake, Apache Iceberg, or parquet tables.
Instead of landing messy payloads directly into bronze storage layers and spending expensive warehouse compute on post-hoc cleaning scripts, quality gates enforce schema rules, data types, and business expectations right at the ingestion boundary. If a record violates validation logic, it fails fast, gets quarantined for auditing, and leaves your downstream lakehouse completely pristine.
The Business Challenge: When Trash Lands in the Lake
Allowing unvalidated data to settle into a modern lakehouse creates a destructive blast radius across enterprise data platforms:
- Cascading Pipeline Failures: An upstream application deploy silently changes a JSON field from an integer to a string. Downstream Spark and dbt transformations fail hours later, derailing morning executive dashboards.
- Polluted Machine Learning Models: In MLOps pipelines, corrupted sensor telemetry or altered customer event schemas quietly skew feature stores, causing models to retrain on inaccurate feature vectors.
- Exorbitant Remediation Costs: Data engineers waste up to 70% of their bandwidth untangling schema drift, running manual backfills, and paying heavy cloud compute bills to purge corrupt storage partitions.
The Solution: Enforcing Quality Gates with IOblend
Operating as a next-generation data integration engine on Apache Spark, IOblend executes ultra-low-latency, in-flight data quality checks across real-time CDC, streaming, and batch workflows. Rather than babysitting a complex multi-tool stack, IOblend enables data teams to:
- Enforce Automated Data Contracts: Catch schema drift, missing fields, and type anomalies instantly, quarantining bad events at record level without crashing production streams.
- Maintain Record-Level Lineage & Observability: Track, audit, and debug data flows with built-in lineage, allowing engineers to pause, amend, or replay streams effortlessly.
- Slash Infrastructure Compute Costs: By shifting validation “to the left” before storage, IOblend eliminates unnecessary in-warehouse processing and cuts infrastructure spend by up to 50%.
- Standardise Portable Logic: Build production-grade pipelines using portable JSON playbooks with SQL or Python, scaling seamlessly to over 1,000,000 transactions per second.
Safeguard data products, and achieve full-throttle lakehouse quality with IOblend.

The Agent Has Permission. Should It Have the Data?
Why least privilege may need a companion: least context Here’s a funny thing about enterprise AI. We spend a lot of time talking about what an agent should be allowed to do, but much less time talking about what it
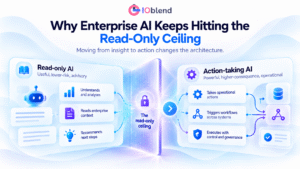
Why Enterprise AI Keeps Hitting the Read-Only Ceiling
The difficult part starts when an agent stops describing the business and starts changing it Enterprise AI has become very good at telling us what it thinks should happen next. It can investigate an incident, review a supplier, classify a
Copilot Agents Need More Than Connectors
Microsoft Copilot is becoming more than a productivity assistant. That is the part many businesses are watching closely. The first wave was about helping users write, summarise, search and move a bit faster. Useful, yes. But not transformational on its