Realtime Ingestion to Databricks: From Source to Delta Tables
💽 Did you know? According to industry surveys, nearly eighty per cent of an enterprise’s data budget is consumed purely by data integration and upfront data wrangling rather than actual analytics.
Defining real-time ingestion
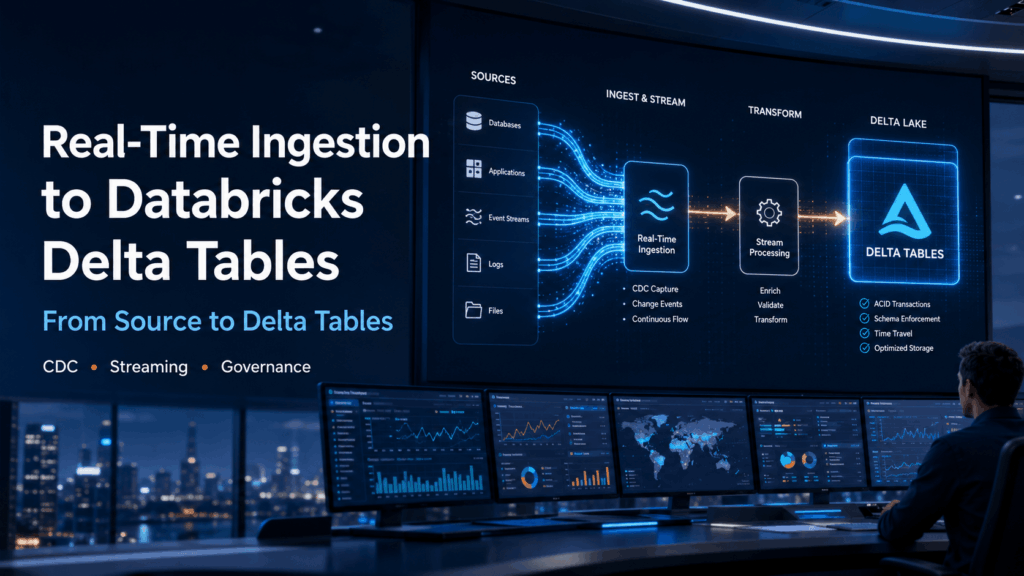
Real-time ingestion to Databricks represents the technical evolution from rigid scheduled batch processing to continuous, event-driven data streaming. At its core, the architecture involves capturing high-velocity data from sources, such as transactional databases via Change Data Capture (CDC), IoT sensors, or application log streams, and immediately driving it into Databricks Delta Tables.
The friction points for modern business
Data teams migrating to continuous lakehouse replication face steep operational hurdles. Traditional ETL stacks rely on multiple disjointed tools to stitch together ingestion, storage, and processing, which creates brittle pipelines that are a nightmare to manage.
The primary business pain points include:
- The “Five-Tool Stack” Complexity: Constantly babysitting separate tools for CDC, stream ingestion, schema drift tracking, and orchestration.
- Schema Drift and Failures: Quiet changes in source database schemas frequently break downstream pipelines, resulting in data downtime.
- Prohibitive Cloud Compute Costs: Poorly optimised Apache Spark clusters running 24/7 to process streaming workloads can cause cloud bills to skyrocket out of control.
Consider a fleet operations enterprise trying to build a live ETA pipeline. If sensor schemas mutate slightly, or if out-of-order data arrives during network drops, manual coding interventions are required, stalling operations.
The IOblend Solution
IOblend redefines this architecture by standardising real-time production pipelines into a single, unified DataOps application built on Kappa architecture. Instead of managing a bloated stack, data experts use the low-code IOblend Designer to build pipelines that automatically generate highly optimised, pure Apache Spark code running behind the scenes.
IOblend directly solves enterprise challenges through:
Massive Performance: Achieving throughput speeds exceeding 1 million transactions per second (TPS) on modest infrastructure, slashing Databricks compute costs by up to seventy per cent.
Built-In Data Governance: Automating record-level lineage, data quality checks, de-duplication, and advanced Change Data Capture (log, trigger, or query-based) within every single flight.
No Vendor Lock-In: Pipelines are stored as portable JSON playbooks, keeping your core SQL and Python business logic independent.
Whether replicating over 400 MySQL tables via continuous CDC or syncing complex smart meter streams to Databricks, IOblend removes the coding burden entirely.
Accelerate your real-time Databricks pipelines from quarters to days with the power of IOblend.

Streaming Predictive MX: Drift-Aware Inference
Predictive Maintenance 2.0: Feeding real-time sensor drifts directly into inference models using streaming engine 🔩 Did you know? The cost of unplanned downtime for industrial manufacturers is estimated at nearly £400 billion annually. Predictive Maintenance 2.0: The Real-Time Evolution Predictive Maintenance
Beyond Micro-Batching: Continuous Streaming for AI
Beyond Micro-batching: Why Continuous Streaming Engine is the Future of “Fresh Data” for AI 💻 Did you know? Most modern “real-time” AI applications are actually running on data that is already several minutes old. Traditional micro-batching collects data into small chunks
ERP Cloud Migration With Live Data Sync
Seamless Core System Migration: The Move of Large-Scale Banking and Insurance ERP Data to a Modern Cloud Architecture ⛅ Did you know that core system migrations in large financial institutions, which typically rely on manual data mapping and validation, often require