Realtime Ingestion to Databricks: From Source to Delta TablesĀ
š½Ā Did you know? According to industry surveys, nearly eighty per cent of an enterprise’s data budget is consumed purely by data integration and upfront data wrangling rather than actual analytics.Ā
Defining real-time ingestionĀ
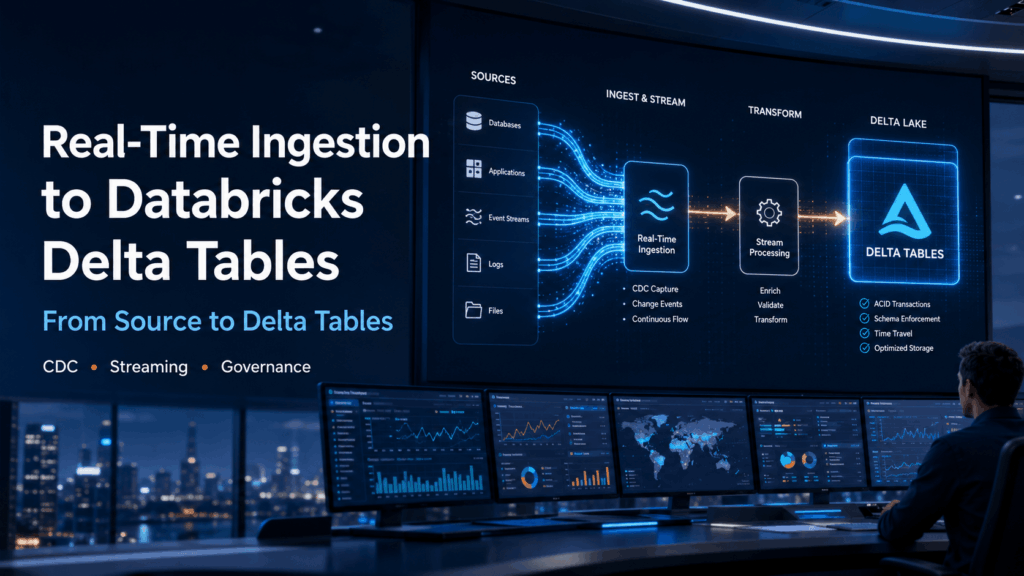
Real-time ingestion to Databricks represents the technical evolution from rigid scheduled batch processing to continuous, event-driven data streaming. At its core, the architecture involves capturing high-velocity data from sources, such as transactional databases via Change Data Capture (CDC), IoT sensors, or application log streams, and immediately driving it into Databricks Delta Tables.Ā
The friction points for modern businessĀ
Data teams migrating to continuousĀ lakehouseĀ replication face steep operational hurdles. Traditional ETL stacks rely on multiple disjointed tools to stitch together ingestion, storage, and processing, which creates brittle pipelines that are a nightmare to manage.Ā
The primary business pain points include:Ā
- The “Five-Tool Stack” Complexity: Constantly babysitting separate tools for CDC, stream ingestion, schema drift tracking, and orchestration.Ā
- Schema Drift and Failures: Quiet changes in source database schemas frequently break downstream pipelines, resulting in data downtime.Ā
- Prohibitive Cloud Compute Costs: PoorlyĀ optimisedĀ Apache Spark clusters running 24/7 to process streaming workloads can cause cloud bills to skyrocket out of control.Ā
Consider a fleet operations enterprise trying to build a live ETA pipeline. If sensor schemas mutate slightly, or if out-of-order data arrives during network drops, manual coding interventions are required, stalling operations.Ā
The IOblend Solution
IOblend redefines this architecture by standardising real-time production pipelines into a single, unified DataOps application built on Kappa architecture. Instead of managing a bloated stack, data experts use the low-code IOblend Designer to build pipelines that automatically generate highly optimised, pure Apache Spark code running behind the scenes.
IOblend directly solves enterprise challenges through:
Massive Performance: Achieving throughput speeds exceeding 1 million transactions per second (TPS) on modest infrastructure, slashing Databricks compute costs by up to seventy per cent.
Built-In Data Governance: Automating record-level lineage, data quality checks, de-duplication, and advanced Change Data Capture (log, trigger, or query-based) within every single flight.
No Vendor Lock-In: Pipelines are stored as portable JSON playbooks, keeping your core SQL and Python business logic independent.
Whether replicating over 400 MySQL tables via continuous CDC or syncing complex smart meter streams to Databricks, IOblend removes the coding burden entirely.
Accelerate your real-time Databricks pipelines from quarters to days with the power of IOblend.

Schema Drift: The Silent Killer of Data Pipelines
The Silent Pipeline Killer: Surviving Schema Drift in the WildĀ šĀ Did you know? In the early days of big data, a single column change in a source database could trigger a “data graveyard” effect, where downstream analytics remained broken for
Preventing Data Drift in Modern Data Systems
The Invisible Erosion: Detecting and Managing Data Drift in Modern ArchitecturesĀ šĀ Did you know? According to recent industry surveys, over 70% ofĀ organisationsĀ experience significant data drift within the first six months of deploying a production system.Ā The Concept of Data DriftĀ

Stream Database Changes to Your Lakehouse with CDC
Zero-Lag Operations: Stream Database Changes to Your LakehouseĀ š¾Ā Did you know? The “data downtime” caused by traditional batch processing costs the average enterprise approximately Ā£12,000 per minute.Ā The Concept: Moving at the Speed of ChangeĀ Zero-lag operations rely on a