Schema Evolution Without Chaos: Strong Data Contracts Enforced In Pipelines
📋 Did you know? In the early days of big data, a single altered column in a production database could trigger a catastrophic “data graveyard” effect.
The Concept of Schema Evolution
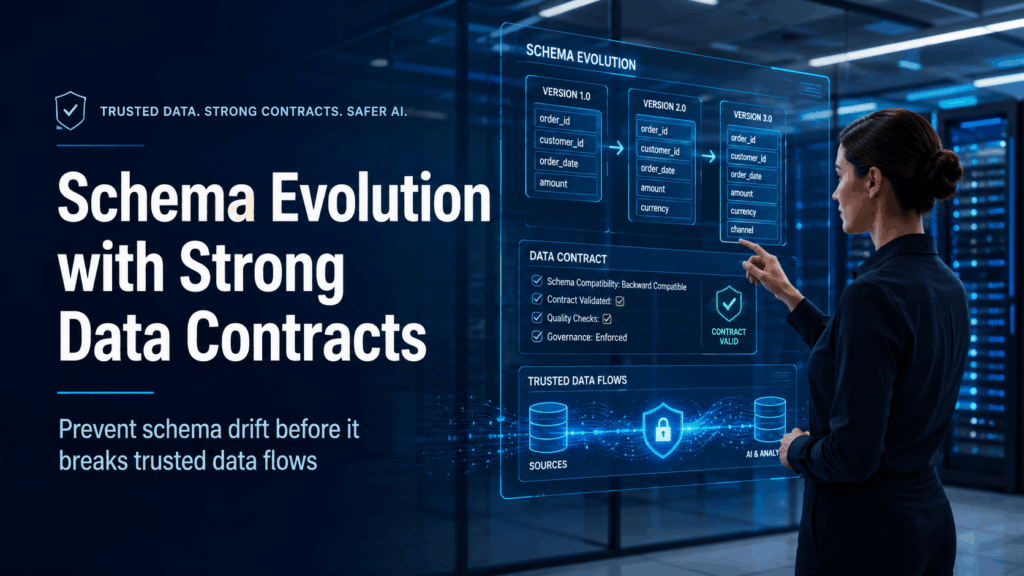
Schema evolution is the ability of a data platform to gracefully adapt to structural changes in incoming data, such as added, renamed, or dropped columns, without failing or corrupting existing datasets. In modern data lakehouses, this is achieved by moving away from rigid, hard-coded structures and adopting strong data contracts. These contracts act as explicit, enforceable agreements between data producers and consumers, ensuring that any structural evolution happens safely, predictably, and without manual pipeline intervention.
The Brittle Reality of Schema Drift
When organizations scale their data operations, they inevitably face schema drift. As upstream applications evolve, their underlying data models change. Without strict enforcement mechanisms, these changes ripple through to the data lake and such, causing severe operational pain:
- Broken Downstream Applications: A sudden alteration in a source database column type instantly breaks downstream machine learning models and business intelligence dashboards.
- The “Silent Failure” Dilemma: Pipelines often do not crash; they simply ingest malformed data, poisoning clean tables and rendering historical reports inaccurate.
- Engineering Bottlenecks: Data engineers spend more time writing defensive error-handling code and manually patching broken pipelines than building new data products.
Mastering Schema Evolution with IOblend
Managing schema evolution manually is a losing battle, but IOblend completely automates this operational challenge. Built with advanced DataOps capabilities, IOblend turns complex Apache Spark™ engine management into simple, metadata-driven pipelines that handle structure changes out of the box.
- Dynamic Schema Generation & Versioning: IOblend automatically generates schemas based on incoming data streams. It tracks and versions schema changes over time, maintaining full backward compatibility.
- Automatic Schema Validation: Every incoming batch or stream is checked against predefined contracts. If data deviates catastrophically, IOblend prevents ingestion, keeping your target tables clean.
- Automated Error Isolation: Rather than crashing the pipeline, invalid records are automatically channelled into a dedicated error table for isolation and automated debugging, while valid data continues to flow smoothly.
- Record-Level Lineage: If a drift event occurs, IOblend tracks exact record-level lineage and metadata, allowing engineers to instantly see what changed, what it impacted, and how to address it.
Eliminate data downtime and secure your data platform against schema drift.

IOblend JSON Playbooks: Keep Logic Portable, No Lock-In
The End of Vendor Lock-in: Keeping your logic portable with IOblend’s JSON-based playbooks and Python/SQL core 💾 Did you know? The average enterprise now uses over 350 different data sources, yet nearly 70% of data leaders feel “trapped” by their infrastructure.
Real-Time Defect Detection with Agentic AI + ETL
Smart Quality Control: Embedding Agentic AI into ETL pipelines to visually inspect and categorise production defects 🔩 Did you know? “visual drift” in manual quality control can lead to a 20% drop in defect detection accuracy over a single eight-hour shift The Concept:
Agentic AI ETL for Real-Time Sentiment Pricing
Sentiment-Driven Pricing: Using Agentic AI ETL to scrape social sentiment and adjust prices dynamically within the data flow 🤖 Did you know? A single viral tweet or a trending TikTok “dupe” video can alter the perceived value of a product by