The Silent Pipeline Killer: Surviving Schema Drift in the Wild
📊 Did you know? In the early days of big data, a single column change in a source database could trigger a “data graveyard” effect, where downstream analytics remained broken for weeks.
The silent pipeline killer
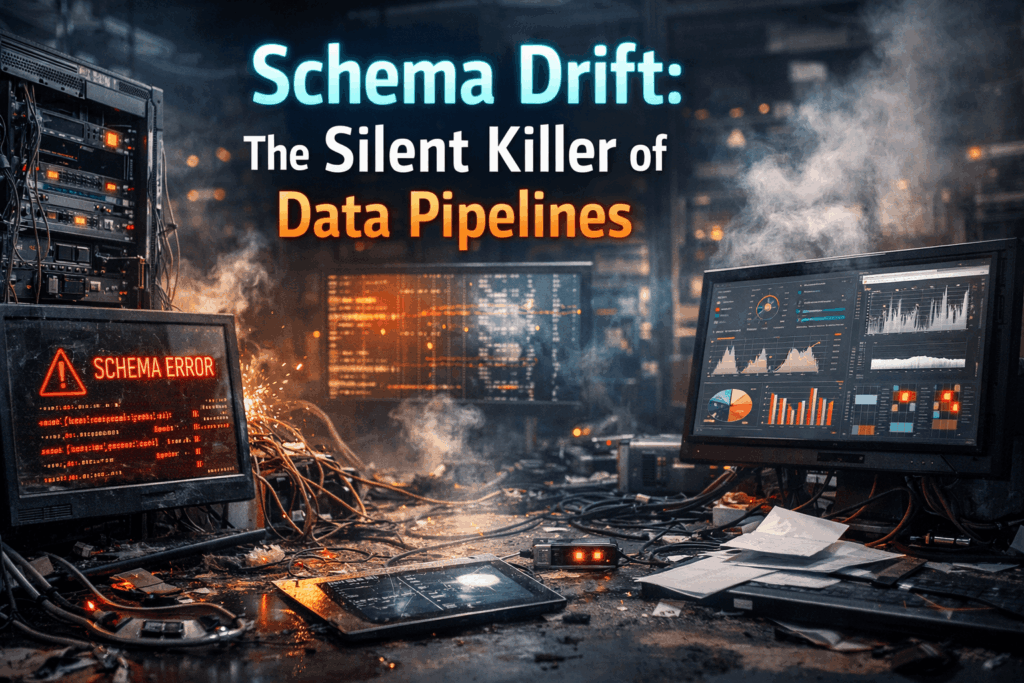
Schema drift occurs when the structure of source data changes unexpectedly. Imagine your upstream CRM team adds a “region” field, renames “customer_id” to “uid”, or changes a currency format from an integer to a string. To a human, these are minor tweaks; to a rigid data pipeline, they are fatal errors. Without a flexible architecture, these changes cause ingestion processes to crash, resulting in partial data loads or, worse, “silent failures” where corrupted data flows into your dashboards unnoticed.
The high cost of structural instability
For modern businesses, schema drift isn’t just a technical nuisance, it’s a commercial risk. When source systems evolve without warning, several critical issues emerge:
- Broken Downstream Analytics: If a field name changes, Every SQL join, BI dashboard, and ML model relying on that field instantly breaks.
- Engineering Toil: Data engineers spend up to 40% of their time on “break-fix” tasks. Manually updating ETL code every time a source API changes is a reactive, non-scalable way to work.
- Data Loss: In traditional rigid schemas, if an incoming record contains a new, undefined attribute, that data is often dropped entirely. This results in the loss of valuable business signals before they can even be analysed.
Navigating the wild with IOblend
IOblend provides a modern, “AI-forward” solution to the chaos of schema drift by moving away from brittle, hard-coded pipelines. Here is how the platform ensures you survive changing sources:
- Schema Evolution & Agility: IOblend is designed to handle structural changes dynamically. Instead of crashing, the platform can automatically detect new fields or data type changes, ensuring that your data flow remains consistent and reliable. AI agents can automatically analyse and act upon the changes based on your policies.
- Record-Level Lineage: Because IOblend tracks data at the record level, you can trace exactly when and where a schema change occurred. This provides full visibility into how your data has evolved over time, making audits and troubleshooting effortless.
- Real-Time Adaptability: Whether you are dealing with Spark-driven batch processing or real-time streaming, IOblend’s architecture abstracts the complexity of the underlying structure. This allows your team to focus on extracting value rather than rewriting ingestion logic.
- Unified Data Interface: By decoupling the source structure from the consumption layer, IOblend allows you to maintain a consistent “Golden Record” even as the “Wild” sources behind it continue to shift and change.
Ensure your pipelines are future-proof by making IOblend the backbone of your data engineering strategy.

Most Agent Failures Won’t Look Like AI Failures
Why enterprise AI agents can behave perfectly and still reach the wrong conclusion The agent gives a perfectly reasonable answer. The model behaved as expected. The prompt was fine. The tool call worked. And the result is still wrong. I
MCP, AI Agents and Live Enterprise Data
Enterprise AI is crossing an important boundary. Until recently, most enterprise AI systems were primarily asked to read information and produce an answer. They could summarise a contract, explain a report, find customer information or draft a response. Agentic AI
When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity.