AW-10865990051

Visual Debugging for Apache Spark Streams

Debugging-for-Apache-Spark-Streams-IOblend

Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration 

📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory, traditional breakpoints and step-through debugging are impossible without stopping the entire world, corrupting states, and causing downstream disaster. 

The Concept of Visual Tracing 

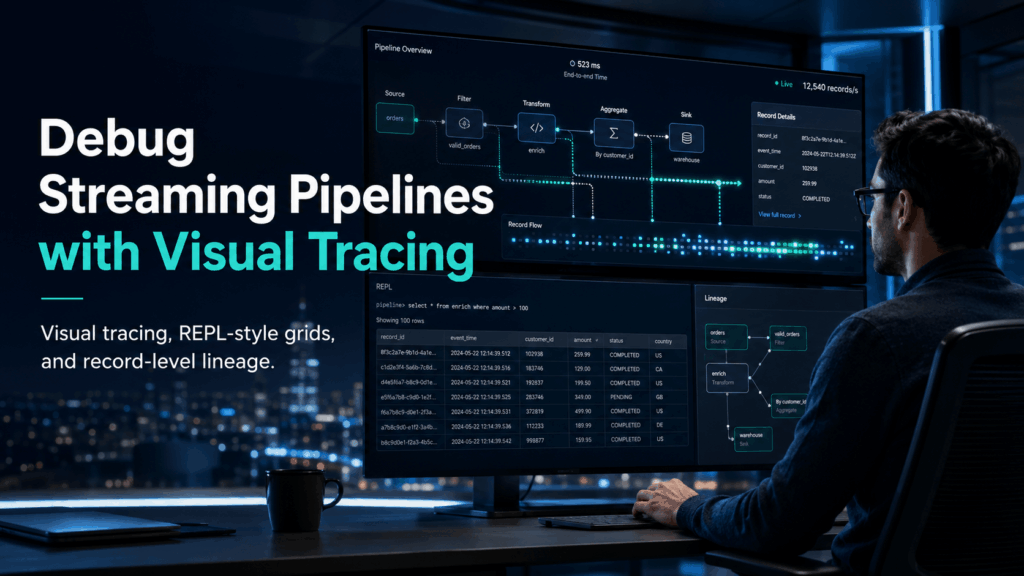
Streaming debugging is notoriously complex. Unlike batch processing, where you can pause, inspect, and rerun a static chunk of data, streaming flows constantly. Visual tracing changes this entirely. It acts like a high-speed camera for data-in-motion, allowing data experts to map out data flows and evaluate execution blocks in real time. Instead of looking at unformatted command-line error logs, engineers can see records moving through transformations interactively, mimicking Read-Eval-Print Loop (REPL) interactive grids. 

Streaming Bottlenecks for Modern Enterprises 

Building real-time data architectures, like Kappa or Lambda models, presents massive operational challenges for businesses: 

  • The Black Box Dilemma: When an aggregate metric spikes or a schema drifts, finding the exact corrupted record or broken joint downstream requires hours of parsing log files. 
  • Sluggish Iteration Cycles: Testing a minor business logic adjustment or custom Python snippet often requires full redeployment to a remote Apache Spark or Apache Flink cluster, dragging out development phases from days into weeks. 
  • Late-Arriving Records & Drift: Data arriving out of order or unexpected upstream structural modifications can silently break hand-written stateful transformations, resulting in inaccurate real-time dashboards and broken business trust. 

The IOblend Solution 

To overcome these production bottlenecks, IOblend shifts the entire streaming paradigm by embedding built-in DataOps directly into a low-code visual environment. Running on a highly optimised Kappa architecture, IOblend autogenerates distributed Apache Spark streaming jobs without requiring manual code. 

For data experts debugging complex streams, IOblend provides specific, production-ready capabilities: 

  • Visual Debugging & REPL Grids: Test real-time data flows locally via an interactive developer desktop application with REPL-like data grids, allowing you to iterate instantly before pushing pipelines live. 
  • Granular Record-Level Lineage: If an error occurs, IOblend tracks data changes down to the individual record, exposing exactly what modified the data. 
  • Automated Drift & Late Data Handling: It automatically tracks schema evolution, protects data contracts, and seamlessly replays transforms whenever late-arriving data hits the engine. 

Simplify your pipelines and scale with confidence by leveraging the real-time observability of IOblend. 

IOblend: See more. Do more. Deliver better.

IOblend_Salesforce_CDC_sync_Snowflake
AI

Real-Time Salesforce CDC to Snowflake

Real-Time CDC: Keep Salesforce and Snowflake in Perfect Sync 🔎 Did you know? While many businesses still rely on nightly batch windows to move CRM data, Salesforce generates millions of events every hour. The Concept: Real-Time CDC Real-Time Change Data
Read More »
Attachment Details IOblend_production_grade_data_pipelines_no_scala
AI

Build Production Spark Pipelines—No Scala Needed

Democratising Spark: How IOblend enables Data Analysts to build production-grade Spark pipelines without writing Scala or Java   Did You Know? The average enterprise now manages over 350 different data sources, yet nearly 70% of data leaders report feeling “trapped” by their own infrastructure. 
Read More »
IOblend-portable-JSON-SQL-and-Python
AI

IOblend vs Vendor Lock-In: Portable JSON + Python + SQL

The End of Vendor Lock-in: Keeping your logic portable with IOblend’s JSON-based playbooks and Python/SQL  💾 Did you know? The average enterprise now uses over 350 different data sources, yet nearly 70% of data leaders feel “trapped” by their infrastructure.

Read More »
Scroll to Top