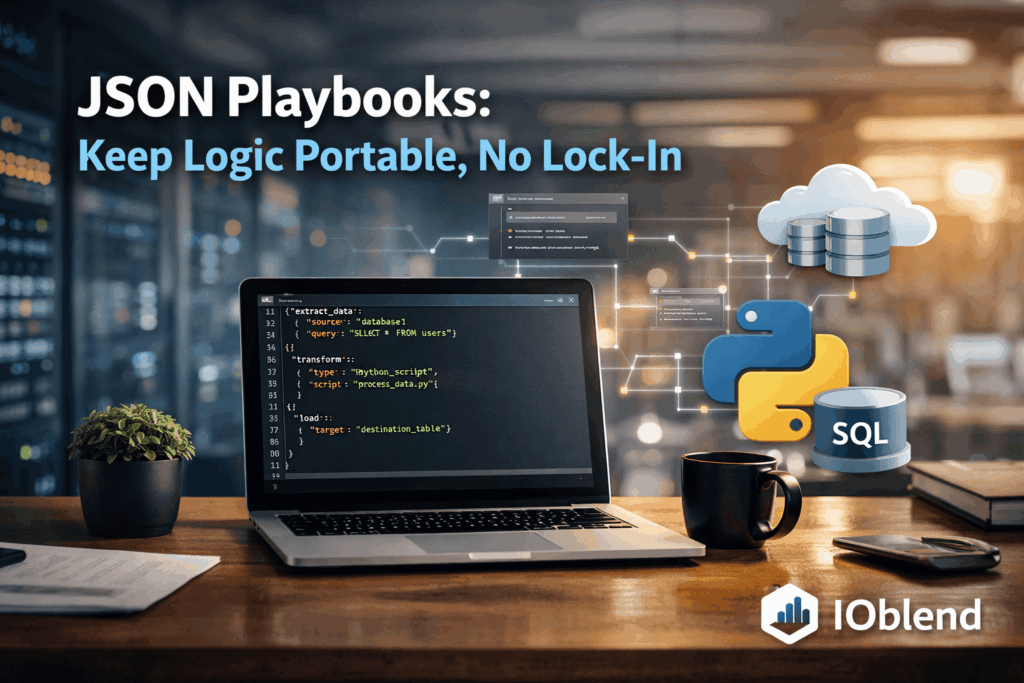
The End of Vendor Lock-in: Keeping your logic portable with IOblend’s JSON-based playbooks and Python/SQL core
💾 Did you know? The average enterprise now uses over 350 different data sources, yet nearly 70% of data leaders feel “trapped” by their infrastructure. Recent industry reports suggest that migrating a legacy data warehouse to a new provider can cost up to five times the original implementation price, primarily due to proprietary code conversion.
The Concept of Portable Logic
In the modern data stack, “vendor lock-in” is the invisible tether that binds your intellectual property, your business logic, to a specific service provider’s proprietary format. IOblend disrupts this cycle by decoupling the execution engine from the logic itself. By using a combination of universal SQL, standard Python, and JSON-based playbooks, IOblend ensures that your data pipelines remain platform-agnostic. Essentially, it treats your data integration as “living code” that can be moved, audited, and executed across different environments without a total rewrite.
The High Cost of Architectural Rigidity
For many organisations, the initial ease of “drag-and-drop” ETL tools eventually turns into a technical debt nightmare. When logic is stored in a vendor’s proprietary binary format or hidden behind a “black-box” GUI, the business loses its agility.
Data experts frequently encounter these friction points:
- The Migration Tax: Switching from one cloud provider to another often requires manual translation of thousands of stored procedures.
- Skill Gaps: Teams become specialists in a specific tool’s interface rather than the data itself, making it difficult to hire or pivot.
- Opaque Version Control: Proprietary tools often struggle with Git integration, making CI/CD pipelines fragile and difficult to peer-review.
The IOblend Solution: Portability by Design
IOblend solves these challenges by providing a developer-centric framework that prioritises transparency.
- JSON-Based Playbooks: Instead of opaque configurations, IOblend uses human-readable JSON playbooks to define pipeline stages. This means your entire workflow is documented in a standard format that can be version-controlled in Git and reviewed by any engineer.
- Python & SQL Core: By sticking to the industry-standard languages of data, SQL for transformations and Python for complex logic, IOblend ensures that your code remains your own. If you want to run a specific transformation elsewhere, the SQL block remains valid.
- Seamless Integration: IOblend’s approach allows you to build, run, and monitor pipelines at scale. By leveraging advanced metadata-driven automation, it eliminates the need for manual plumbing, allowing your team to focus on extracting value rather than managing infrastructure.
Future-proof your data strategy and break free from the shackles of legacy lock-in with IOblend.

BCBS 239 Compliance with Record-Level Lineage
Regulatory Compliance at Scale: Automating record-level lineage and audit trails for BCBS 239 📋 Did you know? In the wake of the 2008 financial crisis, the Basel Committee found that many global banks were unable to aggregate risk exposures accurately or
Real-Time Churn Agents with Closed-Loop MLOps
Churn Prevention: Building “closed-loop” MLOps systems that predict churn and trigger automated retention agents 🔗 Did you know? In the telecommunications and subscription-based sectors, a mere 5% increase in customer retention can lead to a staggering profit surge of more than 25%. Closed-Loop MLOps
Streaming Predictive MX: Drift-Aware Inference
Predictive Maintenance 2.0: Feeding real-time sensor drifts directly into inference models using streaming engine 🔩 Did you know? The cost of unplanned downtime for industrial manufacturers is estimated at nearly £400 billion annually. Predictive Maintenance 2.0: The Real-Time Evolution Predictive Maintenance