AW-10865990051

Real-Time Upserts: Deduping and Idempotency

Real-time-data-processing-with-deduplication

Streaming Upserts Done Right: Deduping and Idempotency at Scale 

💻 Did you know? In many high-velocity streaming environments, the “same” event can be sent or processed multiple times due to network retries or distributed system failures. 

The Art of the Upsert 

At its core, a streaming upsert (a portmanteau of “update” and “insert”) is the process of synchronising incoming data with an existing dataset in real time. If a record with a specific primary key already exists, it is updated; if not, it is created. 

To do this “right” at scale, two concepts are non-negotiable: 

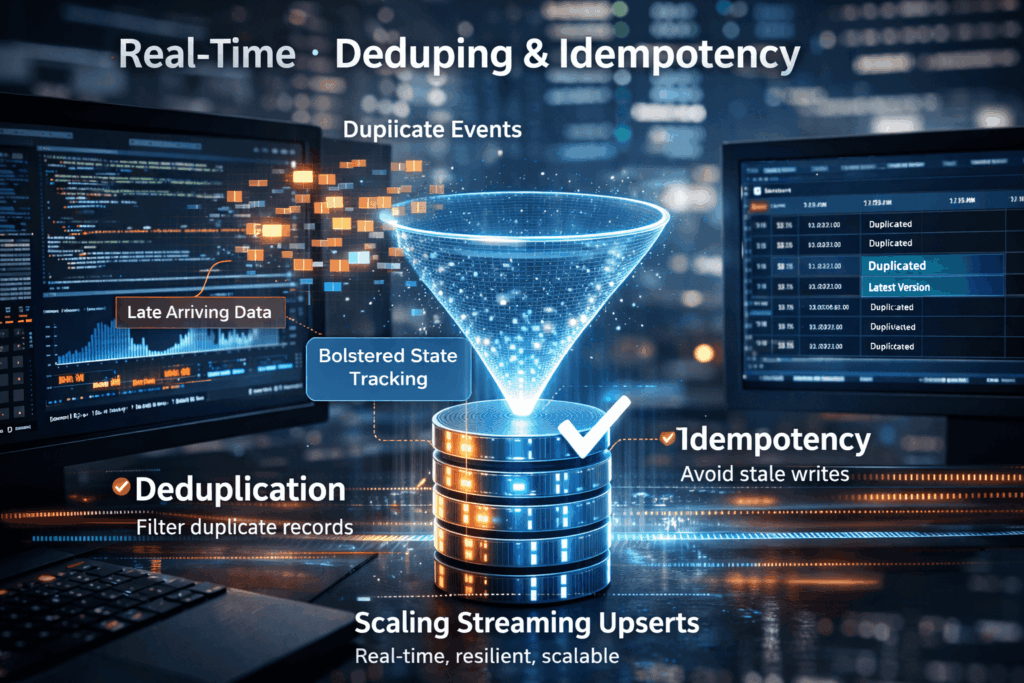
Deduplication: Removing identical redundant records before they hit the storage layer. 

Idempotency: Ensuring that performing an operation multiple times has the same effect as performing it once. 

The Scalability Wall: Why Businesses Struggle 

Most businesses start with simple batch updates, but as they move toward real-time insights, they hit a wall. In a distributed stream (like Kafka or Kinesis), data rarely arrives in the correct order. This leads to several critical issues: 

  • Late-Arriving Data: An older version of a customer’s profile might arrive after a newer version. If the system blindly upserts, it “downgrades” the data to an incorrect, stale state. 
  • The “Double Bubble” Problem: During system spikes or restarts, producers often resend batches. Without a robust state store to track what has already been processed, the downstream database suffers from bloated storage and inaccurate analytics. 
  • Performance Bottlenecks: Checking for the existence of a record in a multi-terabyte table before every single write is computationally expensive. Traditional databases often crawl to a halt under the high-IOPS (Input/Output Operations Per Second) demand of a true streaming upsert. 

Mastering the Stream with IOblend 

IOblend solves the complexity of streaming upserts by shifting the heavy lifting away from the database and into a high-performance, “AI-Forward” data engineering tier.  

Instead of writing complex, custom Spark or Flink scripts to manage state and watermarking, IOblend provides a unified interface to handle real-time data synchronisation. It natively manages: 

  • Automated Deduplication: Identifying and discarding redundant events at the ingestion point to save on downstream costs. 
  • Stateful Processing: Ensuring idempotency by keeping track of the latest version of every record, regardless of the order in which they arrive. 
  • Schema Evolution: Seamlessly handling changes in data structure without breaking the streaming pipeline. 

By using IOblend’s advanced CDC (Change Data Capture) and streaming capabilities, businesses can move from fragile, “bolt-on” deduplication to a resilient, enterprise-grade data mesh that guarantees accuracy at any scale. 

Don’t let duplicate data dilute your insights, streamline your future with IOblend. 

IOblend: See more. Do more. Deliver better.

Migration-QA-at-Scale-Reconciliation-Checksums-and-Audit-Trails
AI

Data Migration QA: Checksums & Audit Trails

Migration QA at Scale: Reconciliation, Checksums, and Audit Trails  📂 Did you know that during enterprise database migrations, as much as 20% of quiet data corruption goes entirely unnoticed until post-cutover operational failures occur?  Understanding migration QA at scale  Migration QA
Read More »
Lakehouse-Quality-Gates-Fail-Fast-Before-Bad-Data-Lands-IOblend
AI

Lakehouse Data Quality Gates: Stop Bad Data Fast

Lakehouse Quality Gates: Fail Fast Before Bad Data Lands  📋 Did You Know? Up to 20% of real-time event streams suffer from schema drift, duplicate payloads, or corrupted records, costing global organisations billions each year in wasted compute, broken analytical models, and polluted
Read More »
Data-contracts-with-IOblend
AI

Automated Data Contracts: Stop Schema Drift

Data Contracts That Stick: Enforce Schema and Expectations Automatically  📜 Did You Know? In the early days of big data, a single unannounced column type change in an upstream transactional database could trigger a catastrophic “data graveyard” effect, corrupting millions of

Read More »
Scroll to Top