Streaming Upserts Done Right: Deduping and Idempotency at Scale
💻 Did you know? In many high-velocity streaming environments, the “same” event can be sent or processed multiple times due to network retries or distributed system failures.
The Art of the Upsert
At its core, a streaming upsert (a portmanteau of “update” and “insert”) is the process of synchronising incoming data with an existing dataset in real time. If a record with a specific primary key already exists, it is updated; if not, it is created.
To do this “right” at scale, two concepts are non-negotiable:
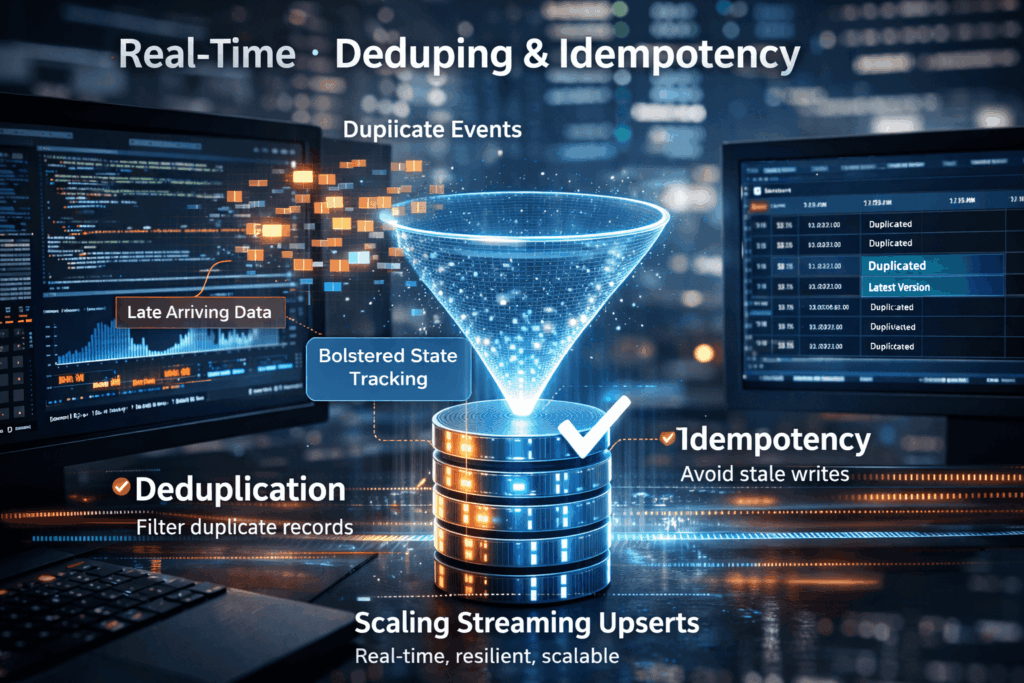
Deduplication: Removing identical redundant records before they hit the storage layer.
Idempotency: Ensuring that performing an operation multiple times has the same effect as performing it once.
The Scalability Wall: Why Businesses Struggle
Most businesses start with simple batch updates, but as they move toward real-time insights, they hit a wall. In a distributed stream (like Kafka or Kinesis), data rarely arrives in the correct order. This leads to several critical issues:
- Late-Arriving Data: An older version of a customer’s profile might arrive after a newer version. If the system blindly upserts, it “downgrades” the data to an incorrect, stale state.
- The “Double Bubble” Problem: During system spikes or restarts, producers often resend batches. Without a robust state store to track what has already been processed, the downstream database suffers from bloated storage and inaccurate analytics.
- Performance Bottlenecks: Checking for the existence of a record in a multi-terabyte table before every single write is computationally expensive. Traditional databases often crawl to a halt under the high-IOPS (Input/Output Operations Per Second) demand of a true streaming upsert.
Mastering the Stream with IOblend
IOblend solves the complexity of streaming upserts by shifting the heavy lifting away from the database and into a high-performance, “AI-Forward” data engineering tier.
Instead of writing complex, custom Spark or Flink scripts to manage state and watermarking, IOblend provides a unified interface to handle real-time data synchronisation. It natively manages:
- Automated Deduplication: Identifying and discarding redundant events at the ingestion point to save on downstream costs.
- Stateful Processing: Ensuring idempotency by keeping track of the latest version of every record, regardless of the order in which they arrive.
- Schema Evolution: Seamlessly handling changes in data structure without breaking the streaming pipeline.
By using IOblend’s advanced CDC (Change Data Capture) and streaming capabilities, businesses can move from fragile, “bolt-on” deduplication to a resilient, enterprise-grade data mesh that guarantees accuracy at any scale.
Don’t let duplicate data dilute your insights, streamline your future with IOblend.

When Enterprise Data Platforms Become Too Complex
When Enterprise Data Platforms Become Too Complex Enterprise data platforms usually start with a sensible goal: Connect the data Make it trustworthy Make it useful The problem is that, over time, the platform itself can become part of the complexity.
Real-Time Entity Resolution for Enterprise Data and AI
Entity Resolution at Scale: Merge Duplicates as Data Moves Enterprise data rarely arrives clean. The same customer, supplier or product can exist across multiple systems under different names, IDs or formats. For reporting, this creates inconsistency. For AI and automation,
Real-Time Customer 360: MDM for AI-Ready Data
Real-Time Customer 360: MDM That Keeps Data Current A Customer 360 view is only useful if the data behind it is current. Many organisations still rely on batch integration, which means customer profiles can quickly fall behind reality. As businesses