
AW-10865990051

Preventing Data Drift in Modern Data Systems

Drift-detection-in-data-systems-IOblend

The Invisible Erosion: Detecting and Managing Data Drift in Modern Architectures 

📊 Did you know? According to recent industry surveys, over 70% of organisations experience significant data drift within the first six months of deploying a production system. 

The Concept of Data Drift 

Data drift occurs when the statistical properties or the underlying structure of incoming data change over time. In a production pipeline, this isn’t necessarily a “bug” in the code; rather, it’s a shift in the reality the data represents. Imagine a retail pipeline where a “category” field suddenly receives new, undefined values because a supplier changed their system. The pipeline might continue to run, but your downstream analytics will now be missing crucial segments. Unlike a schema break, which crashes a job, drift is a sub-perceptual erosion of data quality that happens while your monitors are still showing “green”. 

Issues Faced by Modern Businesses 

For data-driven firms, undetected drift leads to “silent failures” that carry heavy costs.  

  • Decision Corruption: Executive dashboards might show a dip in performance that isn’t real, it’s just a change in how a source system labels “pending” versus “completed” transactions. 
  • Operational Friction: Automated supply chain triggers might fail to fire because the distribution of “stock levels” has shifted beyond the hard-coded thresholds set by engineers months ago. 
  • Resource Drain: Data teams often spend 80% of their time “firefighting”, manually tracing back data discrepancies to a source change that happened weeks prior. 

How IOblend Solves the Drift Dilemma 

Traditional tools treat drift as an afterthought, but IOblend embeds drift handling and technical governance into the very fabric of the pipeline. Built on a powerful Apache Spark™ engine and a Kappa architecture, IOblend provides a production-grade environment where data is managed throughout its entire journey. 

  • In-flight Quality Checks: IOblend applies data quality rules and statistical profiling in real-time. It doesn’t just move data; it validates it as it flows, catching anomalies before they land in your warehouse. 
  • Schema & Metadata Evolution: With built-in schema drift detection and automated metadata cataloguing, IOblend alerts you the moment a source structure changes, preventing downstream “data debt.” 
  • Record-Level Lineage: If drift is detected, IOblend’s automatic record-level lineage allows engineers to trace exactly where the deviation started, making debugging a matter of minutes rather than days. 
  • Agentic AI Integration: By embedding AI agents directly into the ETL stream, IOblend can intelligently validate and enrich data, identifying “visual drift” or conceptual shifts that traditional threshold-based monitors would miss. 

Stop flying blind and start trusting your data again with IOblend. 

IOblend: See more. Do more. Deliver better.

Deduplicate Streaming Events IOblend
AI
admin

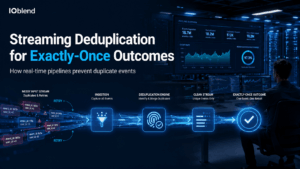
Streaming Deduplication for Exactly-Once Outcomes

Deduplicate Streaming Events: Exact-Once Outcomes in Real Life  📋 Did you know? In high-velocity streaming environments, network retries and transient worker failures cause up to 20% of event streams to contain duplicate payloads.  Understanding exact-once outcomes  In real-time data engineering, achieving “exactly-once” outcomes does not mean a message is transported across the wire only once, distributed
Read More »
Debugging-for-Apache-Spark-Streams-IOblend
AI
admin

Visual Debugging for Apache Spark Streams

Debug Streaming Like a Pro: Visual Tracing and Rapid Iteration  📎 Did you know? The vast majority of real-time streaming data pipeline bugs only reveal themselves under production workloads, usually at 03:00 am. Because streaming systems process unbounded data in memory, traditional breakpoints and step-through debugging are impossible without stopping the entire world, corrupting states, and
Read More »
Ship AI-Ready Data Products Faster IOblend
AI
admin

Ship AI-Ready Data Products Faster

Build a “Data Product” in Days: Reusable Pipeline Playbooks  📝 Did you know? According to industry research, over 75% of the enterprise data budget is swallowed by repetitive data integration tasks. Rather than delivering high-value analytical models, engineers spend the majority of their time building the same structural boilerplate over and over again.  What are reusable
Read More »
Schema-Evolution-Without-Chaos-Strong-Data-Contracts-Enforced-In-Pipelines
AI
admin

Schema Evolution with Strong Data Contracts

Schema Evolution Without Chaos: Strong Data Contracts Enforced In Pipelines  📋 Did you know? In the early days of big data, a single altered column in a production database could trigger a catastrophic “data graveyard” effect.  The Concept of Schema Evolution  Schema evolution is the ability of a data platform to gracefully adapt to structural changes
Read More »
Mainframe-to-Cloud-with-CDC-IOblend
Data analytics
admin

Mainframe to Cloud: Data Migration with CDC

Mainframe to Cloud: A Practical Data Migration Playbook  💾 Did you know? An alarming 83% of data migrations fail outright or drastically overrun their budgets.  Shifting Mainframe Heavyweights to the Cloud  Mainframe-to-cloud data migration is the process of moving core legacy data assets, often stored in rigid formats like DB2, VSAM, or IMS, into modern cloud
Read More »
Real-time-CDC-pipelines-into-Delta-tables-IOblend
AI
admin

Real-Time CDC to Databricks Delta Tables

Realtime Ingestion to Databricks: From Source to Delta Tables  💽 Did you know? According to industry surveys, nearly eighty per cent of an enterprise’s data budget is consumed purely by data integration and upfront data wrangling rather than actual analytics.  Defining real-time ingestion  Real-time ingestion to Databricks represents the technical evolution from rigid scheduled batch processing

Read More »
Scroll to Top